Repository navigation
test(serve): widen hosted recovery waitFor windows for CI contention (#14101) - #14107
Conversation


…14101)

Co-authored-by: Qwen-Coder <qwen-coder@alibabacloud.com>

Autofix E2E Report — Issue #14101SummaryMain-branch CI (
Root causeBoth tests poll session state with a bare This is the same contention class the house fixed the same day in #14084/#14091 ("the observed chain is a serial run of fsync-backed publishes and journal commits; 5s flaked on a loaded ubuntu-latest runner"), which widened a sibling hosted wait from 5 s to 10 s. FixGive both waits an explicit Reproduction notesThe flake did not reproduce locally: both tests pass in isolation (~0.1–0.2 s each), pass in the full 284-test describe block, and pass again with Verification
中文说明Autofix E2E 报告 — Issue #14101摘要主分支 CI(
根因两个测试都用不带参数的 这与当天 #14084/#14091 修复的争抢问题同属一类("the observed chain is a serial run of fsync-backed publishes and journal commits; 5s flaked on a loaded ubuntu-latest runner"),该修复把同类 hosted 等待从 5 秒放宽到 10 秒。 修复为两处等待显式加上 复现说明该偶发故障在本地未能复现:两个测试单独运行通过(各约 0.1–0.2 秒),在完整的 284 个测试的 describe 块中通过,并在 验证
🧠 Handled by Qwen Code · model/模型 |
 github-actions
Bot
added
the
review/self-reported


|
Thanks for the PR! Template looks good ✓ — every required section is filled in, and the Chinese half is a real translation rather than a stub. Problem: observed, not theoretical. #14101 is open and was auto-filed by the main-CI watcher; the run you cite (38410683888) is real — Direction: in scope. Keeping Size: not applicable. One file, Approach: the shape of the change is right, and I verified that instead of taking the description's word for it. The diff adds I also confirmed the fix isn't inert: the runner is The concern is the cause, not the change, and it's serious enough that I'm flagging it up front rather than burying it in the review: a maintainer posted a root-cause analysis on #14101 five minutes before this PR was opened concluding this is a product regression from Risk: no elevated risk signals. The high-risk-path check matched nothing, since the only changed file is a test file. Moving on to code review. 🔍 中文说明感谢贡献! 模板完整 ✓ —— 所有必填部分都已填写,中文部分也是真实翻译而非占位。 问题: 是已观测到的,不是理论性的。#14101 处于 open 状态,由 main CI 监视器自动创建;你引用的 run(38410683888)确实存在—— 方向: 在范围内。保持 规模: 不适用。单个文件 方案: 改动的形态是对的,这一点我做了核实而非采信描述。diff 给两处等待加了 我也确认了这个修复不是无效的:runner 是 我的顾虑在于成因而非改动本身,且分量足够重,所以我提前指出而不是埋在审查里:一位维护者在本 PR 开启前 5 分钟于 #14101 发布了根因分析,结论是这是 风险: 无升级风险信号。高风险路径检查未命中任何项,因为唯一改动的文件是测试文件。 进入代码审查 🔍 — Qwen Code · qwen3.8-max-2026-09-02 Reviewed at |
Code reviewMy independent proposal first (written from the title and "Why it's needed" only, before reading the diff): for "two hosted recovery tests fail on main CI against a 1 s default Steps (2) and (3) are what this PR does, and it does them well — I verified the assertion-preservation claim directly against the diff, and it holds: the callback bodies are byte-identical modulo Prettier re-indentation, and the only additions are the two Step (1) is the gap, and it's the whole review. The diagnosis is unresolved — this is the blocking questionThe PR asserts the failure is contention and "not a real defect". A maintainer ( I verified the load-bearing facts on both sides myself through the API rather than trusting either account: Supporting the regression reading:
Supporting the contention reading — and this is what the regression analysis on #14101 did not check: The two runs are on different hosts, and the failing one was far more loaded at the moment these tests executed. From each job's own
Roughly 2.7× the 5-min load. Under that, a 1 s window spanning fsync-backed journal commits plus a supertest round-trip per poll is genuinely marginal — and test 2 burned ~23 s per attempt of non-wait work, which is enormous for a unit test. So neither diagnosis is established. Both the code and the environment changed between the green and failing runs, which is a confound — the "passed before / failed after, test file unchanged" argument that #14101 rests on does not control for the runner, and the "it's just contention" argument here does not explain why the state never landed in any of three attempts. I can't resolve this from the diff, and I don't think anyone can without a controlled rerun. Why this blocks rather than merely interests me: if it is a regression, widening the window doesn't just fail to fix it — it risks converting a loud, deterministic, correctly-located failure into a slow or intermittent one. That is the specific outcome this repo's The good news is that this resolves itself cheaply, and the PR's own description is right that "the CI rerun on this PR is the meaningful gate":
I'd add one more cheap discriminator for whoever picks this up: the failure is only reproducible under load, so the useful experiment is to run these two tests against Testing evidenceUnattended CI run — per the review rules I did not build or execute any PR-derived code, so everything below is this PR's own CI read through the API, plus the historical run logs cited above. No check has landed red. Final CI results for
One row per check name (latest run); skipped checks omitted; failures sort first. / 每个检查名一行(取最新一次运行),省略 skipped,失败项排在最前。 On the sandboxed lanes: neither one can settle this claim, so I'm not recommending either. Real-scenario testing: N/A — unattended CI run, and a test-only timing change with nothing user-visible to drive. Not verified: whether the regression reading or the contention reading is correct. That is the open question this review defers on, and it needs a maintainer plus a load-controlled rerun, not more reading of this diff. 中文说明代码审查先说我自己的独立方案(只看标题和"为什么需要"、未读 diff 时写下):面对"两个 hosted recovery 测试在 main CI 上因 第 (2)(3) 步正是本 PR 所做的,而且做得好——我直接对照 diff 核实了"断言未变"这一说法,成立:回调体除 Prettier 重新缩进外逐字节相同,唯一新增是两处 第 (1) 步是缺口,也是本次审查的全部关键。 诊断悬而未决——这才是阻塞性问题本 PR 断言失败源于资源争抢且"不是真实缺陷"。一位维护者( 我没有采信任何一方的说法,而是通过 API 亲自核实了双方的关键事实: 支持"回归"读法的证据:
支持"资源争抢"读法的证据——而这正是 #14101 上那份回归分析没有检查的: 两次 run 在不同宿主上,且失败那次在这两个测试实际执行的时刻负载高得多。数据来自各 job 自身的
5 分钟负载约高 2.7 倍。在这种负载下,一个要跨越 fsync journal 提交、且每次轮询都含一次 supertest 往返的 1 秒窗口确实很勉强——而测试 2 每次尝试仅非等待部分就耗掉约 23 秒,对一个单元测试而言极其异常。 因此两种诊断都未被确立。 绿色 run 与失败 run 之间,代码和环境同时发生了变化,这是一个混淆变量——#14101 所依据的"改前通过 / 改后失败、测试文件未变"论证没有控制 runner 因素,而本 PR 的"只是资源争抢"论证也没能解释为何状态在三次尝试中一次都没到达。我无法从 diff 解决这一点,我认为没有受控重跑谁也解决不了。 为什么这构成阻塞而不只是值得关注:如果确为回归,放宽窗口不仅修不好它——还会有把一个响亮、确定性、定位准确的失败,变成缓慢或偶发失败的风险。而这正是本仓库 好消息是这个问题会以很低的成本自行揭晓,而且本 PR 描述里说得对——"本 PR 的 CI 重跑才是有意义的门禁":
我再补一个成本很低的判别方法给接手的人:该失败只在负载下可复现,因此有用的实验是在同一 runner 上、背靠背、负载可比的条件下,对 测试证据无人值守 CI 运行——按审查规则,我没有构建或执行任何源自本 PR 的代码,因此以下内容全部来自通过 API 读取的本 PR 自身 CI,以及上文引用的历史 run 日志。 没有任何 check 变红。 (CI 表格见上方英文区,中文侧不重复,以免重复输出机器可读标记。) 关于沙箱验证 lane: 两者都无法判定这一主张,所以我都不推荐。 真实场景测试:N/A —— 无人值守 CI 运行,且为仅测试的时序改动,无用户可见行为可驱动。 未验证:回归读法与资源争抢读法孰对孰错。这正是本次审查据以暂缓的未决问题,它需要维护者加上一次受控负载重跑,而不是对这个 diff 再读几遍。 — Qwen Code · qwen3.8-max-2026-09-02 Reviewed at |
|
Confidence: 3/5 — the change itself is clean and I'd merge it in isolation; what I can't clear is whether it fixes the actual cause, and a maintainer has already put a competing root-cause on record that this PR doesn't answer. Stepping back: this is a well-formed PR in search of a settled diagnosis. The craft is right — assertion-preserving to the byte, minimal, consistent with the file's own idiom and with #14091, and it correctly declines to sweep the other ~80 bare waits in the file. My independent proposal reached the same change. If the failure really is a 1 s window expiring under load, this is the correct fix and there is nothing more to say. But my proposal had a step this PR skipped, and it turned out to be the one that matters: establish the failure mode before widening the window. When I did that, the answer came back genuinely ambiguous rather than confirming the description. The same byte-identical test file passed on The reason I'm deferring rather than approving is the asymmetry, not the ambiguity. If it's contention, approving costs nothing and CI goes green. If it's a regression, approving quietly converts a loud, deterministic, correctly-located failure in hosted turn cleanup and journal recovery into a slower or intermittent one — and the regressing code ( Six months from now I'd thank the author for the tidy, well-commented change and curse whoever merged it without resolving #14101. So: not a rejection — the code is fine — but not mine to approve while the cause is open. What settles it, cheaply:
Not blocking, for whoever picks this up: ~80 bare 1 s waits remain in this file against 173 explicit ones. Fixing them two-at-a-time per CI failure will keep generating autofix PRs. Vitest has no global Deferring to @doudouOUC — you wrote the regression analysis on #14101, so this is your call to make, not mine: the load telemetry I pulled suggests the contention reading is more viable than "regression" alone implies, but I can't rule your reading out either, and only a load-controlled rerun separates them. Assigned so it lands in your filter. Needs a human call on this one. 中文说明Confidence: 3/5 —— 改动本身是干净的,单独看我愿意合并;我无法排除的是它是否修到了真正的成因,而一位维护者已在案卷上留下了相互竞争的根因分析,本 PR 并未回应。 退一步看:这是一个形态良好、但诊断尚未落定的 PR。工艺是对的——逐字节保留断言、改动最小、与文件自身惯例以及 #14091 一致,并且正确地没有去动文件里其余约 80 处裸等待。我的独立方案也得到同样的改动。如果失败确实是 1 秒窗口在负载下耗尽,那这就是正确的修复,无需再多说什么。 但我的方案里有一步是本 PR 跳过的,而它恰好是关键:在放宽窗口之前先确定失败形态。我补做这一步后,得到的结论是真正的两可,而非印证描述。同一个逐字节相同的测试文件在 我选择暂缓而非批准,理由是风险的不对称,而不是这份不确定性本身。若是资源争抢,批准毫无代价,CI 变绿。若是回归,批准就会把 hosted turn cleanup 与 journal recovery 中一个响亮、确定性、定位准确的失败,悄悄变成更慢或偶发的失败——而引入回归的代码( 半年后回看,我会感谢作者写出这个整洁、注释清楚的改动,但会咒骂那个在 #14101 未解决时就合并它的人。所以:这不是否决——代码没问题——但在成因未决之前,这个批准不该由我来给。 能低成本定论的做法:
给接手者的非阻塞建议:该文件仍有约 80 处裸 1 秒等待,对照 173 处显式等待。按"CI 失败一次修两处"的节奏推进,会持续产生 autofix PR。Vitest 没有全局 转交 @doudouOUC —— #14101 上的回归分析出自你手,因此这个判断该由你做,而不是我:我拉取的负载遥测表明,资源争抢这一读法比单看"回归"所暗示的更站得住脚,但我同样无法排除你的读法,只有受控负载重跑才能分开二者。已 assign,以便进入你的待办过滤。这一处需要人来拍板。 — Qwen Code · qwen3.8-max-2026-09-02 Reviewed at |

🩺 serve daemon A/BBuilt the PR base vs this PR head
|
| field | PR base (before) | this PR (after) |
|---|---|---|
activeWorkStaleMs |
5 |
4 |
— Qwen Code · serve A/B
|
🤖 Reviewed the latest feedback — no changes needed. Why, point by point: · 已审阅最新反馈——无需改动。逐点说明原因如下: Autofix Address-Review — PR #14107 (issue #14101)Outcome: no change this round. Every actionable item in this round's feedback was triaged to a disposition that requires no code edit; the reasoning and evidence for each is below. Feedback dispositions1. Issue comment
|

|
已评审
另有一项需要纠正的 CI 信息:当前 Hosted process fault gates / MySQL 8.4 / Java 21 的失败日志明确显示 验证范围:完整差异、相关测试上下文、超时配置、历史评审及当前提交的 CI 原始日志; |

|
🤖 Reviewed the latest feedback — no changes needed. Why, point by point: · 已审阅最新反馈——无需改动。逐点说明原因如下: Autofix round — no changeNo code change this round. The only new feedback is maintainer @wenshao's review of Disposition of each feedback point
VerificationNo local checks were run because this round makes no change to the working tree. The maintainer's review already verified the current head against the live CI: Linux unit tests 459/459 pass for the touched file, Lint & Static passed, and 中文说明Autofix 本轮——无需改动本轮不进行任何代码修改。唯一的新反馈是维护者 @wenshao 对 各反馈点的处理结论
验证本轮未改动工作树,因此未在本地运行任何检查。维护者的评审已基于实时 CI 对当前 head 完成验证:涉及文件的 Linux 单元测试 459/459 通过,Lint & Static 通过, Base-conflict check · 基分支冲突检查: no conflict with main. · 与 main 无冲突。 🧠 Handled by Qwen Code · model/模型 |

Verification report — PR #14107Verdict: merge-ready — 0 unexpected failures across 45 scripted assertions (fault-injection A/B ×2, 48-run timing matrix, gates, static census/equivalence). Verified head: 中文摘要
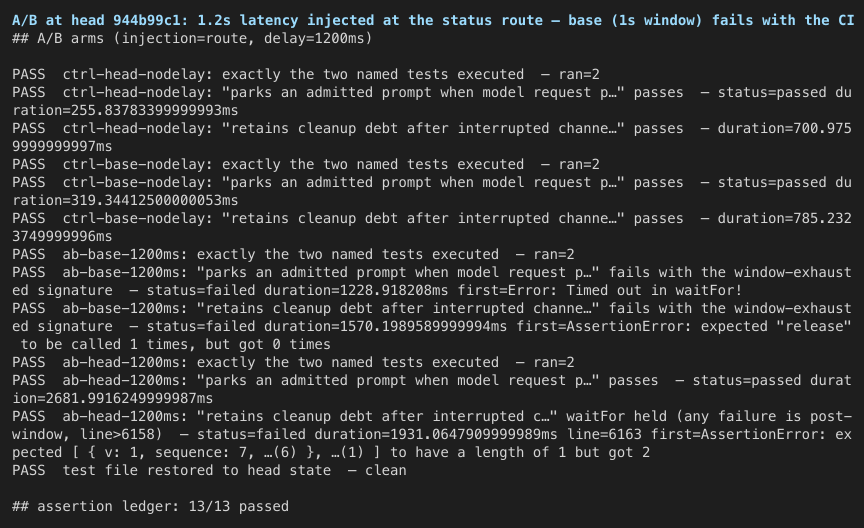
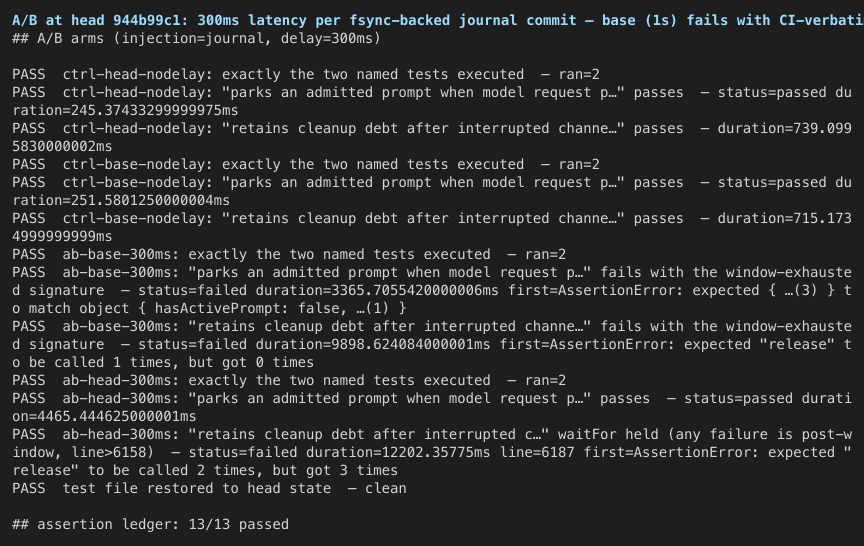
Central claim and A/B proofThe PR exists to change exactly one behavior: the polling window of two A/B method. Both arms run in the head worktree; the test file is swapped between the base blob and the head blob (the only in-diff change), and latency is injected at two independent points:
Numbers below are the new-head (
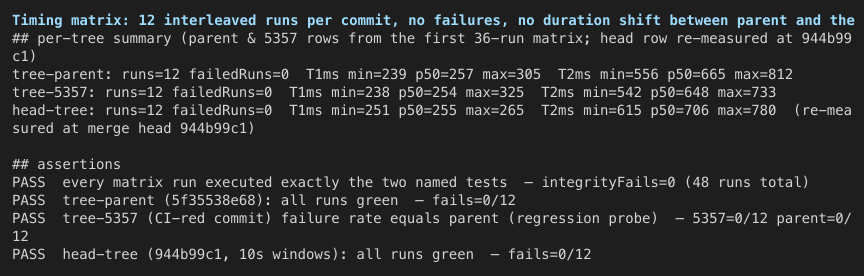
(a) CI signature match. CI job 115369140703 (run 38410683888) failed T1 with (b) T2's head arms. Under both injections T2's widened Each arm also asserts that exactly the two named tests executed (2/2, never 0 or 458) and that the test file is restored byte-clean afterwards ( The contested question: contention or regression?The stage-3 review deferred on a genuinely open question — @doudouOUC's regression reading of 1. CI's own record (census, no re-run needed). 2. Local controlled experiment (the one the review asked for). The two named tests, 12 interleaved runs each on
No failure anywhere, and no duration shift between the parent and the suspect commit (Δp50 ≈ −3 ms on T1, −17 ms on T2 — inside run-to-run spread). Reviewer test plan, walked
Static verification of the diff shape
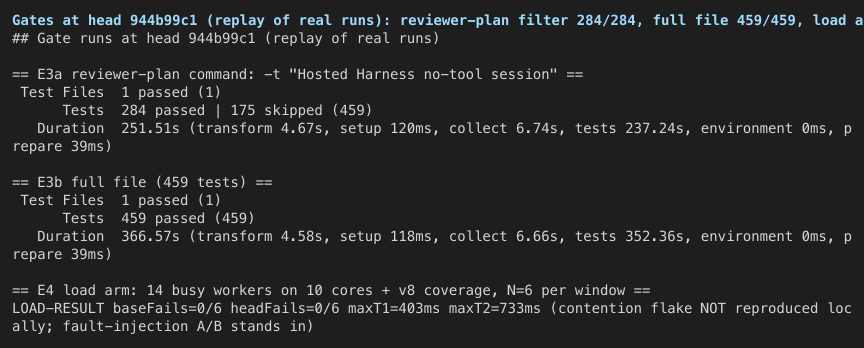
Gates
Corrections
FindingsNone blocking. One observation, not for this PR:
Not covered
MethodologyLocal maintainer-driven round on macOS (10-core arm64, 16 GB), Node v22. Three git worktrees at head / parent ( Evidence captures
— verification run by @wenshao (local maintainer round; harnesses, per-arm JSON reports and raw logs preserved under |
|
🔀 Base updated: red check(s) [Test (ubuntu-latest, Node 22.x)] pass on current main — merged current main via update-branch; CI will re-run. 中文说明🔀 已更新 base:红色检查 [Test (ubuntu-latest, Node 22.x)] 在当前 main 上通过 —— 已通过 update-branch 合入当前 main,CI 将重新运行。 |

 yiliang114
left a comment
yiliang114
left a comment
There was a problem hiding this comment.
Approving. The change is exactly what it claims: two vi.waitFor windows in hosted-harness-session.test.ts raised to an explicit 10_000, with the callback bodies and every assertion preserved — the diff is the two option objects plus two comments. That is the deflake policy's allowed fix #1 and matches the file's own dominant explicit window (10_000), so it's the right shape and the right scope.
The open question from triage — 1s-window flake vs. a product regression — resolves on this head. The PR's own Test (ubuntu-latest, Node 22.x) lane is green: Qwen Code CI run 38494457195 succeeded at head 0f3c53cd. So the state does land, just slowly, which is consistent with runner contention. Worth noting the widened window can't hide a "state never arrives" defect either: if the transition genuinely didn't happen, the unchanged expects still fail at 10s. It only tolerates slowness.
The two Java checks that show red on this head are not attributable here. Hosted process fault gates / MySQL 8.4 / Java 21 is red on main at this PR's own base 1f39a80b too (sdk-java run 38493191034), failing the same way — RuntimeBroker Workspace execution authority is unavailable across HostedPublicWorkspaceIT / HostedTeamLeadMySqlIT / HostedProcessCrashIT — and Real daemon E2E / Java 11 is a superseded cancelled job. There's no path from a TS test-only diff to those, so I'm reading them as pre-existing Java-lane state, not this PR.
Non-blocking follow-ups (not merge blockers):
- The PR body says the failure produced
Timed out in waitFor!; that string is absent from the failing log. The real signature is anAssertionErrorraised inside the waitFor callback (the last poll error rethrown when the 1s window expires). Same conclusion, but worth correcting if you touch the body. - ~80 bare
vi.waitForcalls remain in this file against 173 that carry an explicit window. A file-local helper wrappingvi.waitForwith the house10_000would stop these one-flake-at-a-time PRs; explicitly out of scope here, just flagging the follow-up.


|
Released in v0.25.2. |

`gives a read-profile Session no skill catalog from its agent definition`
polls `hasActivePrompt` through a bare `vi.waitFor`, so it inherits vitest's
1s default. On a contended ECS runner (load ~74, 52 concurrent test processes)
that second is not reachable: the poll crosses a settle path that commits a
journal entry before the active flag clears, and the case failed 3/3 attempts
inside one run at the same assertion.

Every other hosted wait in this file already carries an explicit budget — this
one was in the bare minority that `@testing-library`'s `asyncUtilTimeout`
cannot cover, because `vi.waitFor` has no equivalent global bump.

Same shape as QwenLM#14091, QwenLM#14107, QwenLM#14394 and QwenLM#13323. Nothing is asserted less: a
condition that never holds still fails, it just gets ten seconds to hold.


What this PR does
Widens the state-polling windows in two Hosted Harness no-tool session tests from vitest's implicit 1000 ms
vi.waitFordefault to an explicit 10 s, with a comment on each naming the issue and the mechanism. No assertions were added, removed, or weakened, and no production code changed.Why it's needed
Main-branch CI failed on these two tests in run 38410683888 (
Test (ubuntu-latest, Node 22.x)). Both tests wait for recovery state that settles across fsync-backed journal commits — parking an admitted prompt after a model-request-preparation failure, and settling an interrupted channel turn while retaining cleanup debt — with a supertest HTTP round-trip per poll. Vitest's defaultwaitForwindow is only 1 s, which a loaded shared runner running the main-branch coverage-instrumented job can exhaust before the state lands, producing aTimed out in waitFor!flake rather than a real defect. This is the same contention class fixed the same day in #14084/#14091, which widened a sibling hosted wait from 5 s to 10 s for the same reason; this change brings the two remaining bare waits in line with that precedent and with the other waits in the same file that already use explicit 10 s windows.Reviewer Test Plan
How to verify
Confirm the diff touches only the two failing tests'
vi.waitForcalls and only adds{ timeout: 10_000 }plus a comment — every assertion is unchanged. Then run the tests:cd packages/cli && npx vitest run src/serve/hosted-harness-session.test.ts -t "Hosted Harness no-tool session"should pass all 284 tests, and the two named tests (parks an admitted prompt when model request preparation fails,retains cleanup debt after interrupted channel settlement until original-owner release succeeds) pass individually. Expected: green before and after locally — the flake is contention-dependent and did not reproduce on an unloaded machine, even withCI=true QWEN_CI_COVERAGE=1; the fix removes the narrow window instead of changing observable behavior. The CI rerun on this PR is the meaningful gate.Evidence (Before & After)
N/A — test-only timing change, no user-visible behavior.
Tested on
Environment (optional)
N/A — unit tests only (
npm run build,npm run typecheck,npm run lint, and focused Vitest runs all pass).Risk & Scope
vi.waitForcalls in the file were left as-is; only the two tests observed failing in CI were widened, keeping the change minimal. CI, Docker, and platform-specific behavior beyond the Linux unit-test job is out of scope.Linked Issues
Fixes #14101
中文说明
本 PR 做了什么
将两个 Hosted Harness no-tool session 测试中的状态轮询窗口,从 vitest 默认的隐式 1000 毫秒
vi.waitFor超时放宽为显式的 10 秒,并在每处添加注释注明对应 issue 和机制。未新增、删除或削弱任何断言,也未改动任何生产代码。为什么需要
主分支 CI 在 run 38410683888(
Test (ubuntu-latest, Node 22.x))中这两个测试失败。两个测试等待的恢复状态需要跨越基于 fsync 的 journal 提交才能就绪——模型请求准备失败后挂起已准入的 prompt,以及在保留清理债务的同时结算被中断的 channel turn——且每次轮询都包含一次 supertest HTTP 往返。vitest 的waitFor默认窗口只有 1 秒,在负载较高、且运行主分支覆盖率插桩任务的共享 runner 上,状态可能还未就绪窗口就已耗尽,从而产生Timed out in waitFor!的偶发失败,而非真实缺陷。这与当天 #14084/#14091 修复的问题同属一类,该修复出于同样原因把同类 hosted 等待从 5 秒放宽到 10 秒;本改动让文件中仅剩的两处裸等待与该先例以及同文件中其他已使用显式 10 秒窗口的等待保持一致。评审者测试计划
如何验证
确认 diff 只触及两个失败测试的
vi.waitFor调用,且仅添加了{ timeout: 10_000 }和注释——所有断言均未改动。然后运行测试:cd packages/cli && npx vitest run src/serve/hosted-harness-session.test.ts -t "Hosted Harness no-tool session"应通过全部 284 个测试,且两个具名测试(parks an admitted prompt when model request preparation fails、retains cleanup debt after interrupted channel settlement until original-owner release succeeds)单独运行也通过。预期:本地在修复前后均为绿色——该偶发故障依赖负载争抢,即使在CI=true QWEN_CI_COVERAGE=1下也无法在空载机器上复现;本修复收窄的是超时窗口本身,不改变可观察行为。本 PR 的 CI 重跑才是有意义的门禁。前后对比证据
N/A —— 仅测试超时时长改动,无用户可见行为。
测试平台
环境(可选)
N/A —— 仅单元测试(
npm run build、npm run typecheck、npm run lint及相关 Vitest 运行均已通过)。风险与范围
vi.waitFor调用保持不变;只放宽了 CI 中实际观测到失败的两个测试,以保持改动最小。Linux 单元测试任务之外的 CI、Docker 和平台特定行为超出范围。关联 Issue
Fixes #14101