Repository navigation
fix(memory): report omitted index entries at write time - #14937
Conversation


|
Verified source commit 0ff2926, 22 October review follow-up. Current PR head is 5f93cd5, a normal merge of main 8a9ae63 required by the upstream freshness gate. All ten PR blobs and the audited net diff are identical. On current 5f93cd5, upstream lint/static, no-AK integration (276 tests), TUI parity and no-flicker passed. The Linux job passed CLI (44,058; 101 skipped), core (38,220 passed, including all 32 diagnostic regressions; 22 skipped) and web-shell unit tests (12,810); their uploaded JUnit reports contain no failures/errors. The job remains red: standalone provisioning received HTTP 502 from npm for Bun 1.3.14 before executing the standalone regression; subsequent script tests did not run. That provisioning script is byte-identical on exact base 8a9ae63 and observed main 7091697. The exact-base run completed its Node/Bun standalone probes and later failed a different no-AK wiring assertion—not this download failure or a fully green baseline. I changed no code, thresholds or retries for this. The Linux job needs a maintainer-side rerun. Current browser smoke finished with 352 passed and one failed: on all three attempts the menu disappears after hovering Edit message and waiting 180 ms, at line 929. The focused exact-base/head/observed-main comparison is now complete: the original case passed on attempt 0 on base 8a9ae63, head 5f93cd5 and observed main 952c6de, with no global/test errors. Configured worker limit was 2; actual workers were 1 per arm. Assertions, retries and timeouts were unchanged. The failure was not reproduced in this isolated current-base comparison. The same unchanged head failed three full-smoke attempts but passed this isolated execution; no source fix or root cause is established, and the full 353-case concurrency/order/load was not recreated. The original upstream gate remains red; automated review is still pending. The author-suite receipts below remain pinned to 0ff2926. I reproduced the five behavior findings on exact d115d1e before changing source: transient index-only edits, wrong writer remedies, differing arbitrary-root diagnosis, false separator-only truncation, and reader length advice under a pure count limit. The fixed source was separately checked against those witnesses and unchanged-behavior controls. Fresh isolated Windows source-runtime verification passed 14 grouped records, including 24 separator/line-ending variants, all scoped/arbitrary-root modes and relocated project storage. Retained bodies/order and 205-topic content/mtime manifests matched the baseline; four large-notice/grouping fixtures stayed at or below 888/1024 units. The same 14 grouped witnesses passed again independently on merged head 5f93cd5, from a freshly generated 152-input source bundle whose digest matches 0ff2926. This is new-base source sanity, not binary E2E or a completed new-base CI claim. This is an actual-source fallback, not interactive CLI/TUI/ACP/model or Dream lifecycle E2E. On validated source commit 0ff2926, before the main merge, Linux/Node 22: root build/bundle, repository typecheck, formatting of all ten PR files, lint of the seven TypeScript files, the full memory suite (1,136 passed, one existing macOS-only skip; all 32 diagnostic regressions passed), built CLI version/help, startup bundle closure and the restored tracked-tree check passed. My first October 22 attempt remains red: my fork-only harness did not recognize Vitest's serialized Historical results remain historical: d115 author aggregate preflight exited 1 at missing fork-workflow size metadata, while exact-d115 upstream workspaces/scripts/startup closure passed. The d115 upstream browser smoke was 348 passed/3 failed; base/head/observed-main comparison reproduces both symptoms outside the memory change, with intermittent hover outcomes. I did not alter those assertions, retries, timeouts or browser code. Neither comparison was converted into an all-green result, and neither substitutes for current-head upstream CI/review. No provider credentials, stale source bundle or real user memory were used. Windows source-runtime and Linux remote checks only; macOS not tested. Limits, retained entry bodies/order, link targets, trust rules, all topic files and headless lifecycle remain unchanged. |


|
Qwen Code review never started. The job ended before a runner picked it up, so no review ran for this head. This can happen when a queued run is cancelled or expires; this step cannot determine the cause. See workflow logs. Check the latest |

 doudouOUC
left a comment
doudouOUC
left a comment
There was a problem hiding this comment.
EN
Thanks — the split between scan-cap omissions and index-budget omissions is the right shape, and I confirmed the important invariants hold: the written body is byte-identical to before (the notice is appended after trimIndexToBudgetDetailed(...).content, and trimIndexToBudget is the same function), the retained set for project/user/team is the same 200 documents as the replaced scan wrappers, every reported name really is absent from the index body while surviving lines are never named, and both the count and the name sample are bounded (3 names × 60 units per set, paragraph ≈ 850 units, well inside the reader's 1024-unit exemption).
One accuracy problem in the new scan-cap-only path. When only the 200-file scan cap trips and the entry body is well inside both index limits, reasons is empty and the notice is still built from the size-pressure opening plus the entry-budget lever (packages/core/src/memory/indexer.ts:236-262): > WARNING: MEMORY.md is too large; only part of it was written. Dropped 5 of 205 topic files: … Scan limit: 200 files. Prune or merge entries to reduce the index. In that state MEMORY.md is not too large (200 entries, ~9,000 units of 25,000), and pruning or merging index entries cannot clear a file-count cap — the same 205 files are rescanned next rebuild, so following that lever only shrinks the catalog further. Since the diagnostics are the whole point of this fix, please derive the opening sentence and the lever from whichever limit actually tripped (reasons.length === 0 && scanOmitted > 0 ⇒ say the index does not list every topic file, and suggest merging or removing topic files). The tests at index-drop-notice.test.ts:80-92 and :200-251 cover this state but only assert the name lists and Scan limit:, so the cause sentence and lever are currently unverified.
Smaller points, no action required if you disagree:
packages/core/src/memory/prompt.ts:189-191still measureshasOverlongEntryover every line, including lines the 200-line cap already excludes; a long entry at position 250 makes the reader's lever say "keep entries to 150 units" when shortening it cannot help. Your last commit fixed exactly this on the writer side (indexer.ts:240-244scopes it tocandidates); a matchingentries.slice(0, MAX_MANAGED_AUTO_MEMORY_INDEX_LINES)would keep the two halves consistent, and the existing guard atindex-drop-notice.test.ts:107-118covers only the writer.packages/core/src/memory/index-budget.ts:11-15:INDEX_TRUNCATION_NOTICE_STARTandINDEX_TRUNCATION_WARNINGduplicate the same sentence, and the reader recognizes the notice by exact prefix (prompt.ts:167). A future wording change on one literal only would make the writer emit a notice the reader no longer exempts, at which point the paragraph is budgeted as an entry and can be reported back as a dropped entry. Deriving one from the other removes that trap; the two legacy constants otherwise now have no production reader.packages/core/src/memory/indexer.ts:265-274formats a fulldocIndexLinefor every omitted document just to keep three names, which is O(omitted) sanitize work on each managed-write rebuild for a store far past the cap; only the first three need formatting.packages/core/src/memory/indexer.ts:258-261sums dropped index lines with omitted topic files. For the team scope,groupTeamDocsByDescriptioncan make one dropped line stand for several files, so the "in total" number is neither unit in that case; wording the two counts separately, or only emitting the total when entries are ungrouped, avoids the ambiguity.
中文
感谢这个改动——把扫描上限遗漏和索引预算遗漏分开报告方向是对的。我确认了几个关键不变量成立:写入正文与改动前逐字节一致(警告是在 trimIndexToBudgetDetailed(...).content 之后追加的,而 trimIndexToBudget 就是同一个函数);project/user/team 保留的仍然是同一批 200 个文档,与被替换的扫描包装函数一致;被报告的名称确实都不在索引正文里,而保留的条目从未被误报;数量与名称样本都受限(每组 3 个名称 × 60 单元,整段约 850 单元,远小于读取侧 1024 单元的豁免上限)。
新的「仅扫描上限」路径存在一处准确性问题。当只有 200 文件扫描上限触发、条目正文远未触及两条索引上限时,reasons 为空,但警告仍由「体积过大」开头加条目预算建议拼成(packages/core/src/memory/indexer.ts:236-262):> WARNING: MEMORY.md is too large; only part of it was written. Dropped 5 of 205 topic files: … Scan limit: 200 files. Prune or merge entries to reduce the index. 此时 MEMORY.md 并不大(200 条目、约 9,000 / 25,000 单元),而「prune or merge entries」也无法解决文件数量上限——下次重建仍会扫描同样的 205 个文件,照此操作只会让目录进一步缩水。既然诊断文本就是本次修复的全部内容,建议根据实际触发的上限选择开头句子和 lever(reasons.length === 0 && scanOmitted > 0 时改为「索引未列出全部主题文件」,并建议合并或删除主题文件)。index-drop-notice.test.ts:80-92 与 :200-251 覆盖了这个状态,但只断言了名称列表和 Scan limit:,开头句子与 lever 目前没有测试保护。
以下为较小的问题,若不认同可忽略:
packages/core/src/memory/prompt.ts:189-191的hasOverlongEntry仍然对全部行做判断,包括已被 200 行上限排除的行;位于第 250 位的超长条目会让读取侧建议「把条目压到 150 单元」,而缩短它并不能解决问题。你最后一个提交恰好修正了写入侧的同类误判(indexer.ts:240-244只看candidates),读取侧补一个entries.slice(0, MAX_MANAGED_AUTO_MEMORY_INDEX_LINES)即可对齐;现有保护测试index-drop-notice.test.ts:107-118只覆盖写入侧。packages/core/src/memory/index-budget.ts:11-15:INDEX_TRUNCATION_NOTICE_START与INDEX_TRUNCATION_WARNING重复了同一句话,而读取侧按精确前缀识别该警告(prompt.ts:167)。将来只改其中一处,写入侧就会生成读取侧不再豁免的警告,那段文字会被当作条目参与预算,甚至被回报成「被丢弃的条目」。让一个从另一个派生即可消除该隐患;另外这两个旧常量目前已没有生产代码读取。packages/core/src/memory/indexer.ts:265-274为了保留 3 个名称,对每个被遗漏文档都完整格式化了一次docIndexLine;对于远超上限的存储,这会在每次托管写入重建时产生 O(omitted) 的净化开销,而实际只需要前三个。packages/core/src/memory/indexer.ts:258-261把被丢弃的索引行与被遗漏的主题文件相加。在 team 作用域下groupTeamDocsByDescription可能让一个被丢弃的行对应多个文件,此时「in total」的数字既不是行数也不是文件数;分开表述两个数量,或仅在未分组时输出合计,可以避免歧义。
|
I kept the earlier review corrections and addressed the 22 October review in 0ff2926. Current PR head is 5f93cd5, after a normal merge of main 8a9ae63 required by lint-gate change 0ac1fcc. All ten PR blobs and the audited net diff are identical. On current 5f93cd5, upstream lint/static, no-AK integration (276 tests), TUI parity and no-flicker passed. The Linux job passed CLI (44,058; 101 skipped), core (38,220 passed, including all 32 diagnostic regressions; 22 skipped) and web-shell unit tests (12,810); their uploaded JUnit reports contain no failures/errors. The job remains red: standalone provisioning received HTTP 502 from npm for Bun 1.3.14 before executing the standalone regression; subsequent script tests did not run. That provisioning script is byte-identical on exact base 8a9ae63 and observed main 7091697. The exact-base run completed its Node/Bun standalone probes and later failed a different no-AK wiring assertion—not this download failure or a fully green baseline. I changed no code, thresholds or retries for this. The Linux job needs a maintainer-side rerun. Current browser smoke finished with 352 passed and one failed: on all three attempts the menu disappears after hovering Edit message and waiting 180 ms, at line 929. The focused exact-base/head/observed-main comparison is now complete: the original case passed on attempt 0 on base 8a9ae63, head 5f93cd5 and observed main 952c6de, with no global/test errors. Configured worker limit was 2; actual workers were 1 per arm. Assertions, retries and timeouts were unchanged. The failure was not reproduced in this isolated current-base comparison. The same unchanged head failed three full-smoke attempts but passed this isolated execution; no source fix or root cause is established, and the full 353-case concurrency/order/load was not recreated. The original upstream gate remains red; automated review is still pending.
On validated source commit 0ff2926, before the main merge, Linux/Node 22: root build/bundle, repository typecheck, formatting of all ten PR files, lint of the seven TypeScript files, the full memory suite (1,136 passed, one existing macOS-only skip; all 32 diagnostic regressions passed), built CLI version/help, startup bundle closure and the restored tracked-tree check passed. My first October 22 attempt remains red: my fork-only harness did not recognize Vitest's serialized Limits, entry bodies/order, links, trust rules and topic files are preserved. I did not add a headless lifecycle or browser fix. The older author-preflight metadata failure and baseline browser failures remain qualified in the PR body; this is not a claim that all upstream checks or maintainer review have passed. 中文说明当前 PR head 为 5f93cd5:为满足 lint gate 变更 0ac1fcc,普通 merge 合入 main 8a9ae63。全部十个 PR 文件及净差异与 0ff2926 一致;当前 5f93cd5 的上游 lint/static、no-AK integration(276 个测试)、TUI parity 及 no-flicker 均通过。Linux job 中 CLI 44,058 通过/101 skipped,core 38,220 通过(含全部 32 个诊断回归)/22 skipped,web-shell 单元测试 12,810 通过;上传的三个 JUnit 报告均无 failure/error。但 job 仍为红色:standalone 准备阶段从 npm 获取 Bun 1.3.14 时收到 HTTP 502,尚未执行 standalone 回归,后续 scripts 测试也未运行。该准备脚本与精确基线 8a9ae63 及观察到的 main 7091697 字节一致。精确基线验证 完成了 Node/Bun standalone probes,之后因另一条 no-AK wiring 断言失败,不能将其描述成同一下载错误或全绿基线。我未因此修改代码、阈值或重试。Linux job 需要 maintainer 侧重跑。当前 browser smoke 为 352 通过、一个失败:三次尝试均在 hover Edit message 并等待 180 ms 后,于第 929 行发现 menu 消失。精确基线/head/观察到的 main 对照已完成:原用例在基线 8a9ae63、head 5f93cd5 和观察到的 main 952c6de 上均于第 0 次尝试通过,无全局或用例错误。配置 worker 上限为 2,每组实际为 1;断言、重试和超时均未改变。本次单用例隔离对照未复现当前基线失败。同一未修改 head 在完整 smoke 中三次失败、在隔离运行中通过;这不证明源码修复或根因,也未重现完整 353 用例的并发、顺序和负载。原上游门禁仍为红色;自动 review 仍待完成。我在 0ff2926 保留此前评审修复并处理本轮:R1-1/3/5/6/9/10 修正持久处理建议、注释、任意根目录诊断、空白分隔及真实受限预算对应建议;R1-2 准确命名长度测试并补短 bidi/反引号变异控制;R1-7 保留 wildcard subpath 导出的兼容 API,同时直接检查实际索引扫描的符号链接拒绝;R1-8/11 补多行尾部及两种警告组合的有效变异控制。R1-4 的非阻塞共享 overflow API 重构暂缓,避免扩大本次诊断修复。所有上限、条目正文/顺序、链接、信任规则及主题文件不变,没有加入 headless 生命周期或浏览器修复。以下远程结果仅对应合并 main 之前的已验证源码提交 0ff2926,不代表新 head 的完整 CI:Linux/Node 22:根目录 build/bundle、全仓 typecheck、全部十个 PR 文件的格式检查、七个 TypeScript 文件的 lint、完整 memory suite(1,136 通过、一个既有 macOS-only skip;32 个诊断回归用例全部通过)、CLI version/help、startup bundle closure 及恢复后的 tracked tree 检查均通过。10 月 22 日的第一次验证仍保留为红色:我的 fork-only harness 未识别 symlink 变异中预期的 Vitest |
 qwen-code-review-bot
left a comment
qwen-code-review-bot
left a comment
There was a problem hiding this comment.
Reviewed. Suggestions are inline.
Not explored to full depth (tool budget reached): "agent reverse-audit (round 2)": empirical measurement of the writer notice's worst-case length against the reader's 1024-unit bound ( npx tsx -e could not resolve the source module from an ev….
中文说明
已审查。 建议见行内评论。
未探索到全部深度(达到工具调用预算):"agent reverse-audit (round 2)":empirical measurement of the writer notice's worst-case length against the reader's 1024-unit bound ( npx tsx -e could not resolve the source module from an ev…。
— qwen3.8-max via Qwen Code /review (v0.25.3)
| const candidates = lines.slice(0, MAX_INDEX_LINES); | ||
| const charCount = candidates.join('\n').length; | ||
| const hasOverlongEntry = candidates.some( |
There was a problem hiding this comment.
[Suggestion] R1-4: The overflow diagnosis being built here is a near-copy of the reader's in truncateManagedAutoMemoryIndex (prompt.ts:194-214), rather than a shared builder in index-budget.ts — the module this diff already made the shared home for describeDroppedIndexEntries, both notice prefixes and the MAX_INDEX_* limits. Three pieces are duplicated: this candidate window plus overlong predicate, the char-overflow reason fragment (identical except the reader appends (${entries.length})), and the overlong lever. The charCount computed on the next line also re-joins up to 200 candidate lines to reproduce a value trimIndexToBudgetDetailed already computed internally two lines earlier (index-budget.ts:69-72) and does not return.
The copies have already drifted inside this one PR, and both notices land in the same prompt paragraph — renderIndexBlock emits the writer notice followed by the reader's — so the model reads two independently-worded diagnoses of one condition. Any future change to the limit semantics or the count/length diagnosis has to be made in two files; miss one and the writer and reader contradict each other about whether shortening entries can help.
Witness:
PROBE_C7_hasWriterDroppedNames= true  AND  PROBE_C7_hasReaderWarning= true
  -> two independently-worded diagnoses of one condition in one prompt block
writer  indexer.ts:242-246   lines.slice(0, MAX_INDEX_LINES) / .some(l => l.length > MAX_INDEX_LINE_CHARS)
reader  prompt.ts:191-194    entries.slice(0, MAX_MANAGED_AUTO_MEMORY_INDEX_LINES).some(...)
charCount indexer.ts:243  ==  raw index-budget.ts:69-72  (computed, not returned)
Have trimIndexToBudgetDetailed return the overflow facts it already has (candidateCount, candidateChars, hasOverlongEntry) on IndexTrimResult, and add one shared builder in index-budget.ts — e.g. describeIndexCharOverflow(chars, hasOverlongEntry) — used by both assembleIndex and truncateManagedAutoMemoryIndex.
Share only the reason fragment, the predicate and the char count. The two lever tails differ deliberately (only the reader advises on an index it did not write), so a single shared lever string would change wording that index-drop-notice.test.ts:107 and prompt.test.ts:154 pin — and the writer's whole notice must stay inside the reader's 1024-unit exemption (prompt.ts:175, trimmed.length - noticeStart <= 1024 &&), or the notice gets budgeted as an entry again, which is the bug this PR fixes.
中文说明
这里构建的溢出诊断与读取侧 truncateManagedAutoMemoryIndex(prompt.ts:194-214)中的实现高度重复,而没有做成 index-budget.ts 里的共享构建函数——而本 diff 已经把 describeDroppedIndexEntries、两个警告前缀和 MAX_INDEX_* 上限都放进了那个模块,它本就是共享实现的归属地。重复的有三处:此处的候选窗口与超长判定、字符溢出原因片段(除读取侧多拼 (${entries.length}) 外完全相同)、以及超长条目的建议文案。下一行计算的 charCount 还把最多 200 行候选重新 join 一次,去还原 trimIndexToBudgetDetailed 在两行之前已在内部算过、却没有返回的值(index-budget.ts:69-72)。
这两份副本在本 PR 内部就已经出现漂移,而两段警告会落在提示词的同一个段落里——renderIndexBlock 先输出写入侧警告、再输出读取侧警告——因此模型会读到对同一状况的两种不同措辞的诊断。今后任何对上限语义或「条数/长度」诊断的修改都必须同时改两个文件;漏掉一处,写入侧与读取侧就会在「缩短条目是否有用」上互相矛盾。
建议让 trimIndexToBudgetDetailed 把它已经算出的溢出事实(candidateCount、candidateChars、hasOverlongEntry)通过 IndexTrimResult 返回,并在 index-budget.ts 增加一个共享构建函数(例如 describeIndexCharOverflow(chars, hasOverlongEntry)),供 assembleIndex 与 truncateManagedAutoMemoryIndex 共用。
只共享原因片段、判定条件与字符数即可。两侧建议文案的结尾是有意不同的(只有读取侧是在为一个不是它写出的索引提供建议),因此共用一个字符串会改动 index-drop-notice.test.ts:107 与 prompt.test.ts:154 所固定的措辞;另外写入侧整段警告必须保持在读取侧 1024 单元的豁免范围内(prompt.ts:175,trimmed.length - noticeStart <= 1024 &&),否则警告会重新被当作条目参与预算,那正是本 PR 要修的缺陷。
— qwen3.8-max via Qwen Code /review (v0.25.3)
There was a problem hiding this comment.
[Suggestion] R1-4: still stands — the writer's overflow diagnosis remains a near-copy of the reader's, and the copies have now demonstrably drifted into separately-wrong advice. Deferred by the author as a non-blocking refactor; keeping this thread as the record.
Re-verified at this head: three production copies of the candidate window now exist (index-budget.ts:69, indexer.ts:242, prompt.ts), each followed by its own overlong predicate and its own cause/lever vocabulary, and the wording has already drifted (the reader's reason carries (200), the writer's does not; the reader grew a third lever branch the writer lacks). The drift cost is no longer hypothetical: this round's R2-1 and R2-2 confirm the writer's copy certifying a false cause and the reader's copy giving false advice, in the same char-budget-overflow region, one executed run each. Both notices still land in one prompt paragraph, so the model reads two independently-worded diagnoses of one condition.
Witness:
round 1: PROBE_C7_hasWriterDroppedNames=true AND PROBE_C7_hasReaderWarning=true
  -> two independently-worded diagnoses of one condition in one prompt block
this round: ripgrep — three production copies of the `slice(0, MAX_INDEX_LINES)` window + per-copy predicates;
  the R2-1 probe (writer copy, false cause) and the R2-2 probe (reader copy, false lever) on the same state class
As round 1: have trimIndexToBudgetDetailed return the overflow facts it already computes (candidateCount, candidateChars, hasOverlongEntry) on IndexTrimResult, and add one shared builder in index-budget.ts (e.g. describeIndexCharOverflow(chars, hasOverlongEntry)) used by both assembleIndex and truncateManagedAutoMemoryIndex; share only the reason fragment, the predicate and the char count. The two lever tails differ deliberately (only the reader advises on an index it did not write — round 1's R1-10 asymmetry), so a single shared lever string would change wording pinned by index-drop-notice.test.ts and prompt.test.ts, and the writer's whole notice must stay inside the reader's 1024-unit exemption (prompt.ts:175 — see R2-3). Please pin the extraction both ways: the writer test at index-drop-notice.test.ts:327 and the reader's char-budget case must stay green through it, and a mutation of the shared predicate must red BOTH sides — today mutating one copy leaves the other's tests green.
中文说明
仍然成立——写入侧的溢出诊断仍是读取侧的近拷贝,且两份副本已被证实各自漂移出不同的错误建议。作者已将此共享重构推迟为非阻塞后续;此线程作为记录保留。
对当前 head 复核:候选窗口现有三处生产副本(index-budget.ts:69、indexer.ts:242、prompt.ts),各自跟随自己的超长判定与原因/杠杆词汇,且措辞已经漂移(读取侧原因带 (200) 后缀,写入侧没有;读取侧新增了写入侧没有的第三杠杆分支)。漂移的代价不再是假设:本轮 R2-1 与 R2-2 分别以实测证实,在同一个字符预算溢出区域,写入侧副本认证了错误原因、读取侧副本给出了错误建议。两段警告仍落在同一个提示词段落,模型读到的是对同一状况的两种独立措辞的诊断。
见证:第 1 轮 PROBE_C7(hasWriterDroppedNames=true 且 hasReaderWarning=true → 同一提示词块中对同一状况的两种独立诊断);本轮 ripgrep 确认三处生产窗口副本与各自的判定,且 R2-1 探针(写入侧副本、错误原因)与 R2-2 探针(读取侧副本、错误杠杆)在同一状态类上各自实测成立。
修复(同第 1 轮):让 trimIndexToBudgetDetailed 通过 IndexTrimResult 返回它已经算出的溢出事实(candidateCount、candidateChars、hasOverlongEntry),并在 index-budget.ts 增加一个共享构建函数(如 describeIndexCharOverflow(chars, hasOverlongEntry)),供 assembleIndex 与 truncateManagedAutoMemoryIndex 共用;只共享原因片段、判定条件与字符数。约束:两侧杠杆尾句是有意不同的(只有读取侧在为不是它写出的索引提供建议——第 1 轮 R1-10 的不对称性),共用一个字符串会改动 index-drop-notice.test.ts 与 prompt.test.ts 固定的措辞;写入侧整段警告必须保持在读取侧 1024 单元豁免内(prompt.ts:175,另见 R2-3)。请双向固定这次提取:写入侧 index-drop-notice.test.ts:327 与读取侧字符预算用例都必须在重构后保持通过,且对共享判定的变异必须让两侧同时变红——今天只改一份副本,另一份的测试依然全绿。
— qwen3.8-max via Qwen Code /review (v0.26.0)
There was a problem hiding this comment.
[Suggestion] R1-4: still stands — the writer's overflow diagnosis remains a hand-rolled twin of the reader's rather than a shared builder in index-budget.ts, and the copies have now demonstrably diverged: this round's R2-1 fix gave the writer the causal overlongEntriesCauseOverflow predicate (indexer.ts:248-249) while the reader kept bare hasOverlongEntry (prompt.ts:194), so identical content receives "too many index entries" from the writer and "index entries are too long" from the reader — the contradiction R3-2 witnesses with executed output. The shared-builder fix — trimIndexToBudgetDetailed returning the overflow facts it already computes plus one index-budget.ts predicate both sides call — now closes R1-4, R2-2 and R3-2 in one move. The author tracks the follow-up in issue 15277.
Witness:
round-3 probe (R3-2): same 200-entry overlong content —
READER: "— index entries are too long. … Keep index entries to one line at most 150 UTF-16 code units…"
WRITER: "— too many index entries. … Merge topic files or remove obsolete ones…"
ordinaryCharCount 30199 > 25000, so length cannot be the cause: the writer is right, the reader is wrong.
The original constraints are unchanged: share only the reason fragment, the predicate and the char count — the two lever tails differ deliberately (only the reader advises on an index it did not write), index-drop-notice.test.ts:107 and prompt.test.ts:154 pin that wording, and the writer's whole notice must stay inside the reader's 1024-unit exemption (prompt.ts:175). Fix witness: the R3-2 and R2-2 mirror tests are the mutations that prove the shared predicate — reverting either side to its hand-rolled copy must red them.
中文说明
仍然成立——写入侧的溢出诊断仍是读取侧的手写孪生副本,而非 index-budget.ts 中的共享构建器,且两份副本现已可实测地分叉:本轮 R2-1 修复让写入侧改用因果判定 overlongEntriesCauseOverflow(indexer.ts:248-249),读取侧仍是 bare hasOverlongEntry(prompt.ts:194),同一内容因此得到写入侧「too many index entries」与读取侧「index entries are too long」的矛盾诊断——R3-2 以执行输出见证了这一矛盾。共享构建器修复——让 trimIndexToBudgetDetailed 返回它已经计算的溢出事实,加上一个两侧共同调用的 index-budget.ts 判定——现在可以一次关闭 R1-4、R2-2 与 R3-2。作者已将后续工作记录在 issue 15277。
(见证见上方英文部分。)
原约束不变:只共享原因片段、判定与字符数——两侧杠杆尾部是有意不同的(只有读取侧在为不是它写出的索引提供建议),index-drop-notice.test.ts:107 与 prompt.test.ts:154 固定该措辞,且写入侧整段警告必须保持在读取侧 1024 单元豁免之内(prompt.ts:175)。修复见证:R3-2 与 R2-2 的镜像测试就是证明共享判定的变异——把任何一侧回退为手写副本必须使其变红。
— qwen3.8-max via Qwen Code /review (v0.26.0)
There was a problem hiding this comment.
[Suggestion] R1-4: still stands — the writer's overflow diagnosis remains a hand-rolled twin of the reader's rather than a shared builder in index-budget.ts, and the copies have now demonstrably diverged into separately-wrong advice: the writer answers "overlong or too many?" with the causal ordinaryCharCount test (indexer.ts:252-253, added by the R2-1 fix), while the reader answers it with bare hasOverlongEntry (prompt.ts:211/:213). Both reason-string formats are duplicated too (indexer.ts:257-260 vs prompt.ts:200-204). This round's R2-2 escalation (reader side) and R4-1 (writer side) are the two divergent outcomes the copies have produced.
In the 169×150 + 1×600 state the writer classifies "too many index entries" while the reader classifies "index entries are too long" — and when the on-disk index carries a writer notice, prompt.ts:217 emits the retained writer notice AND the appended reader lever, so contradictory diagnoses sit in one system prompt. Every wording change must be made twice, and only one copy carries the causal test.
Witness:
git grep at head 12696e61ce:
  indexer.ts:252/:257/:267  overlongEntriesCauseOverflow (causal ordinaryCharCount test)
  prompt.ts:194/:201/:211/:213  hasOverlongEntry (bare length test)
Suggested fix: extract one helper into index-budget.ts — which already owns MAX_INDEX_CHARS, MAX_INDEX_LINE_CHARS, MAX_INDEX_LINES and the shared describeDroppedIndexEntries — e.g. export function indexOverflowCause(candidates: readonly string[]): { charCount: number; overlongCausesOverflow: boolean } implementing the writer's achievable-shortening test, and have both assembleIndex and truncateManagedAutoMemoryIndex call it instead of each computing candidates / char counts / overlong-ness locally.
The reader must keep giving length advice when shortening genuinely helps: prompt.test.ts:449-458 ("keeps blaming entry length when an entry really does exceed the line limit") asserts toContain('index entries are too long') and the 150-unit lever for the single-huge-entry fixture — a shared helper must still classify that case as overlong-caused.
Please add the reader-mirror regression and prove it by mutation: a 200-candidate index where clipping every entry to MAX_INDEX_LINE_CHARS still exceeds MAX_INDEX_CHARS but at least one entry is overlong — asserting the prompt contains "too many index entries" and does NOT contain "Keep index entries to one line at most" (the mirror of index-drop-notice.test.ts:328-360); it must go red against the current hasOverlongEntry-only condition.
中文说明
仍然存在——写入侧的溢出诊断仍是读取侧的手写孪生,而不是 index-budget.ts 中的共享 builder,且两份拷贝已实证分叉成各自错误的建议:写入侧用因果的 ordinaryCharCount 测试回答「超长还是条数过多」(indexer.ts:252-253,R2-1 修复引入),读取侧只用 bare hasOverlongEntry(prompt.ts:211/:213)。两个原因字符串格式也是重复的(indexer.ts:257-260 对 prompt.ts:200-204)。本轮的 R2-2 升级(读取侧)与 R4-1(写入侧)正是两份拷贝产出的两个分叉后果。
在 169×150 + 1×600 状态下,写入侧判「too many index entries」而读取侧判「index entries are too long」——当磁盘索引带有写入侧警告时,prompt.ts:217 同时输出保留的写入侧警告与追加的读取侧杠杆,矛盾诊断同处一个 system prompt。每次措辞修改都要做两遍,且只有写入侧携带因果测试。
见证见上方英文部分(HEAD 上两组判据的 git grep)。
修复建议:把唯一 helper 放进 index-budget.ts——它已拥有 MAX_INDEX_CHARS、MAX_INDEX_LINE_CHARS、MAX_INDEX_LINES 和共享的 describeDroppedIndexEntries——例如 export function indexOverflowCause(candidates: readonly string[]): { charCount: number; overlongCausesOverflow: boolean },实现写入侧的「可缩短性」测试,由 assembleIndex 与 truncateManagedAutoMemoryIndex 共同调用,替代各自本地计算 candidates / 字符数 / 超长判断。
当缩短确实有效时读取侧必须继续给长度建议:prompt.test.ts:449-458(『keeps blaming entry length when an entry really does exceed the line limit』)对单条超大条目 fixture 断言 toContain('index entries are too long') 与 150 单元杠杆——共享 helper 必须继续把该情形判为超长导致。
请补上读取侧镜像回归并用变异验证:构造 200 候选、把每条裁到 MAX_INDEX_LINE_CHARS 后仍超 MAX_INDEX_CHARS、且至少一条超长的索引,断言 prompt 含「too many index entries」且不含「Keep index entries to one line at most」(与 index-drop-notice.test.ts:328-360 镜像)——对当前仅 hasOverlongEntry 的条件为红。
— qwen3.8-max via Qwen Code /review (v0.26.1)
| const { docs, omitted } = await scanAutoMemoryIndexDocumentsFromRoot( | ||
| teamRoot, | ||
| 'team', | ||
| ); |
There was a problem hiding this comment.
[Suggestion] R1-7: This replacement removed the last production caller of scanTeamAutoMemoryTopicDocuments, orphaning it, and the team "deterministic cap because the index is committed and shared" invariant is now encoded twice — deterministic: true in the dead wrapper (structured-scan.ts:877) and deterministic: scope === 'team' in the live one (:626).
Repo-wide the orphan has exactly three references: its definition (structured-scan.ts:872), the test import (structured-scan.test.ts:25) and one test call (:804). It is not re-exported — packages/core/src/index.ts's memory exports include neither memory/scan.js nor memory/structured-scan.js, and package.json's exports map exposes only ./memoryScopes from that directory — so no external consumer keeps it alive. The cost is that a future change to the cap or to followRootSymlink semantics for team scope can be applied to one copy and not the other, and structured-scan.test.ts:804 keeps passing against a function nothing in production calls, so the assertion names the wrong function rather than the one rebuildTeamAutoMemoryIndex actually uses.
To be explicit about what this is not: the security property itself is not unpinned, and an earlier draft of this finding said it was. team-index.test.ts:132,162 pin rebuildTeamAutoMemoryIndex's leaf-symlink and parent-component-symlink rejections directly, and widening listMarkdownFiles' followRootSymlink to include team still reds refuses a symlinked team memory root instead of scanning its target through the live scanAutoMemorySnapshot assertion once the dead-wrapper assertion is removed. So this is orphaned code plus a mis-aimed witness, not a live hole.
Witness:
sweep: scanTeamAutoMemoryTopicDocuments -> 3 hits (definition + 2 in its own test)
mutant: followRootSymlink widened to team
  -> FAIL structured-scan.test.ts > refuses a symlinked team memory root...
  -> with the dead-wrapper assertion at :804 deleted, the SAME mutant still fails
     that test via the live half: expected true to be false (scanAutoMemorySnapshot, :807-812)
Delete scanTeamAutoMemoryTopicDocuments and repoint the assertion at the live path, so the test names the function rebuildTeamAutoMemoryIndex actually calls:
await expect(
  scanAutoMemoryIndexDocumentsFromRoot(teamRoot, 'team'),
).rejects.toThrow('symlinked memory root');
Leave the sibling project-scope case at structured-scan.test.ts:778 alone — scanAutoMemoryTopicDocuments still has production callers (dreamAgentPlanner.ts:167, extractionAgentPlanner.ts:150, remember.ts:127, status.ts:65). Alternatively, keep the wrapper and move its determinism comment onto scanAutoMemoryIndexDocumentsFromRoot.
Please keep the relocated assertion pinning the same property, and ask for the mutation that proves it: it must go red if listMarkdownFiles' followRootSymlink: scope === 'user' is widened to include 'team', i.e. a .qwen/team-memory -> /outside symlink must still be refused rather than scanned.
中文说明
这处替换移除了 scanTeamAutoMemoryTopicDocuments 的最后一个生产调用方,使其成为孤儿;同时 team 的「因为索引会被提交共享,所以上限必须确定」这一不变量现在被编码了两次——已废弃的包装函数里是 deterministic: true(structured-scan.ts:877),在用的那个里是 deterministic: scope === 'team'(:626)。
全仓范围内该孤儿函数只有三处引用:定义(structured-scan.ts:872)、测试导入(structured-scan.test.ts:25)与一次测试调用(:804)。它没有被再导出——packages/core/src/index.ts 的 memory 导出既不含 memory/scan.js 也不含 memory/structured-scan.js,package.json 的 exports 映射在该目录下只暴露 ./memoryScopes——因此没有外部消费者让它存活。代价是:今后对上限或 team 作用域的 followRootSymlink 语义的修改,可能只应用到两份中的一份,而 structured-scan.test.ts:804 仍会针对一个生产中无人调用的函数保持通过,于是该断言指向的是错误的函数,而不是 rebuildTeamAutoMemoryIndex 实际调用的那个。
需要明确它不是什么:安全属性本身并非无人固定,而本条意见的初稿是这么写的。team-index.test.ts:132,162 直接固定了 rebuildTeamAutoMemoryIndex 对叶子符号链接与父级路径符号链接的拒绝;并且把 listMarkdownFiles 的 followRootSymlink 放宽到包含 team 之后,即使删掉那个针对废弃包装函数的断言,refuses a symlinked team memory root instead of scanning its target 仍会通过在用的 scanAutoMemorySnapshot 断言变红。所以这是孤儿代码加一个指错对象的见证,而不是当前的真实漏洞。
建议删除 scanTeamAutoMemoryTopicDocuments,并把断言改指在用的路径(代码见上方英文块),使测试指向 rebuildTeamAutoMemoryIndex 实际调用的函数。structured-scan.test.ts:778 的 project 作用域同类用例请保留——scanAutoMemoryTopicDocuments 仍有生产调用方(dreamAgentPlanner.ts:167、extractionAgentPlanner.ts:150、remember.ts:127、status.ts:65)。另一种做法是保留该包装函数,但把它的确定性注释移到 scanAutoMemoryIndexDocumentsFromRoot 上。
请让迁移后的断言继续固定同一属性,并用变异验证:如果把 listMarkdownFiles 的 followRootSymlink: scope === 'user' 放宽到包含 'team',它必须变红,即 .qwen/team-memory -> /outside 这样的符号链接仍必须被拒绝而不是被扫描。
— qwen3.8-max via Qwen Code /review (v0.25.3)
There was a problem hiding this comment.
[Suggestion] R1-7: still stands — scanTeamAutoMemoryTopicDocuments remains orphaned (now at structured-scan.ts:873), and the retention rationale does not cover these modules. The live-path symlink assertion added this round (structured-scan.test.ts:805-807) genuinely addresses the mis-aimed-witness half of the original finding; the dead wrapper and its own assertion at :808 remain, and the team "deterministic cap because the index is committed and shared" invariant is still encoded twice (deterministic: true in the dead wrapper, deterministic = scope === 'team' in the live helper at :623).
The round-1 rationale ("the package has wildcard subpath exports, so the absence of in-tree production callers alone does not justify deleting that API") was checked at this head: the wildcard "./*": "./dist/src/*" exists and packages/cli really imports through it (memory/refresh.js, memory/paths.js, memory/request-context.js) — but nothing anywhere imports memory/structured-scan.js or memory/scan.js, the core barrel (src/index.ts) exports neither, and packages/core is "private": true. No external consumer keeps it alive; these are internal dead code. The orphan family also grew this round: scanAllAutoMemoryTopicDocumentsFromRoot (:613) lost its last caller to the R1-6 fix (see R2-4).
Witness (sweep at this head):
scanTeamAutoMemoryTopicDocuments -> 2 references, both in structured-scan.test.ts
  (import :26, dead-wrapper assertion :808); 0 production callers
As round 1: delete scanTeamAutoMemoryTopicDocuments and drop the dead-wrapper assertion at :808-810 (the live-path assertion at :805-807 pins the same guard), or keep the wrapper deliberately and move its determinism comment onto scanAutoMemoryIndexDocumentsFromRoot. Leave the sibling project-scope case at structured-scan.test.ts:778 alone — scanAutoMemoryTopicDocuments still has production callers (dreamAgentPlanner.ts:167, extractionAgentPlanner.ts:150, remember.ts:127, status.ts:65). Please keep the pinning mutation: widening listMarkdownFiles' followRootSymlink: scope === 'user' to include 'team' must still red refuses a symlinked team memory root instead of scanning its target through the live assertion — a .qwen/team-memory -> /outside symlink must be refused, not scanned.
中文说明
仍然成立——scanTeamAutoMemoryTopicDocuments 仍是孤儿(现位于 structured-scan.ts:873),且保留理由不覆盖这两个模块。本轮新增的活路径符号链接断言(structured-scan.test.ts:805-807)确实解决了原发现中「见证指错对象」的一半;但死包装及其在 :808 的断言仍在,team「索引被提交共享,所以上限必须确定」的不变量仍被编码两次(死包装里 deterministic: true,活助手 :623 里 deterministic = scope === 'team')。
第 1 轮的保留理由(「包有 wildcard subpath exports,因此仅凭树内无生产调用方不足以删除该 API」)已在当前 head 核实:通配导出 "./*": "./dist/src/*" 确实存在,packages/cli 也确实经它导入(memory/refresh.js、memory/paths.js、memory/request-context.js)——但没有任何文件导入 memory/structured-scan.js 或 memory/scan.js,core barrel(src/index.ts)也不导出,且 packages/core 为 "private": true。没有外部消费者让它存活;这是内部死代码。本轮孤儿家族还扩大了:scanAllAutoMemoryTopicDocumentsFromRoot(:613)在 R1-6 修复后失去最后一个调用方(见 R2-4)。
见证(当前 head 全仓扫描):scanTeamAutoMemoryTopicDocuments → 2 处引用,均在 structured-scan.test.ts(import :26、死包装断言 :808);生产调用方 0 处。
修复(同第 1 轮):删除 scanTeamAutoMemoryTopicDocuments 并移除 :808-810 的死包装断言(:805-807 的活路径断言固定同一保护),或有意保留包装并把其确定性注释移到 scanAutoMemoryIndexDocumentsFromRoot 上。约束:structured-scan.test.ts:778 的 project 作用域同类用例请保留——scanAutoMemoryTopicDocuments 仍有生产调用方(dreamAgentPlanner.ts:167、extractionAgentPlanner.ts:150、remember.ts:127、status.ts:65)。请保留验证变异:把 listMarkdownFiles 的 followRootSymlink: scope === 'user' 放宽到包含 'team',必须仍能通过活路径断言让 refuses a symlinked team memory root instead of scanning its target 变红——.qwen/team-memory -> /outside 的符号链接必须被拒绝而不是被扫描。
— qwen3.8-max via Qwen Code /review (v0.26.0)
There was a problem hiding this comment.
[Suggestion] R1-7: still stands — scanTeamAutoMemoryTopicDocuments remains orphaned (now at structured-scan.ts:873; this PR's team-rebuild rewiring removed its last production caller), and the team "deterministic cap because the index is committed and shared" invariant remains encoded twice — deterministic: true in the dead wrapper versus deterministic = scope === 'team' in the live one. structured-scan.ts is unchanged since round 2. The author tracks the follow-up in issue 15277.
Witness:
round-3 git grep at head 1d595e2f: scanTeamAutoMemoryTopicDocuments -> 3 hits:
  definition (structured-scan.ts:873) + structured-scan.test.ts:26, :808 — no production caller.
The original ask is unchanged: delete the wrapper and repoint the :808 assertion at the live path — await expect(scanAutoMemoryIndexDocumentsFromRoot(teamRoot, 'team')).rejects.toThrow('symlinked memory root') (the assertion this PR adds at :805-807 already pins the same guard); keep the project-scope sibling at :778, and the relocated assertion must go red under the mutation widening listMarkdownFiles' followRootSymlink: scope === 'user' to include 'team' — a .qwen/team-memory -> /outside symlink must still be refused rather than scanned.
中文说明
仍然成立——scanTeamAutoMemoryTopicDocuments 仍是孤儿(现位于 structured-scan.ts:873;本 PR 的 team 重建改接移除了它最后一个生产调用方),team 的「因为索引被提交共享,所以上限必须确定」不变量仍被编码两次——废弃包装里的 deterministic: true 与在用实现里的 deterministic = scope === 'team'。structured-scan.ts 自第 2 轮以来未变。作者已将后续工作记录在 issue 15277。
(见证见上方英文部分。)
原修复要求不变:删除该包装,并把 :808 的断言改指活路径——await expect(scanAutoMemoryIndexDocumentsFromRoot(teamRoot, 'team')).rejects.toThrow('symlinked memory root')(本 PR 在 :805-807 新增的断言已固定同一保护);保留 :778 的 project 作用域同类用例,且迁移后的断言必须在「把 listMarkdownFiles 的 followRootSymlink: scope === 'user' 放宽到包含 'team'」的变异下变红——.qwen/team-memory -> /outside 这样的符号链接必须仍被拒绝而不是被扫描。
— qwen3.8-max via Qwen Code /review (v0.26.0)
There was a problem hiding this comment.
[Suggestion] R1-7: still stands — scanTeamAutoMemoryTopicDocuments remains orphaned (now at structured-scan.ts:886; this PR's team-rebuild rewiring at indexer.ts:518-521 removed its last production caller), and the team "deterministic cap because the index is committed and shared" invariant now lives only in dead code, while the live rule is the uncommented default deterministic = scope === 'team' (structured-scan.ts:636).
The orphaned helper still reads as THE team-index scan (name + rationale comment) but returns a bare capped array with no omitted tail: a future caller wiring a team rebuild picks it and silently re-creates issue #14877 for the committed team index. Meanwhile a future edit flipping the live default has no comment and no test explaining that it would make the committed MEMORY.md differ per machine and ping-pong the ff-only sync.
Witness:
git grep scanTeamAutoMemoryTopicDocuments at head 12696e61ce:
  structured-scan.ts:886:export async function scanTeamAutoMemoryTopicDocuments(
  structured-scan.test.ts:27   (import)
  structured-scan.test.ts:809  (symlink assertion - re-added for the new function at :806-808)
  <- zero production callers
Suggested fix: delete scanTeamAutoMemoryTopicDocuments and its now-redundant assertion at structured-scan.test.ts:809 (plus the import at :27), and move its "Deterministic cap: the team index is committed and shared…" comment onto the deterministic = scope === 'team' default in scanAutoMemoryIndexDocumentsFromRoot.
structured-scan.test.ts:806-808 must survive the deletion — it already pins the same symlink trust boundary for the new entry point (rejects.toThrow('symlinked memory root')).
The fix deletes code and relocates a comment, so no new test pins it; the surviving guard at :806-808 is the check.
中文说明
仍然存在——scanTeamAutoMemoryTopicDocuments 依旧孤立(现在位于 structured-scan.ts:886;本 PR 在 indexer.ts:518-521 的 team 重建重接移除了它最后一个生产调用者),team「确定性上限,因为索引被提交共享」的不变量现在只存在于死代码里,而活的规则是无注释的默认值 deterministic = scope === 'team'(structured-scan.ts:636)。
孤立 helper 看起来仍是 team 索引扫描的正主(函数名 + 理由注释),却返回不带 omitted 尾部的裸截断数组:未来接线 team 重建的调用者选它会为已提交的 team 索引无声重演 issue #14877。同时,未来翻转活默认值的编辑没有注释也没有测试说明:那会让提交的 MEMORY.md 因机器而异,把 ff-only 同步来回打乒乓。
见证见上方英文部分(git grep 三处命中:定义、测试 import、测试断言;零生产调用者)。
修复建议:删除 scanTeamAutoMemoryTopicDocuments 及其现在冗余的 structured-scan.test.ts:809 断言(连同 :27 的 import),并把它的「Deterministic cap: the team index is committed and shared…」注释移到 scanAutoMemoryIndexDocumentsFromRoot 的 deterministic = scope === 'team' 默认值上。
structured-scan.test.ts:806-808 必须在删除后存活——它已为新入口固定同一 symlink 信任边界(rejects.toThrow('symlinked memory root'))。
修复是删除代码并迁移注释,无新测试可固定;:806-808 的存活守卫即为验证。
— qwen3.8-max via Qwen Code /review (v0.26.1)
There was a problem hiding this comment.
[Suggestion] R1-7: still standing from round 1. This diff's team-rebuild rewiring here removed the last production caller of scanTeamAutoMemoryTopicDocuments (now at structured-scan.ts:886), orphaning it. The team "deterministic cap because the index is committed and shared" invariant is now encoded twice — once in the live path through scanAutoMemoryIndexDocumentsFromRoot(teamRoot, 'team'), whose deterministic = scope === 'team' default supplies it, and once in a function nothing in production calls.
The concrete cost is that the test asserting the invariant now names the wrong function. structured-scan.test.ts:804 keeps passing against a function no production caller reaches, so the symlink/ordering assertion beside the one this diff added at :806-808 no longer pins the behaviour rebuildTeamAutoMemoryIndex actually depends on — a future change to the live team path can break the invariant while that test stays green.
Witness (exhaustive ripgrep over the whole worktree, production and tests, at head f76cabf67f):
scanTeamAutoMemoryTopicDocuments:
  structured-scan.ts:886        <- its own definition
  structured-scan.test.ts:27    <- import
  structured-scan.test.ts:809   <- assertion
  production callers: 0
packages/core/src/index.ts re-exports memory/scan.js or structured-scan.js: NO
Because neither symbol is re-exported from the package entry, removing it is not a breaking change to @qwen-code/qwen-code-core consumers.
Delete scanTeamAutoMemoryTopicDocuments and migrate structured-scan.test.ts:804-809 onto scanAutoMemoryIndexDocumentsFromRoot(teamRoot, 'team'), so the deterministic-ordering and symlink-rejection assertions pin the function rebuildTeamAutoMemoryIndex actually calls. The migrated assertions must stay green and reverting the migration must leave them naming a function with no production caller again — that is the whole point of the move, so please confirm the assertion still exercises the live path rather than only compiling.
中文说明
R1-7:第 1 轮提出、至今仍然存在。本 diff 在此处对 team 重建路径的改写,移除了 scanTeamAutoMemoryTopicDocuments(现位于 structured-scan.ts:886)最后一个生产调用方,使其成为孤儿。team 作用域「因为索引会被提交并共享,所以必须使用确定性上限」这一不变量现在被编码了两次——一次在经由 scanAutoMemoryIndexDocumentsFromRoot(teamRoot, 'team') 的活跃路径中(其 deterministic = scope === 'team' 默认值提供了该行为),另一次在一个生产代码从不调用的函数里。
具体代价是:断言该不变量的测试现在指向了错误的函数。structured-scan.test.ts:804 会持续通过,而它测的函数已无任何生产调用方触达;因此紧邻本 diff 在 :806-808 新增断言的那个符号链接/排序断言,已不再固定 rebuildTeamAutoMemoryIndex 实际依赖的行为——将来对活跃 team 路径的修改可以破坏该不变量,而该测试仍然全绿。
见证(在 head f76cabf67f 对整个工作树做穷尽 ripgrep,含生产代码与测试)见上方英文部分:scanTeamAutoMemoryTopicDocuments 只有自身定义、一处 import、一处断言,生产调用方为 0;packages/core/src/index.ts 未再导出 memory/scan.js 或 structured-scan.js,因此删除它不构成对 @qwen-code/qwen-code-core 使用者的破坏性变更。
修复:删除 scanTeamAutoMemoryTopicDocuments,并把 structured-scan.test.ts:804-809 迁移到 scanAutoMemoryIndexDocumentsFromRoot(teamRoot, 'team'),使确定性排序与符号链接拒绝的断言固定 rebuildTeamAutoMemoryIndex 实际调用的函数。迁移后的断言必须保持通过,而回退迁移必须使它们重新指向一个没有生产调用方的函数——这正是本次移动的意义,因此请确认该断言确实仍在执行活跃路径,而不仅仅是能编译通过。
— qwen3.8-max via Qwen Code /review (v0.26.1)

qwen-code-review-bot
left a comment
qwen-code-review-bot
left a comment
There was a problem hiding this comment.
Partially reviewed — gaps disclosed.
1 Suggestion-level finding(s) this review confirmed are already reported on this PR and are not repeated:
- writer/reader budget-pressure derivation duplication (indexer.ts:242) — already reported (R1-4, comment 4343381355)
Not explored to full depth (tool budget reached): "agent 4": did not run npm run build && npm run bundle to measure the esbuild metafile byte delta; the bundle conclusion above rests on reading the import lists and conf….
Not reviewed: reverse audit — stopped before round 6 by the review time budget.
Test Plan (not a blocker): 38,220 passed — this review observed 38060, 2814, 43875, 1028, 2274, 641, 12810 passed; 352 passed — this review observed 38060, 2814, 43875, 1028, 2274, 641, 12810 passed; 1,136 passed — this review observed 38060, 2814, 43875, 1028, 2274, 641, 12810 passed; 348 passed — this review observed 38060, 2814, 43875, 1028, 2274, 641, 12810 passed.
Deferred under the convergence posture (round 2, not a blocker) — recorded, not requested in this round:
packages/core/src/memory/index-budget.ts:15 — [review] Orphaned notice vocabulary: INDEX_TRUNCATION_WARNING/INDEX_TRUNCATION_NOTICE/trimIndexToBudget have zero production consumers but read as livepackages/core/src/memory/indexer.ts:266 — [probe] Scan-cap remedy carries no pinned/ carve-out: an omitted pinned record is named by title only and advised for removalpackages/core/src/memory/indexer.ts:281 — [probe] Omitted topic files sampled by title, not path — same-name omissions indistinguishable, remedy unactionablepackages/core/src/memory/indexer.ts:282 — [probe] Scan-cap notice total counts group-dropped siblings as listed: retained team files whose (also:) link does not fit vanish uncountedpackages/core/src/memory/indexer.ts:285 — [probe] 'Scan limit: ${docs.length} files.' publishes the retained-array size as the limit instead of MAX_SCANNED_MEMORY_FILESpackages/core/src/memory/prompt.ts:174 — [probe] Notice-exemption gate is shape-based: forged single-paragraph WARNING tails get guaranteed delivery; U+2028/U+2029 pass the checkpackages/core/src/memory/structured-scan.ts:634 — [review] New helper re-applies the scan cap (third cap-application copy), diverging from the status.ts reporting pathpackages/core/src/memory/structured-scan.ts:635 — [probe] Parse/read-failed topic files never appear in the omission diagnostic; at or under 200 survivors there is no notice at all
中文说明
仅完成部分审查,审查缺口已披露。
本轮确认的 1 条建议级发现已在 PR 上报告过,不再重复发布(列表见上方英文部分)。
未探索到全部深度(达到工具调用预算):"agent 4":did not run npm run build && npm run bundle to measure the esbuild metafile byte delta; the bundle conclusion above rests on reading the import lists and conf…。
未审查:反向审计——评审时间预算不足,未能开始第 6 轮。
Test Plan(非阻断):38,220 passed — this review observed 38060, 2814, 43875, 1028, 2274, 641, 12810 passed; 352 passed — this review observed 38060, 2814, 43875, 1028, 2274, 641, 12810 passed; 1,136 passed — this review observed 38060, 2814, 43875, 1028, 2274, 641, 12810 passed; 348 passed — this review observed 38060, 2814, 43875, 1028, 2274, 641, 12810 passed。
收敛姿态下延后(第 2 轮,非阻断)——已记录,本轮不要求修改:共 8 条(原文未翻译,列表见上方英文部分)。
— qwen3.8-max via Qwen Code /review (v0.26.0)
| : hasOverlongEntry | ||
| ? ' Shortening entries cannot reduce the line count — prune or merge entries.' | ||
| : ` No candidate entry exceeds the ${MAX_INDEX_LINE_CHARS}-unit line limit, so shortening entries cannot help — prune or merge entries.`; |
There was a problem hiding this comment.
[Suggestion] R2-2: The reader lever's third branch claims "shortening entries cannot help" exactly when the character budget binds and no candidate is overlong — the one state where shortening entries is what works — and it now contradicts the remedy this PR's own fix round added to docs/users/features/memory.md:101 ("or shorten their frontmatter names and descriptions").
Executed: a MEMORY.md of 200 entries at 137 units each (27,599 > 25,000, none over 150) loads 181 of 200 entries and warns …too many index entries (200). Only part of it was loaded. Dropped 19 of 200 entries: … No candidate entry exceeds the 150-unit line limit, so shortening entries cannot help — prune or merge entries. Doing what the user doc says instead — trimming hooks to 60 units — yields 12,199 units, no warning, all 200 entries loaded. An agent that trusts the warning prunes or merges stored memories (irreversible) when a reversible edit would have kept every entry.
Witness (probe against the real buildManagedAutoMemoryPrompt):
ARM A (200x137 units): entries in prompt 181/200 | warning carries 'shortening entries cannot help'
ARM B (hooks trimmed to 60 units): 12199 units | 200/200 entries | NO warning
ARM C control (250-line line-cap case): same sentence is correct there
Restrict the "shortening cannot help" claim to line-count overflow; when the binding limit is the character budget and no candidate is overlong, name shortening as the lever (e.g. " Shorten entry descriptions, or prune/merge entries to fit 25,000 units."). The fix must keep index-drop-notice.test.ts:184 green — it asserts toContain('No candidate entry exceeds the 150-unit line limit') for the 250-line line-cap case, where the sentence is correct. Please add the mirror test and ask for the mutation that proves it: an over-char-budget index whose every candidate is ≤150 units, asserting the warning does NOT contain "shortening entries cannot help" and names shortening as a lever — reverting the branch gate must red it.
中文说明
读取侧杠杆的第三分支在「字符预算是约束、且没有任何候选超过 150 单元」时声称「shortening entries cannot help — prune or merge entries」——这恰恰是缩短条目最有效的状态,并且与本 PR 修复轮刚写入 docs/users/features/memory.md:101 的建议(「or shorten their frontmatter names and descriptions」)自相矛盾。
实测:200 条 × 137 单元的 MEMORY.md(27,599 > 25,000,无一超长)载入 181/200 条,警告称缩短无用;把 hook 修剪到 60 单元后 → 12,199 单元、200/200 全部载入、无警告。相信警告的 agent 会去删并记忆(不可逆),而可逆的修剪本可保住全部条目。
见证(针对真实 buildManagedAutoMemoryPrompt 的探针):ARM A(200×137 单元):提示词载入 181/200,警告含「shortening entries cannot help」;ARM B(hook 修剪到 60 单元):12,199 单元、200/200、无警告;ARM C 对照(250 行、行数上限场景):同一句话在那里是正确的。
修复:把「cannot help」限定为行数上限溢出;当约束是字符预算且无超长候选时,把缩短列为杠杆(例如「 Shorten entry descriptions, or prune/merge entries to fit 25,000 units.」)。约束:修复必须保持 index-drop-notice.test.ts:184 通过——它为 250 行(行数上限)场景固定了 toContain('No candidate entry exceeds the 150-unit line limit'),该句对行数场景必须保留。请补镜像测试并用变异验证:全部候选 ≤150 单元但超字符预算的索引,断言警告不含「shortening entries cannot help」且把缩短列为杠杆;回退分支门控须变红。
— qwen3.8-max via Qwen Code /review (v0.26.0)
There was a problem hiding this comment.
[Suggestion] R2-2: still stands — the reader lever's third branch still claims "shortening entries cannot help" exactly when the character budget binds and no candidate is overlong: the one state where shortening entries IS the remedy (200 × 137-unit store loads 181/200 entries; trimming hooks to 60 units recovers all 200 with no warning). prompt.ts is byte-identical since round 2, so the original ARM A/B/C probe against the real buildManagedAutoMemoryPrompt applies unchanged. This round's new R3-2 is the mirror sibling — the reason clause plus branch 1 misattributing to length in the state where shortening cannot rescue the budget — and both share one root: the reader keying on bare hasOverlongEntry instead of the writer's new causal predicate. One shared overlongEntriesCauseOverflow fixes both. The author tracks the follow-up in issue 15277; keeping this thread open as the record.
Witness:
prompt.ts unchanged between 5f93cd5d (round-2 head) and 1d595e2f (this head) — no hunks in the file;
the round-2 probe (ARM A: 181/200 entries + "shortening entries cannot help"; ARM B: trim to 60 units
-> 12,199 units, 200/200 entries, no warning) applies to the code at this commit verbatim.
The original ask is unchanged: restrict the "shortening cannot help" claim to line-count overflow, and name shortening as the lever when the character budget binds with no overlong candidate; index-drop-notice.test.ts:184 must stay green, and the new mirror test (over-char-budget index, every candidate ≤150 units, asserting the warning names shortening as a lever) must go red when the branch gate is reverted.
中文说明
仍然成立——读取侧杠杆第三分支在「字符预算 binding 且无候选超长」的状态——缩短条目恰是解法的唯一状态——仍声称「shortening entries cannot help」(200 × 137 单元存储载入 181/200 条;把 hook 修剪到 60 单元即可 200/200 全部载入且无警告)。prompt.ts 自第 2 轮以来字节未变,原有 ARM A/B/C 探针原样适用于当前提交。本轮新增的 R3-2 是其镜像姊妹(原因子句 + 第一分支在「缩短救不回预算」的状态误归因于长度),两者同根:读取侧仍用 bare hasOverlongEntry 而非写入侧的新因果判定;一个共享的 overlongEntriesCauseOverflow 可同时修复两者。作者已将后续工作记录在 issue 15277;本线程保持开放作为记录。
(见证见上方英文部分。)
原修复要求不变:把「缩短无用」限定为行数溢出;字符预算 binding 且无超长候选时把缩短列为杠杆;index-drop-notice.test.ts:184 保持绿色;新增镜像测试(超字符预算、全部候选 ≤150 单元,断言警告把缩短列为杠杆),回退分支门控必须变红。
— qwen3.8-max via Qwen Code /review (v0.26.0)
There was a problem hiding this comment.
[Critical] R2-2: [certifies-falsely] The reader lever's third branch tells the agent "shortening entries cannot help" in exactly the states where shortening below the 150-unit ordinary bound is the one remedy that preserves every memory — entries each legal (≤150 units) but collectively over the 25,000-unit budget. Filed as a Suggestion in rounds 2-3; re-adjudicated Critical this round after executed probes measured the consequence on both reachable states.
State 1 (only the char budget binds): 170 entries at exactly 150 units (25,669 > 25,000; line count 170 ≤ 200). Shortening each entry 150→140 clears the warning and keeps 170/170; doing what the notice prescribes instead (prune 5 entries) clears the warning but leaves 165 loaded — 5 memories permanently out of the catalog. State 2 (both caps bind; no shipped fixture covers it): 251 lines whose first 200 candidates sit at 130 units each (candidateChars 26,199 > 25,000, nothing overlong) — the branch still says shortening cannot help, while shortening 130→120 recovers all 10 char-dropped entries (kept 190→200) with nothing pruned or merged. Root cause: branch 3 fires whenever no candidate exceeds 150 units, without ever asking whether sub-150 shortening clears the char budget among the candidates. The merge base emits the same false sentence, and this diff rewrites and re-blesses the line ("No entry" → "No candidate entry"; the new comment at :209 argues only the line-cap sibling); prompt.test.ts:414 pins the false sentence at :428.
Witness:
State 1 (170 x 150 units, charCount 25,669 > 25,000):
PR: "...25669 UTF-16 code units (limit: 25000) - too many index entries (170).
     Only part of it was loaded. Dropped 5 of 170 entries...
     No candidate entry exceeds the 150-unit line limit, so shortening entries cannot help - prune or merge entries."
  shorten arm (170 x 140 = 23,969): warning=false, kept=170
  prune arm (as prescribed):        warning=false, kept=165  <- 5 memories permanently unloaded
State 2 (251 lines, first 200 x 130 units):
  as shipped:  candidateChars=26199, kept=190, "Dropped 61 of 251", lever says shortening cannot help
  130->120:    candidateChars=24199, kept=200  <- all 10 char-dropped entries recovered
Suggested fix — gate the third branch on the candidate char count, so "shortening cannot help" is claimed only when the character budget does not bind among the candidates:
const candidateChars = candidates.join('\n').length;
const lever =
  candidateChars > MAX_INDEX_CHARS && hasOverlongEntry
    ? ` Keep index entries to one line at most ${MAX_INDEX_LINE_CHARS} UTF-16 code units; move detail into topic files. Prune or merge entries if the count is still over budget.`
    : candidateChars > MAX_INDEX_CHARS
      ? ` Shorten entries below the ${MAX_INDEX_LINE_CHARS}-unit line limit to fit more inside the ${MAX_INDEX_CHARS}-unit budget; prune or merge entries to reduce the line count.`
      : hasOverlongEntry
        ? ' Shortening entries cannot reduce the line count — prune or merge entries.'
        : ` No candidate entry exceeds the ${MAX_INDEX_LINE_CHARS}-unit line limit, so shortening entries cannot help — prune or merge entries.`;
The new branch must key on candidates.join('\n').length, never on charCount/entryContent.length (which count an excluded tail): index-drop-notice.test.ts:173 pins a 251-line index whose overflow comes only from an excluded 'x'.repeat(25_003) line 201 (assertion at :184), and :412 asserts not.toContain('No candidate entry exceeds') for the shape whose slice(0,200) join is pinned < 25,000 at :401 — keying on the wrong measure inverts both.
Please add the two regression cases and prove them by mutation: 170 lines of exactly 150 units, and 250 entries of 130 units plus a short tail, each asserting the prompt does NOT contain "shortening entries cannot help" and DOES name shortening as a lever — red on this head, and deleting the new candidateChars branch must red them again. The fix also flips prompt.test.ts:414 ("blames the entry count, not entry length, when every entry is legal", asserting the false sentence at :428) — measured the only existing failure under the fix; update that case to the corrected behaviour.
中文说明
读取侧杠杆的第三分支恰恰在「把条目缩短到 150 单元以下是唯一能保住全部记忆的补救」的状态下告诉 agent「shortening entries cannot help」——每个条目都合法(≤150 单元)、但合计超出 25,000 单元预算。第 2-3 轮以 Suggestion 报告;本轮通过执行探针实测两种可达状态的后果后,重新判定为 Critical。
状态 1(仅字符预算触发):170 个条目、每行恰好 150 单元(25,669 > 25,000;行数 170 ≤ 200)。把每个条目从 150 缩到 140 即可消除警告并保留 170/170;而照警告执行(删减 5 个条目)虽消除警告,却只剩 165 条被加载——5 条记忆被永久移出目录。状态 2(两条上限同时触发;现有 fixture 未覆盖):251 行,其中前 200 个候选每条恰好 130 单元(candidateChars 26,199 > 25,000,无超长条目)——该分支仍称缩短无用,而实测把 130 缩到 120 后,10 个因字符预算被丢弃的条目全部恢复(保留 190→200),无需删减或合并任何文件。根因:第三分支只在「没有候选超过 150 单元」时触发,从未询问「缩到 150 以下能否在候选范围内解除字符超限」。合并基线版本会输出同样的错误句子,而本 diff 重写并再次确认了该行(No entry → No candidate entry;:209 的新注释只论证了行数上限的兄弟状态);prompt.test.ts:414 在 :428 固定了这句错误文案。
见证与修复代码见上方英文部分(两种状态的探针输出、candidateChars 门控的修复、以及修复会翻转 prompt.test.ts:414 的实测)。
修复约束:新分支必须以 candidates.join('\n').length 为判据,绝不能用 charCount/entryContent.length(它们把已被行数上限排除的尾部也计入):index-drop-notice.test.ts:173 固定了「溢出来自被排除的 'x'.repeat(25_003) 第 201 行」的 251 行索引(:184 断言),:412 对 slice(0,200) 合计 < 25,000(:401 固定)的形状断言 not.toContain('No candidate entry exceeds')——用错判据会把两者都反转。
请补上两个回归用例并用变异验证:170 行恰好 150 单元,以及 250 条 130 单元加一条短尾,各自断言 prompt 不含「shortening entries cannot help」且给出缩短杠杆——当前 head 为红,删除新的 candidateChars 分支须再次变红。修复同时会翻转 prompt.test.ts:414(『blames the entry count, not entry length, when every entry is legal』,在 :428 断言错误文案)——实测这是修复下唯一失败的既有用例,请把它更新为修正后的行为。
— qwen3.8-max via Qwen Code /review (v0.26.1)
There was a problem hiding this comment.
[Critical] R2-2: [certifies-falsely] Still standing from round 2. The reader lever's third branch tells the agent "shortening entries cannot help" in exactly the states where shortening below the 150-unit bound is the one remedy that preserves every memory. The branch fires whenever no candidate exceeds MAX_INDEX_LINE_CHARS, without ever asking whether sub-150 shortening would clear the character budget among the candidates. Meanwhile the writer half of this same PR now diagnoses that identical state as cumulative index entry length and prescribes description edits, so one change hands the agent two contradictory instructions for the same file content.
State 1, only the character budget binds: 170 entries at exactly 150 units, charCount 25,669 against a 25,000 limit, line count 170 within the 200 cap. Shortening each entry from 150 to 140 clears the warning and keeps 170 of 170; obeying the notice instead and pruning 5 entries also clears the warning but leaves 165 loaded, so 5 memories are permanently out of the catalog. State 2, both caps bind: 251 lines whose first 200 candidates sit at 130 units (candidateChars 26,199, nothing overlong) keeps 190 and still says shortening cannot help, while going from 130 to 120 recovers all 10 character-dropped entries (190 to 200) with nothing pruned or merged.
Measured reach this round: for a writer-produced file the reader adds nothing, because the writer already trims the body to 24,914 units and the reader returns it unchanged, so the two contradictory voices reach the agent only for handwritten or out-of-band indexes. Recorded for the maintainer's call rather than as new work: the merge base emits the same false sentence, this diff rewords and re-blesses the line ("No entry" becomes "No candidate entry"), and the author has explicitly deferred reader advice to #15368. It is re-reported because it still stands as a blocker on this PR's own record, not because the round-5 diff introduced it.
Witness (probe against the real buildManagedAutoMemoryPrompt at head f76cabf67f, 200 handwritten lines of exactly 150 units, body 30,199):
READER: "> WARNING: MEMORY.md is 30199 UTF-16 code units (limit: 25000) — too many index entries (200).
         Only part of it was loaded. Dropped 35 of 200 entries: …
         No candidate entry exceeds the 150-unit line limit, so shortening entries cannot help — prune or merge entries."
WRITER (this PR, same state):
        "…— cumulative index entry length. … Shorten topic-file paths or frontmatter names/descriptions…"
Gate the third branch on the candidate character count, so "shortening cannot help" is claimed only when the character budget does not bind among the candidates:
const candidateChars = candidates.join('\n').length;
const lever =
  candidateChars > MAX_INDEX_CHARS && hasOverlongEntry
    ? ` Keep index entries to one line at most ${MAX_INDEX_LINE_CHARS} UTF-16 code units; move detail into topic files. Prune or merge entries if the count is still over budget.`
    : candidateChars > MAX_INDEX_CHARS
      ? ` Shorten entries below the ${MAX_INDEX_LINE_CHARS}-unit line limit to fit more inside the ${MAX_INDEX_CHARS}-unit budget; prune or merge entries to reduce the line count.`
      : hasOverlongEntry
        ? ' Shortening entries cannot reduce the line count — prune or merge entries.'
        : ` No candidate entry exceeds the ${MAX_INDEX_LINE_CHARS}-unit line limit, so shortening entries cannot help — prune or merge entries.`;
The new branch must key on candidates.join('\n').length, never on charCount or entryContent.length, which count a tail the line cap already excluded: index-drop-notice.test.ts:173 pins a 251-line index whose overflow comes only from an excluded 'x'.repeat(25_003) line 201 (assertion at :184), and :412 asserts not.toContain('No candidate entry exceeds') for the shape whose slice(0,200) join is pinned under 25,000 at :401 — keying on the wrong measure inverts both. Please add the two regression cases and prove them by mutation: 170 lines of exactly 150 units, and 250 entries of 130 units plus a short tail, each asserting the prompt does not contain "shortening entries cannot help" and does name shortening as a lever — red on this head, and deleting the new candidateChars branch must red them again. The fix also flips prompt.test.ts:414 ("blames the entry count, not entry length, when every entry is legal"), which currently pins the false sentence at :428, so that case needs updating to the corrected behaviour.
中文说明
第 2 轮提出、至今仍然存在。读取侧 lever 的第三个分支恰恰在「把条目缩短到 150 单元以下是唯一能保住全部记忆的补救」的状态下告诉 agent「shortening entries cannot help」。该分支只在「没有候选超过 MAX_INDEX_LINE_CHARS」时触发,从未询问「缩到 150 以下能否在候选范围内解除字符超限」。而本 PR 的写入侧对完全相同的状态现在判定为「cumulative index entry length」并建议修改描述——同一个改动对同一份文件内容给出了两套互相矛盾的指引。
状态一(仅字符预算触发):170 个条目、每行恰好 150 单元,charCount 25,669 超出 25,000,行数 170 未超 200 上限。把每条从 150 缩到 140 即可消除警告并保留 170/170;而照警告执行删减 5 条同样能消除警告,却只剩 165 条被加载——5 条记忆被永久移出目录。状态二(两条上限同时触发):251 行,前 200 个候选每条 130 单元(candidateChars 26,199,无超长条目),保留 190 条且仍称缩短无用;而把 130 缩到 120 后,10 个因字符预算被丢弃的条目全部恢复(190→200),无需删减或合并。
本轮实测影响范围:对写入侧生成的文件,读取侧不会追加任何内容(写入侧已把正文裁到 24,914 单元,读取侧原样返回),因此两套矛盾说法只在手写或带外索引上同时出现在 agent 面前。以下事实供维护者判断,而非本轮新发现:合并基线输出同样的错误句子,本 diff 重写并再次确认了该行(「No entry」改为「No candidate entry」),作者已明确把读取侧建议单独放到 #15368。之所以再次报告,是因为它作为本 PR 记录上的阻断项仍然存在,而不是因为第 5 轮的 diff 引入了它。
见证(针对 head f76cabf67f 真实 buildManagedAutoMemoryPrompt 的探针,200 行手写条目、每行恰好 150 单元,正文 30,199)见上方英文部分的输出。
修复:把第三个分支门控在候选字符数上,只有当字符预算在候选范围内确实不触发时才声称「缩短无用」。新分支必须以 candidates.join('\n').length 为判据,绝不能用 charCount 或 entryContent.length(它们把已被行数上限排除的尾部也计入):index-drop-notice.test.ts:173 固定了溢出来自被排除的 'x'.repeat(25_003) 第 201 行的 251 行索引(:184 断言),:412 对 slice(0,200) 合计小于 25,000(:401 固定)的形状断言 not.toContain('No candidate entry exceeds')——用错判据会把两者都反转。
请补上两个回归用例并用变异验证:170 行恰好 150 单元,以及 250 条 130 单元加一条短尾,各自断言 prompt 不含「shortening entries cannot help」且给出缩短杠杆——当前 head 为红,删除新的 candidateChars 分支须再次变红。修复同时会翻转 prompt.test.ts:414(「blames the entry count, not entry length, when every entry is legal」,在 :428 断言错误文案),请把该用例更新为修正后的行为。
— qwen3.8-max via Qwen Code /review (v0.26.1)
There was a problem hiding this comment.
[Critical] R2-2: [certifies-falsely] The reader's lever tells the model "shortening entries cannot help" in the one state where shortening entries is the only lossless remedy — when every entry is inside the 150-unit line limit but the entries are collectively over the 25,000-unit character budget.
MAX_INDEX_LINES × MAX_INDEX_LINE_CHARS = 200 × 150 = 30,000 > MAX_INDEX_CHARS = 25,000, so an index can be over budget with every line legal. The third branch of lever keys only on hasOverlongEntry, so in that state it emits:
> WARNING: MEMORY.md is 29579 UTF-16 code units (limit: 25000) — too many index entries (200).
Only part of it was loaded. Dropped 31 of 200 entries: "Topic 169", "Topic 170", "Topic 171", +28 more.
No candidate entry exceeds the 150-unit line limit, so shortening entries cannot help — prune or merge entries.
Shortening those same 200 pointers to 124 units each keeps all 200 with no warning at all. A model that follows the notice merges or deletes topic files and permanently loses memories that trimming a hook would have preserved — while the writer's advice for the identical cumulative state says the opposite (indexer.ts: "Shorten topic-file paths or frontmatter names/descriptions, or merge/remove topic files"), and docs/design/memory-index-omission-notice.md promises the reader keeps its detail-moving advice whenever the candidate character budget binds. Here it binds, and the advice is withheld.
Witness (run against the unmodified built sources at 2fea5d21d0):
200 entries × 144 units = 29,579  -> kept 190, dropped 31, notice says "shortening entries cannot help"
same 200 entries × 124 units = 24,999 -> kept 200, dropped 0, no truncation warning
  shortened prompt has any truncation warning: false
  all 200 pointers retained in prompt: true
The failing state is also pinned as correct by an existing assertion — prompt.test.ts:445 expects toContain('shortening entries cannot help') for a 170-entry uniform over-budget index — so the suite is green on this defect.
Suggested fix: gate the "cannot help" branch on the character condition rather than on hasOverlongEntry. When candidates.join('\n').length > MAX_INDEX_CHARS and no candidate is overlong, advise shortening entries/descriptions and keep prune/merge as the fallback; reserve "cannot help" for the excluded-tail case the code comment already argues (an overlong entry past position 200).
Because prompt.test.ts:445 currently asserts the opposite for a 170-entry store, the fix has to update that assertion too; the two neighbouring branches' wording must stay as pinned by index-drop-notice.test.ts:430 (line-cap overflow with an overlong candidate) and index-drop-notice.test.ts:205 (no candidate overlong, the line cap is what binds).
Please add the case that pins it — 200 entries that are each legal but collectively over budget, asserting the prompt no longer contains shortening entries cannot help — and confirm it by removing the new branch and watching that test go red.
中文说明
[Critical] R2-2:当每个条目都在 150 单元单行上限之内、但合计超过 25,000 单元字符预算时,读取侧的杠杆却告诉模型「shortening entries cannot help(缩短条目无济于事)」——而缩短条目恰恰是该状态下唯一不损失记忆的补救方式。
因为 200 × 150 = 30,000 > 25,000,索引可以在每一行都合法的情况下超出预算。lever 的第三个分支只依据 hasOverlongEntry,于是在该状态下输出上文那段「too many index entries (200) … shortening entries cannot help — prune or merge entries.」。
把同样 200 条指针缩短到每行 124 单元,则 200 条全部保留、没有任何警告。照此警告行事的模型会合并或删除主题文件,永久丢失本可通过缩短 hook 保留的记忆;而写入侧对同一累计状态给出的建议恰好相反(indexer.ts:「Shorten topic-file paths or frontmatter names/descriptions, or merge/remove topic files」),设计文档也承诺「候选字符预算真正构成限制时」保留「移出细节」的建议——这里它确实构成限制,建议却被抹掉了。
见证见上方英文部分的实测输出(当前源码:29,579 单元 → 保留 190、丢弃 31,并输出「无济于事」;缩短到 24,999 单元 → 保留 200、无任何截断警告)。此外 prompt.test.ts:445 目前用 toContain('shortening entries cannot help') 把这个错误状态固定为「正确」,因此测试是绿的。
修复建议:把「无济于事」分支改为按字符条件判断,而不是按 hasOverlongEntry。当 candidates.join('\n').length > MAX_INDEX_CHARS 且没有超长候选时,建议缩短条目/描述,把合并或删除留作后备;仅在代码注释已论证的「被排除尾部」情形(第 200 条之后存在超长条目)才保留「无济于事」。
由于 prompt.test.ts:445 目前断言相反内容(170 条同长度超预算索引),修复时须一并更新;相邻两个分支的措辞分别由 index-drop-notice.test.ts:430(行数上限溢出且存在超长候选)与 index-drop-notice.test.ts:205(无超长候选、真正受限的是行数上限)固定。
请补上固定该行为的用例——200 条各自合法但合计超预算,断言提示词不再包含 shortening entries cannot help——并移除新分支确认该测试变红。
— deepseek-v4.1-flash-1017 via Qwen Code /review (v0.26.3)
| const hasWriterNotice = | ||
| noticeStart !== -1 && | ||
| trimmed.length - noticeStart <= 1024 && |
There was a problem hiding this comment.
[Suggestion] R2-3: The writer↔reader notice contract (the writer's whole notice must fit the reader's 1024-unit exemption) is enforced nowhere: 1024 is a bare literal here, index-budget.ts exports no matching bound, assembleIndex applies no clamp — and the one bound test ("keeps the largest two-set name sample inside the reader notice bound") builds short-path docs, so hasOverlongEntry stays false and the ~200-unit long lever is never emitted: the fixture measures 805 against a real writer maximum of 912. This round's fix made the margin worse — the rewritten budgetLever grew from ~128 to ~200 units, cutting the slack to ~112 — and round 1's own review body disclosed this exact measurement as an unfinished budget gap.
Executed boundary: padding the real maximal notice to 1021 units keeps it verbatim; at 1086 hasWriterNotice flips false — the notice is re-budgeted as entries (near a 25,000-unit body it can evict a real memory entry to make room for the writer's own warning) and the reader substitutes "Only part of it was loaded." with no counts or names: issue 14877 returns silently, in the worst-overbudget case where the diagnostics matter most, with every test green. Any future edit lengthening a lever or reason, or raising MAX_NAMED_DROPPED_ENTRIES from 3, crosses the line undetected.
Witness (probe + sweep):
'1024' in the memory module: prompt.ts:175 (bare literal) + 5 test sites; no writer-side bound/clamp
real maximal notice (60-unit names in BOTH sets, overlong candidates, both reasons, scanLever): 912 units
bound-test fixture: max retained line 146 < 150 -> long lever never emitted -> 805 units
padding arms: 1021 retained verbatim | 1086 notice LOST, reader says 'Only part of it was loaded.'
hard boundary: tail=1024 exempt | tail=1025 not
Export the bound from index-budget.ts (e.g. MAX_INDEX_NOTICE_CHARS = 1024), use it in hasWriterNotice, and extend the bound test to build a genuinely maximal notice (long percent-encoded paths forcing hasOverlongEntry true AND both omission sets) asserting notice.length ≤ the shared constant. The fix must respect MAX_NAMED_DROPPED_ENTRIES = 3 / MAX_DROPPED_ENTRY_NAME_CHARS = 60 (index-budget.ts), which keep each name sample ≤190 units, and the constant must not rise so far that the "does not exempt unbounded handwritten warning-like text" cases (a 25,000-unit tail) start being exempted. Please ask for the mutation that proves it: growing either lever text by >100 units must turn the extended bound test red — today that edit ships green.
中文说明
写入侧↔读取侧的警告契约(写入侧整段警告必须落在读取侧 1024 单元豁免内)没有任何强制点:1024 是此处的裸字面量,index-budget.ts 没有对应常量,assembleIndex 也不做 clamp;唯一的边界测试(「keeps the largest two-set name sample inside the reader notice bound」)用短路径文档构造,hasOverlongEntry 恒为 false,~200 单元的长杠杆根本不会被选中——夹具实测 805,而写入侧真实最大值为 912。本轮修复让余量进一步收窄:重写后的 budgetLever 从 ~128 单元增长到 ~200 单元,余量只剩 ~112;第 1 轮的评审正文曾把这项测量披露为未完成的预算缺口。
实测边界:把真实最大警告填充到 1021 单元 → 原样保留;1086 → hasWriterNotice 翻为 false,警告被重新当作条目参与预算(正文接近 25,000 单元时,写入侧自己的警告会挤掉一条真实记忆条目),读取侧只剩「Only part of it was loaded.」,没有计数也没有名称——issue 14877 在最需要诊断的场景静默回归,且所有测试保持绿色。今后任何加长杠杆/原因文本、或把 MAX_NAMED_DROPPED_ENTRIES 从 3 调大的修改,都会在无察觉的情况下越线。
见证(探针+扫描):内存模块中 '1024' 仅出现于 prompt.ts:175(裸字面量)与 5 处测试;写入侧无边界/无 clamp。真实最大警告(两个集合都用 60 单元名称、含超长候选、双原因、scanLever)= 912 单元;边界测试夹具:最长保留行 146 < 150 → 长杠杆未触发 → 805 单元。填充实验:1021 保留 / 1086 丢失(读取侧只剩 'Only part of it was loaded.');硬边界:1024 豁免、1025 不豁免。
修复:在 index-budget.ts 导出共享常量(如 MAX_INDEX_NOTICE_CHARS = 1024),hasWriterNotice 使用它,并把边界测试扩展为真实最大警告(长百分号编码路径迫使 hasOverlongEntry 为 true,且两个 omission 集合同时存在),断言 notice.length ≤ 共享常量。约束:MAX_NAMED_DROPPED_ENTRIES = 3 与 MAX_DROPPED_ENTRY_NAME_CHARS = 60(index-budget.ts)保证每个名称样本 ≤190 单元;常量也不得抬高到让「does not exempt unbounded handwritten warning-like text」用例(25,000 单元尾部)开始被豁免。请用变异验证:任一杠杆文本增长 >100 单元时,扩展后的边界测试必须变红——今天这样的修改会全绿通过。
— qwen3.8-max via Qwen Code /review (v0.26.0)
There was a problem hiding this comment.
[Suggestion] R2-3: still stands — the writer↔reader notice contract (the writer's whole notice must fit the reader's 1024-unit exemption) is still enforced nowhere: 1024 remains a bare literal here, index-budget.ts exports no matching bound, and assembleIndex applies no clamp. This round's audit re-measured the maximum reachable writer notice by executing the real builders over adversarial inputs (both name sets at the 60-unit cap, both reason clauses, the ~200-unit overlong lever, the scan lever, CJK/astral titles): 857–926 units depending on composition — inside the bound today, but still ~100 units of unnamed headroom, and the one bound test still never builds the maximal notice (its fixture yields the shorter count lever and measures ~805–849). The exemption boundary was also re-pinned empirically this round: exactly 1024 exempt, 1025 budgeted. prompt.ts and index-budget.ts are unchanged since round 2. The author tracks the follow-up in issue 15277.
Witness:
round-3 audit at head 1d595e2f (real builders, adversarial inputs): worst-case notice 857 UTF-16 units;
exemption boundary fuzzed: tail=1024 exempt | tail=1025 budgeted;
'1024' in the memory module: prompt.ts:175 (bare literal) + test sites only — no writer-side bound/clamp.
The original ask is unchanged: export the bound from index-budget.ts (e.g. MAX_INDEX_NOTICE_CHARS = 1024), use it in hasWriterNotice, and extend the bound test to a genuinely maximal notice (overlong lever + both omission sets + 60-unit names) asserting notice.length ≤ the shared constant; the proving mutation — growing either lever text by >100 units — must red the extended test, which today ships green.
中文说明
仍然成立——写入侧↔读取侧的警告契约(写入侧整段警告必须落在读取侧 1024 单元豁免内)仍然没有任何强制点:1024 仍是此处的裸字面量,index-budget.ts 没有对应常量,assembleIndex 也不做 clamp。本轮审计用真实构建器对对抗性输入(两个名称集合都取 60 单元上限、双原因子句、~200 单元的超长杠杆、扫描杠杆、CJK/星际平面标题)重新实测了可达的最大写入侧警告:按组合为 857–926 单元——今天在界内,但仍有 ~100 单元的未命名余量,而唯一的边界测试依然没有构造最大警告(其夹具产生较短的条数杠杆,实测 ~805–849)。本轮还再次实测了豁免边界:恰好 1024 豁免、1025 计入预算。prompt.ts 与 index-budget.ts 自第 2 轮以来未变。作者已将后续工作记录在 issue 15277。
(见证见上方英文部分。)
原修复要求不变:在 index-budget.ts 导出该上限(如 MAX_INDEX_NOTICE_CHARS = 1024),在 hasWriterNotice 中使用它,并把边界测试扩展为真正的最大警告(超长杠杆 + 两个 omission 集合 + 60 单元名称),断言 notice.length ≤ 共享常量;证明性变异——把任一杠杆文本加长 >100 单元——必须使扩展后的测试变红,而今天这样的修改会全绿通过。
— qwen3.8-max via Qwen Code /review (v0.26.0)
There was a problem hiding this comment.
[Suggestion] R2-3: still stands — the writer↔reader notice contract (the writer's whole notice must fit the reader's 1024-unit exemption) is enforced nowhere: 1024 is a bare literal here, index-budget.ts exports no matching bound next to MAX_INDEX_LINE_CHARS / MAX_INDEX_LINES / MAX_INDEX_CHARS / MAX_NAMED_DROPPED_ENTRIES / MAX_DROPPED_ENTRY_NAME_CHARS, assembleIndex has no production-side check against it, and five more bare literals sit in index-drop-notice.test.ts (:216, :247, :426, :448, :539).
The writer's notice is built from six independently growable pieces; this round's auditors measured the worst case at ~886-947 units against the 1024 gate (~80-140 units of slack), and the pinning test exercises the count lever, not the ~76-unit-longer overlong lever combined with both reason clauses. Raising MAX_NAMED_DROPPED_ENTRIES 3→4 (+128 units), lengthening a lever sentence, or adding one clause flips hasWriterNotice to false — the notice is re-budgeted as an ordinary entry and dropped from exactly the over-budget indexes it exists for, silently reintroducing issue #14877 with no test red at the configuration that overflows.
Witness:
git grep '1024' at head 12696e61ce:
  prompt.ts:175    trimmed.length - noticeStart <= 1024 &&     <- only production hit
  index-budget.ts  (no export; grep silent)
maximal-notice probe (this round's auditors): 886 units <= 1024 - the bound holds today,
unenforced; the count-lever-only pinning test measures ~846
Suggested fix: export the bound next to the notice prefixes (e.g. export const MAX_WRITER_NOTICE_CHARS = 1024; in index-budget.ts), use it here in place of the literal, replace the five test literals with it, and add a maximal-configuration writer-side assertion (overlong lever + both three-name samples at the 60-unit cap + scan lever).
The reader's window is inclusive (<= 1024 here) while two writer-side assertions use the strict form toBeLessThan(1024) (index-drop-notice.test.ts:247, :426) — a shared constant must keep the inclusive comparison at this read site, or those two tests change meaning.
Please pin the bound and prove it by mutation: restate the maximal-notice case against the shared constant and add the overlong-lever maximal configuration — lowering the constant below the fixture's notice length must turn the case red.
中文说明
仍然存在——写入↔读取的警告契约(写入侧整段警告必须放得进读取侧 1024 单元豁免)在任何地方都没有强制:1024 在这里是裸字面量,index-budget.ts 在 MAX_INDEX_LINE_CHARS / MAX_INDEX_LINES / MAX_INDEX_CHARS / MAX_NAMED_DROPPED_ENTRIES / MAX_DROPPED_ENTRY_NAME_CHARS 旁没有导出对应上界,assembleIndex 没有生产侧检查,index-drop-notice.test.ts 里还有五个裸字面量(:216、:247、:426、:448、:539)。
写入侧警告由六个可独立增长的部分拼成;本轮审计实测最坏情况约 886-947 单元,对 1024 门槛只剩约 80-140 单元余量,而固定该界的测试走的是条数杠杆,不是多出约 76 单元的超长杠杆加双原因从句的组合。把 MAX_NAMED_DROPPED_ENTRIES 从 3 提到 4(+128 单元)、给杠杆加一句话、或增加一个从句,都会让 hasWriterNotice 变 false——警告随即被当作普通条目参与预算,恰好在它存在的意义所在的超预算索引上被丢弃,无声地重新引入 issue #14877,且溢出的那个配置没有任何测试变红。
见证见上方英文部分(git grep 与最大警告探针)。
修复建议:把上界导出到警告前缀旁(如 index-budget.ts 中 export const MAX_WRITER_NOTICE_CHARS = 1024;),此处以常量替换字面量,五个测试字面量一并替换,并新增写入侧最大配置断言(超长杠杆 + 两组 60 单元上限的三名字样本 + scan 杠杆)。
读取侧窗口是闭区间(此处 <= 1024),而两个写入侧断言用严格形式 toBeLessThan(1024)(index-drop-notice.test.ts:247、:426)——共享常量必须保持读取处的闭区间比较,否则这两个测试的含义会变。
请固定该上界并用变异验证:把最大警告用例改为对共享常量断言,并补上超长杠杆的最大配置——把常量降到 fixture 警告长度以下必须使用例变红。
— qwen3.8-max via Qwen Code /review (v0.26.1)
| return scanAutoMemoryDocumentsFromRoot(root, { scope, uncapped: true }); | ||
| } | ||
|
|
||
| export async function scanAutoMemoryIndexDocumentsFromRoot( |
There was a problem hiding this comment.
[Suggestion] R2-4: The scan swap — completed by this round's rewiring of the last caller (the R1-6 fix moved rebuildAutoMemoryIndexAtRoot onto the new helper) — leaves scanAllAutoMemoryTopicDocumentsFromRoot (structured-scan.ts:613) with zero callers anywhere: no production site, no test, exported directly above the helper that replaced it. Its sibling orphan scanTeamAutoMemoryTopicDocuments (:873) is tracked in the still-standing R1-7 thread.
A contributor wiring the next rebuild or team-memory path greps for a scan helper, finds the scope-named function reading as canonical, and wires it — silently losing the omitted-tail diagnostics this PR exists to add and reproducing issue 14877's defect with no type error and no failing test. The round-1 retention rationale for the sibling ("the package has wildcard subpath exports") was checked at this head and does not cover these modules: packages/core/package.json does carry "./*": "./dist/src/*" and packages/cli really imports through it (memory/refresh.js, memory/paths.js, memory/request-context.js) — but nothing anywhere imports memory/structured-scan.js or memory/scan.js, the core barrel exports neither, and the package is "private": true. These are internal dead code, not a published contract.
Witness (sweep):
ripgrep (worktree, excl. dist):
  scanAllAutoMemoryTopicDocumentsFromRoot -> 1 hit, its own definition (zero callers, zero tests)
  scanTeamAutoMemoryTopicDocuments -> 2 hits, both in structured-scan.test.ts (:26, :808)
  forget.ts:145 calls scanAllAutoMemoryTopicDocuments (no FromRoot) — a different, still-live function
Delete scanAllAutoMemoryTopicDocumentsFromRoot (with the Team wrapper per R1-7, dropping the dead-wrapper assertion at structured-scan.test.ts:808-810 — the live-path assertion this PR adds at :805-807 pins the same guard), or re-express both as thin wrappers over scanAutoMemoryIndexDocumentsFromRoot(...).docs so no diagnostics-free implementation survives beside the live one. Do not delete the still-live siblings: scanAutoMemoryTopicDocuments (remember.ts:127, dreamAgentPlanner.ts:167, status.ts:65, extractionAgentPlanner.ts:150) and scanUserAutoMemoryTopicDocuments (remember.ts:98,133, user-dream.ts:171, user-dream-agent-planner.ts:100, extractionAgentPlanner.ts:151).
中文说明
扫描替换——在本轮修复把最后一个调用方改接新助手(R1-6 修复将 rebuildAutoMemoryIndexAtRoot 接到 scanAutoMemoryIndexDocumentsFromRoot)之后——使 scanAllAutoMemoryTopicDocumentsFromRoot(structured-scan.ts:613)不再有任何调用方:生产代码 0 处、测试 0 处,却仍以导出函数形式紧挨着取代它的助手。姊妹孤儿 scanTeamAutoMemoryTopicDocuments(:873)在仍然成立的 R1-7 线程中跟踪。
代价:下一位贡献者 grep 扫描助手时,会找到这个按作用域命名、看似规范的函数并接线——静默丢掉本 PR 要加的 omitted 尾部诊断,复刻 issue 14877 的缺陷,且没有类型错误或失败测试。第 1 轮对同类孤儿的保留理由(「包有 wildcard subpath exports」)本轮已在当前 head 核实,且不覆盖这两个模块:packages/core/package.json 确有 "./*": "./dist/src/*",packages/cli 也确实经它导入 memory/refresh.js、memory/paths.js、memory/request-context.js——但没有任何文件导入 memory/structured-scan.js 或 memory/scan.js,core barrel 也不导出,且包为 "private": true。这是内部死代码,不是公开契约。
见证(全仓扫描,排除 dist):scanAllAutoMemoryTopicDocumentsFromRoot → 1 处命中,即自身定义(0 调用方、0 测试);scanTeamAutoMemoryTopicDocuments → 2 处命中,均在 structured-scan.test.ts(:26、:808);forget.ts:145 调用的是 scanAllAutoMemoryTopicDocuments(无 FromRoot)——另一个仍在使用的函数。
修复:删除 scanAllAutoMemoryTopicDocumentsFromRoot(连同 R1-7 的 Team 包装与 structured-scan.test.ts:808-810 的死包装断言——本 PR 新增的 :805-807 活路径断言固定同一保护),或把两者改写为 scanAutoMemoryIndexDocumentsFromRoot(...).docs 的薄包装,使无诊断实现不再与活实现并存。约束:不要删除仍在使用的姊妹函数 scanAutoMemoryTopicDocuments(remember.ts:127、dreamAgentPlanner.ts:167、status.ts:65、extractionAgentPlanner.ts:150)与 scanUserAutoMemoryTopicDocuments(remember.ts:98,133、user-dream.ts:171、user-dream-agent-planner.ts:100、extractionAgentPlanner.ts:151)。
— qwen3.8-max via Qwen Code /review (v0.26.0)
There was a problem hiding this comment.
[Suggestion] R2-4: still stands — scanAllAutoMemoryTopicDocumentsFromRoot (structured-scan.ts:613) still has zero callers anywhere: no production site, no test, exported directly above the helper that replaced it. structured-scan.ts is unchanged since round 2. The author tracks the follow-up in issue 15277.
Witness:
round-3 git grep at head 1d595e2f (whole tree, excl. dist):
  scanAllAutoMemoryTopicDocumentsFromRoot -> 1 hit: its own `export async function` line.
(forget.ts:145 calls scanAllAutoMemoryTopicDocuments — a different, still-live function)
The original ask is unchanged: delete it (no callers to migrate), or re-express both orphans as thin wrappers over scanAutoMemoryIndexDocumentsFromRoot(...).docs so no diagnostics-free implementation survives beside the live one; keep the still-live siblings scanAutoMemoryTopicDocuments and scanUserAutoMemoryTopicDocuments, and keep the live-path symlink assertion this PR adds at structured-scan.test.ts:805-807 green.
中文说明
仍然成立——scanAllAutoMemoryTopicDocumentsFromRoot(structured-scan.ts:613)仍然没有任何调用方:生产代码 0 处、测试 0 处,却以导出函数形式紧挨着取代它的助手。structured-scan.ts 自第 2 轮以来未变。作者已将后续工作记录在 issue 15277。
(见证见上方英文部分。)
原修复要求不变:删除它(无调用方需迁移),或把两个孤儿改写为 scanAutoMemoryIndexDocumentsFromRoot(...).docs 的薄包装,使无诊断实现不再与活实现并存;保留仍在使用的姊妹函数 scanAutoMemoryTopicDocuments 与 scanUserAutoMemoryTopicDocuments,并保持本 PR 在 structured-scan.test.ts:805-807 新增的活路径符号链接断言绿色。
— qwen3.8-max via Qwen Code /review (v0.26.0)
There was a problem hiding this comment.
[Suggestion] R2-4: still stands — scanAllAutoMemoryTopicDocumentsFromRoot (structured-scan.ts:626) has zero callers anywhere after this diff's rewiring of rebuildAutoMemoryIndexAtRoot removed its last one; it sits directly above the new function that replaced it.
The name advertises "all documents, uncapped" — precisely the wrong helper for anyone adding a future rebuild path: choosing it silently reintroduces the bug this PR fixes (the index would trim at 200 lines with no omitted tail computed, so no scan-cap notice), and no test would fail. It also ships in dist/ as unreachable code that reads as a supported entry point.
Witness:
git grep scanAllAutoMemoryTopicDocumentsFromRoot at head 12696e61ce (packages/**/*.ts, dist excluded):
  structured-scan.ts:626:export async function scanAllAutoMemoryTopicDocumentsFromRoot(
  <- exactly one hit: its own definition. packages/core/src/index.ts re-exports neither
     memory/scan.js nor memory/structured-scan.js.
Suggested fix: delete scanAllAutoMemoryTopicDocumentsFromRoot (structured-scan.ts:626-631); no call site or test needs updating. If it is kept deliberately for a caller outside this repo, say so in a one-line comment naming that caller.
packages/core/src/memory/scan.ts:7 is export * from './structured-scan.js' and other packages import core memory files by subpath (e.g. packages/cli/src/memory-import/service.ts:26), so a deletion is a public-API change rather than a private cleanup — confirm no external consumer first; and do not extend the deletion to the similarly named live scanners (scanAllAutoMemoryTopicDocuments, scanAutoMemoryTopicDocuments, scanUserAutoMemoryTopicDocuments have production callers at extractionAgentPlanner.ts:150-151, status.ts:65, user-dream.ts:171, remember.ts:98) — scanTeamAutoMemoryTopicDocuments is the separate R1-7 entry.
The fix is a deletion of an unreferenced export, so no new test pins it; structured-scan.test.ts and indexer.test.ts passing unchanged after the removal is the check.
中文说明
仍然存在——本 diff 重接 rebuildAutoMemoryIndexAtRoot 后,scanAllAutoMemoryTopicDocumentsFromRoot(structured-scan.ts:626)在全仓库零调用者,就放在取代它的新函数正上方。
函数名宣称「all documents, uncapped」——恰是未来新增重建路径最不该选的 helper:选它会无声重新引入本 PR 修复的 bug(索引在 200 行处裁剪、不计算 omitted 尾部,于是不出 scan-cap 警告),且不会有测试失败。它还会作为不可达代码进入 dist/,读起来像一个受支持的入口。
见证见上方英文部分(HEAD 上 git grep 仅一处命中即其自身定义;packages/core/src/index.ts 未再导出 memory/scan.js 或 memory/structured-scan.js)。
修复建议:删除 scanAllAutoMemoryTopicDocumentsFromRoot(structured-scan.ts:626-631);无调用点或测试需要更新。若确为仓库外调用者保留,请加一行注释点名该调用者。
约束:packages/core/src/memory/scan.ts:7 是 export * from './structured-scan.js',且其他包通过子路径导入 core memory 文件(如 packages/cli/src/memory-import/service.ts:26),因此删除属于公共 API 变更而非私有清理——先确认无外部消费者;也不要把删除扩大到同名的在用 scanner(scanAllAutoMemoryTopicDocuments、scanAutoMemoryTopicDocuments、scanUserAutoMemoryTopicDocuments 在 extractionAgentPlanner.ts:150-151、status.ts:65、user-dream.ts:171、remember.ts:98 有生产调用者)——scanTeamAutoMemoryTopicDocuments 是 R1-7 的独立条目。
修复是删除无引用导出,无新测试可固定;删除后 structured-scan.test.ts 与 indexer.test.ts 原样通过即为验证。
— qwen3.8-max via Qwen Code /review (v0.26.1)
There was a problem hiding this comment.
[Suggestion] R2-4: still standing from round 2. This diff's rewiring of rebuildAutoMemoryIndexAtRoot onto the new helper added here removed the last production caller of scanAllAutoMemoryTopicDocumentsFromRoot (structured-scan.ts:627), which now sits directly above the function that replaced it with zero references anywhere in the repository.
The reason this is worth more than a hygiene note is what that particular orphan does: it is the uncapped: true variant. A contributor wiring the next rebuild or arbitrary-root path greps for a scan helper, finds the scope-named function reading as canonical, and wires it — silently bypassing the 200-file cap and losing the omission diagnostics this PR exists to add, which reproduces issue 14877's defect with no type error and no failing test. The name says "all", which reads as the more complete option rather than as the one that deliberately skips the cap and its reporting.
Witness (exhaustive ripgrep over the whole worktree, production and tests, at head f76cabf67f):
scanAllAutoMemoryTopicDocumentsFromRoot:
  structured-scan.ts:627   <- its own definition, the ONLY match
  production callers: 0
  tests: 0
at merge base 1df5031e70: exactly one production caller (the arbitrary-root rebuild path)
packages/core/src/index.ts re-exports memory/scan.js or structured-scan.js: NO
Since neither symbol is re-exported from the package entry, removal is not a breaking change to consumers of @qwen-code/qwen-code-core.
Delete scanAllAutoMemoryTopicDocumentsFromRoot. scanAutoMemoryIndexDocumentsFromRoot is its capped, diagnostics-returning replacement and should be the only scan entry point a future caller can reach for by name. No test pins the deleted function, so nothing needs migrating; if you would rather keep an uncapped escape hatch for a future caller, make that explicit in the name and return the file_limit incomplete-scope signal alongside the documents, so the cap bypass cannot be silent.
中文说明
R2-4:第 2 轮提出、至今仍然存在。本 diff 把 rebuildAutoMemoryIndexAtRoot 改写到此处新增的辅助函数上,移除了 scanAllAutoMemoryTopicDocumentsFromRoot(structured-scan.ts:627)最后一个生产调用方;它现在正好位于取代它的那个函数上方,而整个仓库中已无任何引用。
这不仅仅是代码整洁问题的原因在于这个孤儿函数的性质:它是 uncapped: true 的变体。将来负责下一条重建路径或任意根路径的贡献者会搜索扫描辅助函数,看到这个以作用域命名、读起来像是规范实现的函数并接上它——从而静默绕过 200 文件上限、丢失本 PR 存在的意义所要提供的遗漏诊断,在没有任何类型错误、也没有任何测试失败的情况下重现 issue 14877 的缺陷。函数名里的「All」读起来像是更完整的选项,而不是「刻意跳过上限及其上报」的那一个。
见证(在 head f76cabf67f 对整个工作树做穷尽 ripgrep,含生产代码与测试)见上方英文部分:scanAllAutoMemoryTopicDocumentsFromRoot 仅有自身定义这一处匹配,生产调用方 0、测试 0;在合并基线 1df5031e70 上恰有一个生产调用方(任意根重建路径);packages/core/src/index.ts 未再导出 memory/scan.js 或 structured-scan.js,因此删除它不构成对 @qwen-code/qwen-code-core 使用者的破坏性变更。
修复:删除 scanAllAutoMemoryTopicDocumentsFromRoot。scanAutoMemoryIndexDocumentsFromRoot 是它的带上限、会返回诊断信息的替代者,应当成为将来调用方按名字唯一能找到的扫描入口。没有任何测试固定被删除的函数,因此无需迁移;如果你更愿意为将来的调用方保留一个不设上限的出口,请在命名上明确表达这一点,并让它连同文档一起返回 file_limit 的 incomplete-scope 信号,使绕过上限这件事无法静默发生。
— qwen3.8-max via Qwen Code /review (v0.26.1)
| if (lines.length > MAX_INDEX_LINES) { | ||
| reasons.push(`${lines.length} entries (limit: ${MAX_INDEX_LINES})`); | ||
| } |
There was a problem hiding this comment.
[Suggestion] R2-5: After this diff — completed by this round's rewiring of the fourth entry point — the writer's entry-count reason is unreachable from every production rebuild path: all four rebuilds source docs from scanAutoMemoryIndexDocumentsFromRoot, which slices to MAX_SCANNED_MEMORY_FILES (200, structured-scan.ts:36 — a scan-cost knob), the same 200 as MAX_INDEX_LINES (index-budget.ts:8 — an index-size knob), and one doc is one line, so lines.length > MAX_INDEX_LINES can never be true in a written MEMORY.md. Nothing states or tests the cross-module coincidence, and the new JSDoc ("appending a notice when either cap trips") presents the line cap as a live trip condition.
Executed: raising MAX_SCANNED_MEMORY_FILES to 201–204 for scan-cost reasons silently revives the count reason with semantics no rebuild-path test pins — the only rebuild-path assertion (index-drop-notice.test.ts:536, not.toContain('205 entries (limit: 200)')) stays GREEN for caps 201–204 (the reason reads "201 entries (limit: 200)" etc.) and reds only at exactly 205; the two direct-call assertions (:89, :312) feed hand-made 205-doc arrays and never observe a production path. A maintainer debugging "why does my index never report an entry-count overflow" finds a branch that reads as live but is dead by coincidence.
Witness (probe):
ARM 1 production path (rebuildManagedAutoMemoryIndex, real 205-file store):
  scan docs 200 + omitted 5 | 200 entry lines | notice = scan-cap only
  contains 'entries (limit: 200)': false | MEMORY.md on disk === returned index
ARM 2 control (builder fed 205 docs directly, as unit tests do):
  contains '205 entries (limit: 200)': true
ARM 3 threshold sweep: cap=201 -> reason '201 entries (limit: 200)', :536 stays green
  cap=202/204 analogous (green) | cap=205 -> '205 entries (limit: 200)', :536 finally reds
Either drop the entry-count branch from assembleIndex (the scan-cap notice is the sole count-side diagnosis — it already reports "Dropped N of M topic files" for exactly this state), or keep it and make the coupling explicit: export MAX_SCANNED_MEMORY_FILES and assert MAX_SCANNED_MEMORY_FILES <= MAX_INDEX_LINES in a test, with a one-line comment on the branch naming why it is currently unreachable from a rebuild. The design doc fixes both numbers ("Keep the 200-file scan cap, 200-line index cap, 25,000 UTF-16-unit entry-body budget and 150-unit ordinary-entry priority"), and the reader's own line cap stays live regardless — a hand-edited or agent-written MEMORY.md can exceed 200 lines and prompt.ts counts it. Please ask for the mutation that proves the fix: with the enforce-the-coupling variant, the new assertion must go red when MAX_SCANNED_MEMORY_FILES is raised to 201 — measured, the existing :536 negative does NOT catch that; with the delete-the-branch variant, the two direct-call assertions (:89, :312) must be retargeted in the same change.
中文说明
本 diff 之后——由本轮把第四个入口改接 capped 扫描而完成——写入侧的条目数原因在所有生产重建路径上都不可达:四个重建都经 scanAutoMemoryIndexDocumentsFromRoot 取 docs,它切片到 MAX_SCANNED_MEMORY_FILES(200,structured-scan.ts:36,扫描成本旋钮),与 MAX_INDEX_LINES(200,index-budget.ts:8,索引大小旋钮)数值巧合相同;一个文档一行,因此写出的 MEMORY.md 永远不满足 lines.length > MAX_INDEX_LINES。这一跨模块巧合没有任何声明或测试,而新的 JSDoc(「appending a notice when either cap trips」)却把行数上限描述为活的触发条件。
实测:出于扫描成本把 MAX_SCANNED_MEMORY_FILES 提到 201-204,该原因会静默复活,且没有 rebuild 路径测试能抓到——唯一的 rebuild 路径断言(index-drop-notice.test.ts:536,not.toContain('205 entries (limit: 200)'))在 201-204 全部保持绿色(原因文本变成「201 entries (limit: 200)」等),到 205 才变红;两个直接调用断言(:89、:312)喂的是手工 205 文档数组,从不观察生产路径。调试「为什么我的索引从不报告条目数溢出」的维护者,会看到一个看似有效、实则因数值巧合而死亡的分支。
见证(探针):ARM 1 生产路径(rebuildManagedAutoMemoryIndex,真实 205 文件存储):扫描 docs 200 + omitted 5,写出 200 行,警告仅含 scan-cap,不含 'entries (limit: 200)',磁盘 MEMORY.md 与返回值逐字节一致;ARM 2 对照(直接喂 205 文档,即单元测试的方式):出现 '205 entries (limit: 200)';ARM 3 阈值扫描:cap=201 → 原因 '201 entries (limit: 200)' 且 :536 保持绿色,202/204 同理,cap=205 → :536 才变红。
修复:要么删掉 assembleIndex 的条目数分支(scan-cap 警告已是唯一的计数侧诊断——它已为此状态报告「Dropped N of M topic files」),要么保留并显式化耦合:导出 MAX_SCANNED_MEMORY_FILES,在测试中断言 MAX_SCANNED_MEMORY_FILES <= MAX_INDEX_LINES,并在分支上加一行注释说明它当前为何不可达。约束:设计文档固定了两个数字(「Keep the 200-file scan cap, 200-line index cap, 25,000 UTF-16-unit entry-body budget and 150-unit ordinary-entry priority」);读取侧自己的行数上限仍然有效——手改或 agent 写的 MEMORY.md 可超过 200 行,prompt.ts 会计数。请用变异验证:选择显式耦合方案时,新断言必须在 MAX_SCANNED_MEMORY_FILES 提到 201 时变红——实测既有的 :536 负断言抓不到;选择删除分支方案时,:89 与 :312 两个直接调用断言须在同一改动中重定向。
— qwen3.8-max via Qwen Code /review (v0.26.0)
There was a problem hiding this comment.
[Suggestion] R2-5: still stands — the writer's entry-count reason remains unreachable from every production rebuild path. All four rebuilds source docs from scanAutoMemoryIndexDocumentsFromRoot, which slices to MAX_SCANNED_MEMORY_FILES (200, structured-scan.ts:36 — a scan-cost knob), the same 200 as MAX_INDEX_LINES (index-budget.ts:8 — an index-size knob), and one doc is one line, so lines.length > MAX_INDEX_LINES can never be true in a written MEMORY.md — yet the JSDoc directly above still presents the line cap as a live trip condition ("appending a notice when either cap trips"). The R2-1 fix (hunks at 244-249, 252, 262) changed the causal predicate and lever selection but touched neither the count branch nor the cap coincidence. The author tracks the follow-up in issue 15277.
Witness:
read at head 1d595e2f: assembleIndex's `if (lines.length > MAX_INDEX_LINES)` branch intact;
MAX_SCANNED_MEMORY_FILES = 200 == MAX_INDEX_LINES = 200; no hunk in 5f93cd5d..HEAD touches
either constant or the branch's reachability.
The original ask is unchanged: either drop the entry-count branch (the scan-cap notice is the sole count-side diagnosis), or make the coupling explicit — export MAX_SCANNED_MEMORY_FILES, assert MAX_SCANNED_MEMORY_FILES <= MAX_INDEX_LINES in a test, and comment the branch; the proving mutation — raising the scan cap to 201 — must red the new assertion (measured: the existing :536 negative does not catch caps 201–204), and the delete-variant retargets the two direct-call assertions (:89, :312) in the same change.
中文说明
仍然成立——写入侧的条目数原因在所有生产重建路径上仍不可达。四个重建都经 scanAutoMemoryIndexDocumentsFromRoot 取 docs,它切片到 MAX_SCANNED_MEMORY_FILES(200,structured-scan.ts:36,扫描成本旋钮),与 MAX_INDEX_LINES(200,index-budget.ts:8,索引大小旋钮)数值巧合相同,一个文档一行,因此写出的 MEMORY.md 永远不满足 lines.length > MAX_INDEX_LINES——而其上方的 JSDoc 仍把行数上限描述为活的触发条件(「appending a notice when either cap trips」)。R2-1 修复(244-249、252、262 处的 hunk)改的是因果判定与杠杆选择,未触及该分支或上限巧合。作者已将后续工作记录在 issue 15277。
(见证见上方英文部分。)
原修复要求不变:要么删掉条目数分支(scan-cap 警告已是唯一的计数侧诊断),要么显式化耦合——导出 MAX_SCANNED_MEMORY_FILES,在测试中断言 MAX_SCANNED_MEMORY_FILES <= MAX_INDEX_LINES,并为该分支加注释;证明性变异——把扫描上限提到 201——必须使新断言变红(实测:既有的 :536 负断言抓不到 201–204),删除分支方案则须在同一改动中重定向 :89 与 :312 两个直接调用断言。
— qwen3.8-max via Qwen Code /review (v0.26.0)
There was a problem hiding this comment.
[Suggestion] R2-5: still stands — the writer's entry-count reason is unreachable from every production rebuild path: all four rebuilds now source docs from scanAutoMemoryIndexDocumentsFromRoot, which slices to MAX_SCANNED_MEMORY_FILES = 200 (structured-scan.ts:36, module-private), and MAX_INDEX_LINES = 200 (index-budget.ts:8), so lines.length > MAX_INDEX_LINES can never fire outside unit tests that call the builders directly.
The equality of two constants in different modules — one of them module-private — now decides which of the two writer notice prefixes is emitted (and therefore which prefix the reader at prompt.ts:169-170 has to recognise), and nothing records the coupling: a maintainer raising MAX_SCANNED_MEMORY_FILES to quiet the "does not list every topic file" notice silently flips the user-visible warning to a different prefix with different advice text, while the three tests pinning "205 entries (limit: 200)" stay green either way because they call the builder directly. This round's audit re-proved the unreachability from all four paths (docs are sliced to the scan cap before line building, so only char-only, scan-only and char+scan notices ship).
Witness:
git grep at head 12696e61ce:
  index-budget.ts:8:export const MAX_INDEX_LINES = 200;
  structured-scan.ts:36:const MAX_SCANNED_MEMORY_FILES = 200;   <- module-private
Suggested fix: either record the coupling where it is load-bearing — a comment at structured-scan.ts:36 stating it must stay ≤ MAX_INDEX_LINES or the writer's line-cap diagnostic goes dead — or drop the lines.length > MAX_INDEX_LINES reason from assembleIndex and let the scan-cap notice be the writer's only file-count diagnostic, keeping the line cap solely on the reader side where hand-written indexes can still exceed it.
The reader's line cap must stay: prompt.ts:184 const wasLineTruncated = lineCount > MAX_MANAGED_AUTO_MEMORY_INDEX_LINES; is pinned by prompt.test.ts:154 ("WARNING: MEMORY.md is 250 lines (limit: 200). Only part of it was loaded."); do not delete or lower MAX_INDEX_LINES.
Please pin whichever half you choose: index-drop-notice.test.ts "reports line-cap omissions with a bounded name sample" asserts toContain('205 entries (limit: 200)') — it goes red if the branch is removed, and must be deleted or re-pointed at the reader if the coupling comment is chosen instead.
中文说明
仍然存在——写入侧的条目数原因在一切生产重建路径上不可达:四个重建入口现在都从 scanAutoMemoryIndexDocumentsFromRoot 取文档,它按 MAX_SCANNED_MEMORY_FILES = 200(structured-scan.ts:36,模块私有)切片,而 MAX_INDEX_LINES = 200(index-budget.ts:8),所以 lines.length > MAX_INDEX_LINES 只在直接调用 builder 的单元测试里可能成立。
两个模块中两个常量的相等——其一是模块私有——现在决定发出哪一个写入侧警告前缀(从而决定读取侧 prompt.ts:169-170 必须识别哪个前缀),而这个耦合没有任何记录:维护者为消除「does not list every topic file」警告而调高 MAX_SCANNED_MEMORY_FILES 时,会无声把用户可见的警告翻转成另一个前缀、另一套建议文本,而固定「205 entries (limit: 200)」的三个测试两种情况下都绿(它们直接调用 builder)。本轮审计对四条路径重新证明了不可达性(文档在生成行之前已按扫描上限切片,因此只会发出 char-only、scan-only 和 char+scan 三种警告)。
见证见上方英文部分(两个常量的 git grep)。
修复建议:二选一——把耦合记录在承重点(structured-scan.ts:36 加注释:必须保持 ≤ MAX_INDEX_LINES,否则写入侧行数上限诊断失效),或从 assembleIndex 移除 lines.length > MAX_INDEX_LINES 原因,让 scan-cap 警告成为写入侧唯一的文件数诊断,把行数上限留给读取侧(手写索引仍可能超过)。
读取侧行数上限必须保留:prompt.ts:184 的 const wasLineTruncated = lineCount > MAX_MANAGED_AUTO_MEMORY_INDEX_LINES; 由 prompt.test.ts:154(「WARNING: MEMORY.md is 250 lines (limit: 200). Only part of it was loaded.」)固定;不要删除或调低 MAX_INDEX_LINES。
请固定你选择的那一半:index-drop-notice.test.ts『reports line-cap omissions with a bounded name sample』断言 toContain('205 entries (limit: 200)')——移除该分支它会变红;若选择加耦合注释,则应删除该用例或把它重新指向读取侧。
— qwen3.8-max via Qwen Code /review (v0.26.1)
qwen-code-review-bot
left a comment
qwen-code-review-bot
left a comment
There was a problem hiding this comment.
Reviewed. Suggestions are inline.
5 Suggestion-level finding(s) this review confirmed are already reported on this PR and are not repeated:
- writer/reader 1024-unit notice-contract enforcement (prompt.ts:175) — already reported (R2-3, comment 4351849960)
- orphaned scan wrappers (structured-scan.ts:613 / :873) — already reported (R2-4, comment 4351849968; R1-7, comment 4343381380)
- shape-based notice-exemption gate / forged single-paragraph tail incl. U+2028/U+2029/U+0085 (prompt.ts:174) — already reported (round-2 deferral list, review 5618749110)
- orphaned notice vocabulary and trimIndexToBudget zero-consumer exports (index-budget.ts:15 / :103) — already reported (round-2 deferral list, review 5618749110)
- scan-cap re-application outside the cap's owner / parallel omission channel (structured-scan.ts:634) — already reported (round-2 deferral list, review 5618749110)
Not explored to full depth (tool budget reached): "agent 3c": I did not execute npx vitest run src/memory/index-drop-notice.test.ts src/memory/prompt.test.ts src/memory/indexer.test.ts src/memory/structured-scan.test.ts ,….
Convergence: round 3 posted 8 inline comment(s), 2 of them reported for the first time; the previous round posted 7 (5 new). Findings keep coming back to the same files: packages/core/src/memory/prompt.ts (findings in round 2; 1 more now). A cluster that keeps producing siblings usually means the fixes are treating instances of a shared root cause — triaging that cause before the next round, or splitting an independent cluster into its own pull request, tends to end the loop faster than fixing them one at a time. No Critical finding is open on this round, so merging and moving the remaining Suggestion threads to a follow-up issue is available as an ending — a merged pull request cannot diverge further. (Observation only — nothing was withheld from this review because of this observation.)
中文说明
已审查。 建议见行内评论。
本轮确认的 5 条建议级发现已在 PR 上报告过,不再重复发布(列表见上方英文部分)。
未探索到全部深度(达到工具调用预算):"agent 3c":I did not execute npx vitest run src/memory/index-drop-notice.test.ts src/memory/prompt.test.ts src/memory/indexer.test.ts src/memory/structured-scan.test.ts ,…。
收敛情况:第 3 轮发布了 8 条行内评论,其中 2 条是首次提出;上一轮发布了 7 条(其中 5 条首次提出)。发现反复回到同一批文件:packages/core/src/memory/prompt.ts(第 2 轮已出过发现,本轮又有 1 条)。一个不断再生兄弟发现的簇,通常意味着逐条修复只在处理同一根因的实例——先定位并处理该根因,或把独立的簇拆成单独的 PR,通常比逐条修复更快结束循环。本轮没有未决的 Critical,因此"合入后把剩余 Suggestion 线程转到后续 issue"是一个可选的结束方式——已合入的 PR 不会继续发散。(仅为观察——本轮评审未因此扣留任何内容。)
— qwen3.8-max via Qwen Code /review (v0.26.0)
| const { content, dropped } = trimIndexToBudgetDetailed(entries); | ||
| const hasOverlongEntry = entries.some( | ||
| const candidates = entries.slice(0, MAX_MANAGED_AUTO_MEMORY_INDEX_LINES); | ||
| const hasOverlongEntry = candidates.some( |
There was a problem hiding this comment.
[Suggestion] R3-2: The reader still attributes a character-budget overflow to entry length on bare hasOverlongEntry — both in the reason clause below (prompt.ts:200-203, "index entries are too long") and in the first lever branch (:209-211, "Keep index entries to one line at most 150 UTF-16 code units") — even when trimming every candidate to 150 units still leaves the body over 25,000, i.e. when the advice provably cannot work. This round's R2-1 fix gave the writer the causal predicate (overlongEntriesCauseOverflow, indexer.ts:248-249); the reader's twin was not upgraded, so identical content now receives contradictory diagnoses from the two halves of one product: the writer says "too many index entries" while the reader says "index entries are too long". This is the mirror sibling of R2-2 — whose branch 3 claims "shortening entries cannot help" in exactly the state where shortening IS the remedy, while this branch-1/reason claims shortening-to-150 in exactly the state where it cannot rescue the budget — and one shared causal predicate fixes both, which is also the shared-builder direction R1-4 has been asking for. The state is reachable through a hand-edited or pre-PR MEMORY.md, the path the design doc explicitly keeps open ("The reader can also load handwritten entries").
Witness:
[probe against the real reader and writer at head 1d595e2f — same 200-entry overlong shape]
charCount: 40199 > 25000: true
ordinaryCharCount (every candidate cut to 150): 30199 > MAX_INDEX_CHARS: true   (length cannot be the cause)
READER: "… 40199 UTF-16 code units (limit: 25000) — index entries are too long. Only part of it was loaded.
         Dropped 76 of 200 entries: … Keep index entries to one line at most 150 UTF-16 code units;
         move detail into topic files. …"    entries surviving in prompt: 124 of 200
WRITER: "… 40089 UTF-16 code units (limit: 25000) — too many index entries. …
         Merge topic files or remove obsolete ones to reduce the index."
A user following the reader's lever shortens every entry to 150 — and remains 5,199 units over budget.
Extract the predicate once, next to the constants it uses — export function overlongEntriesCauseOverflow(candidates: readonly string[]): boolean in index-budget.ts, computing charCount > MAX_INDEX_CHARS && candidates.map(l => l.slice(0, MAX_INDEX_LINE_CHARS)).join('\n').length <= MAX_INDEX_CHARS — call it from assembleIndex in place of the inline computation, and in truncateManagedAutoMemoryIndex gate the reason's length clause and lever branch 1 on it instead of bare hasOverlongEntry; keep hasOverlongEntry only for branch 2's line-cap claim ("Shortening entries cannot reduce the line count"), and keep the reader's own "move detail into topic files" wording for the genuinely length-caused case.
Constraints the fix must keep: MAX_INDEX_LINE_CHARS = 150 and MAX_INDEX_CHARS = 25_000 (index-budget.ts:7,9); the design doc's rule in both languages (memory-index-omission-notice.md:17 / .zh-CN.md:17) that the reader retains its separate detail-moving advice when the candidate character budget actually binds; and the predicate must run over entries.slice(0, MAX_INDEX_LINES) so does not blame a reader entry already excluded by the line cap (asserts 'No candidate entry exceeds the 150-unit line limit') stays green. Fix witness: add a prompt.test.ts case — 200 candidates whose joined length exceeds 25,000 with at least one line over 150 units whose 150-unit truncation still exceeds 25,000 — asserting the prompt does NOT contain 'index entries are too long' or 'Keep index entries to one line at most', and DOES contain the prune/merge lever; reverting the gate to bare hasOverlongEntry must red it (the reader-side twin of the writer case keeps count advice when a dropped overlong candidate is not the cause).
中文说明
读取侧仍仅凭 hasOverlongEntry 把字符预算溢出归因于条目长度——下方原因子句(prompt.ts:200-203,「index entries are too long」)与杠杆第一分支(:209-211,「Keep index entries to one line at most 150 UTF-16 code units」)皆然——即使把每个候选截到 150 单元后正文仍超过 25,000,也就是该建议可证明无效的状态。本轮 R2-1 修复让写入侧改用因果判定 overlongEntriesCauseOverflow(indexer.ts:248-249),读取侧的孪生判定未同步升级,同一内容因此得到产品两个半边相互矛盾的诊断:写入侧说「too many index entries」,读取侧说「index entries are too long」。这是 R2-2 的镜像姊妹——R2-2 的第三分支在「缩短正是解法」的状态声称「缩短无用」,本条的第一分支/原因子句在「缩短到 150 也救不回预算」的状态建议缩短到 150——一个共享的因果判定可同时修复两者,这也正是 R1-4 一直要求的共享构建器方向。该状态经手改或旧版 MEMORY.md 可达——设计文档明确保留该路径(「读取侧也可能加载手写条目」)。
(见证见上方英文部分的探针输出。)
把判定提取一次、放在它使用的常量旁边——index-budget.ts 中 export function overlongEntriesCauseOverflow(candidates: readonly string[]): boolean,计算 charCount > MAX_INDEX_CHARS && candidates.map(l => l.slice(0, MAX_INDEX_LINE_CHARS)).join('\n').length <= MAX_INDEX_CHARS——在 assembleIndex 中替换内联计算,并在 truncateManagedAutoMemoryIndex 中用它(而非 bare hasOverlongEntry)门控原因子句与杠杆第一分支;hasOverlongEntry 只保留给第二分支的行数上限声明(「Shortening entries cannot reduce the line count」),真正的长度成因保留读取侧自己的「move detail into topic files」措辞。
修复必须尊重的约束:MAX_INDEX_LINE_CHARS = 150 与 MAX_INDEX_CHARS = 25_000(index-budget.ts:7,9);设计文档双语规则(memory-index-omission-notice.md:17 / .zh-CN.md:17)——候选字符预算真正 binding 时读取侧保留自己的 detail-moving 建议;判定必须在 entries.slice(0, MAX_INDEX_LINES) 上运行,使 does not blame a reader entry already excluded by the line cap(断言 'No candidate entry exceeds the 150-unit line limit')保持绿色。修复见证:在 prompt.test.ts 增加一个用例——200 个候选、join 后超过 25,000、至少一行超过 150 单元、截到 150 后仍超过 25,000——断言提示词不含 'index entries are too long' 与 'Keep index entries to one line at most',且包含 prune/merge 杠杆;把门控回退为 bare hasOverlongEntry 必须变红(它是写入侧用例 keeps count advice when a dropped overlong candidate is not the cause 的读取侧孪生)。
— qwen3.8-max via Qwen Code /review (v0.26.0)
There was a problem hiding this comment.
[Suggestion] R3-2: still stands — the reader attributes a character-budget overflow to entry length on bare hasOverlongEntry, both in the reason clause ("index entries are too long", prompt.ts:200-203) and in the first lever branch (:211-212), where the writer's causal predicate (indexer.ts:252-253, added by the R2-1 fix) would classify the identical state as count-caused. The length lever the reader hands out can be unpullable.
169 legal 150-unit entries plus one 600-unit entry: charCount = 26,119 > 25,000 and hasOverlongEntry = true, so the reader prints "index entries are too long" plus "Keep index entries to one line at most 150 UTF-16 code units; move detail into topic files" — advice that cannot work, since clipping all candidates to 150 still leaves 25,669 > 25,000. When the on-disk index carries a writer notice, prompt.ts:217 emits the retained writer notice AND the appended reader lever, so contradictory diagnoses ("too many index entries" vs "index entries are too long") sit in one system prompt.
Witness:
git grep at head 12696e61ce:
  prompt.ts:194  const hasOverlongEntry = candidates.some(
  prompt.ts:211  candidates.join('\n').length > MAX_INDEX_CHARS && hasOverlongEntry
  prompt.ts:213  : hasOverlongEntry
  indexer.ts:252 const overlongEntriesCauseOverflow =
  indexer.ts:253   charCount > MAX_INDEX_CHARS && ordinaryCharCount <= MAX_INDEX_CHARS;
Suggested fix: one causal predicate for both sides — see R1-4's shared builder in index-budget.ts (e.g. indexOverflowCause(candidates) implementing the writer's achievable-shortening test), consumed by both assembleIndex and truncateManagedAutoMemoryIndex for the reason clause and lever selection.
The reader must keep giving length advice when shortening genuinely helps: prompt.test.ts:449 ("keeps blaming entry length when an entry really does exceed the line limit") asserts toContain('index entries are too long') and the 150-unit lever for a single 27,000-unit entry — there shortening to 150 does fit, so the shared predicate must keep classifying that state as overlong-caused.
Please add the reader-mirror regression and prove it by mutation: a prompt.test.ts case with 169 entries of exactly 150 units plus one 600-unit entry asserting the result does NOT contain "Keep index entries to one line at most" and DOES contain "prune or merge entries" — red against the current bare-hasOverlongEntry condition.
中文说明
仍然存在——读取侧仅凭 hasOverlongEntry 就把字符预算溢出归因于条目长度,包括原因从句(「index entries are too long」,prompt.ts:200-203)和第一杠杆分支(:211-212);而写入侧的因果判据(indexer.ts:252-253,R2-1 修复引入)会把同一状态判为条数导致。读取侧发出的长度杠杆可能根本拉不动。
169 条合法的 150 单元条目加一条 600 单元条目:charCount = 26,119 > 25,000 且 hasOverlongEntry = true,读取侧输出「index entries are too long」加「Keep index entries to one line at most 150 UTF-16 code units; move detail into topic files」——该建议无法奏效,因为把所有候选裁到 150 仍剩 25,669 > 25,000。当磁盘索引带有写入侧警告时,prompt.ts:217 会同时输出保留的写入侧警告和追加的读取侧杠杆,于是「too many index entries」与「index entries are too long」两种矛盾诊断同处一个 system prompt。
见证见上方英文部分(HEAD 上的 git grep 输出)。
修复建议:两侧共用一个因果判据——见 R1-4 的共享 builder 方案(在 index-budget.ts 提供如 indexOverflowCause(candidates),实现写入侧的「可缩短性」测试),由 assembleIndex 与 truncateManagedAutoMemoryIndex 共同消费,用于原因从句与杠杆选择。
当缩短确实有效时,读取侧必须继续给长度建议:prompt.test.ts:449(『keeps blaming entry length when an entry really does exceed the line limit』)对单条 27,000 单元条目断言 toContain('index entries are too long') 与 150 单元杠杆——该状态下缩到 150 确实能放下,共享判据必须继续把它归为超长导致。
请补上读取侧镜像回归并用变异验证:prompt.test.ts 新用例,169 条恰好 150 单元加一条 600 单元,断言结果不含「Keep index entries to one line at most」且含「prune or merge entries」——对当前 bare-hasOverlongEntry 条件为红。
— qwen3.8-max via Qwen Code /review (v0.26.1)
There was a problem hiding this comment.
[Suggestion] R3-2: still standing from round 3. The reader attributes a character-budget overflow to entry length on bare hasOverlongEntry, both in the reason clause below (prompt.ts:199-208, "index entries are too long") and in the first lever branch (:212-213). This diff did narrow the first arm to candidates.join('\n').length > MAX_INDEX_CHARS && hasOverlongEntry, which is a real improvement, but in a character-only overflow with 200 or fewer lines that guard is equivalent to bare hasOverlongEntry — measured, it fired in both probes below — so the misattribution survives the narrowing.
Concretely: an index of 200 lines with exactly one overlong entry at 200 units, body 30,277. Shortening that one line to 150 still leaves 30,199, so the overlong entry cannot be the cause of the overflow. The reader nonetheless reports "index entries are too long" and prescribes "Keep index entries to one line at most 150 UTF-16 code units; move detail into topic files", while the writer in this same PR, for equivalent documents, reports "cumulative index entry length" and prescribes shortening topic-file paths or frontmatter names and descriptions. An agent following the reader's lever edits the one long entry, sees no change, and never tries the edit that would have worked.
Witness (probe against the real reader at head f76cabf67f; 200 lines, one overlong at 200 units, body 30,277, and 30,199 even with that line shortened to 150):
READER: "…30277 UTF-16 code units (limit: 25000) — index entries are too long…
         Keep index entries to one line at most 150 UTF-16 code units; move detail into topic files…"
WRITER (equivalent docs):
        "…30199 UTF-16 code units (limit: 25000) — cumulative index entry length…
         Shorten topic-file paths or frontmatter names/descriptions…"
narrowed first-arm guard (candidates.join('\n').length > MAX_INDEX_CHARS && hasOverlongEntry): fired in both probes
Apply the same causal gate the writer now uses at indexer.ts:253-254 — attribute length only when the overlong candidates' excess is what actually pushes the body past MAX_INDEX_CHARS (overlongEntriesCauseOverflow = charCount > MAX_INDEX_CHARS && ordinaryCharCount <= MAX_INDEX_CHARS) — and otherwise report cumulative length. This is the reader half of the shared-classifier collapse R1-4 asks for, and it is the part the author has deferred to #15368; reporting it here because it still stands on this PR's record and the two halves of one change now disagree in public.
Keep both existing pins green: index-drop-notice.test.ts:173-184 pins a 251-line index whose overflow comes only from an excluded 'x'.repeat(25_003) line 201, and prompt.test.ts:154 still pins the reader's own 'WARNING: MEMORY.md is 250 lines (limit: 200). Only part of it was loaded.' line-cap path. Please add a case with 200 legal lines plus one overlong line whose excess does not cause the overflow, asserting the prompt does not contain "index entries are too long" and does name cumulative length; reverting the gate must red it again.
中文说明
R3-2:第 3 轮提出、至今仍然存在。读取侧把字符预算溢出归因于条目长度,判据仍是裸的 hasOverlongEntry——既出现在下方的 reason 子句(prompt.ts:199-208,「index entries are too long」),也出现在第一个 lever 分支(:212-213)。本 diff 确实把第一个分支收窄为 candidates.join('\n').length > MAX_INDEX_CHARS && hasOverlongEntry,这是实质改进;但在行数不超过 200 的纯字符溢出中,该门控与裸 hasOverlongEntry 等价——实测在下面两个探针中都触发——因此误判在收窄之后依然存在。
具体场景:200 行索引,其中恰有一条 200 单元的超长条目,正文 30,277。把这一行缩短到 150 后仍有 30,199,所以该超长条目不可能是溢出的原因。读取侧却仍然报告「index entries are too long」,并建议「Keep index entries to one line at most 150 UTF-16 code units; move detail into topic files」;而同一 PR 的写入侧对等价文档报告「cumulative index entry length」,建议缩短主题文件路径或 frontmatter 名称与描述。照读取侧杠杆执行的 agent 会去改那条长条目,发现毫无变化,而始终没有尝试真正有效的那个编辑。
见证(针对 head f76cabf67f 真实读取侧的探针;200 行、一条 200 单元超长条目、正文 30,277,把该行缩短到 150 后仍为 30,199)见上方英文部分的 READER/WRITER 双臂输出,以及收窄后的第一分支门控在两个探针中均触发的实测结果。
修复:采用写入侧在 indexer.ts:253-254 已使用的同一因果门控——只有当超长候选的超出部分确实把正文推过 MAX_INDEX_CHARS 时才归因于长度(overlongEntriesCauseOverflow = charCount > MAX_INDEX_CHARS && ordinaryCharCount <= MAX_INDEX_CHARS),否则报告累计长度。这是 R1-4 所要求的共享分类器的读取侧一半,也是作者已放到 #15368 的部分;之所以在此报告,是因为它仍存在于本 PR 的记录上,而同一个改动的两半现在已经公开地互相矛盾。
请保持两个既有固定用例通过:index-drop-notice.test.ts:173-184 固定了溢出来自被排除的 'x'.repeat(25_003) 第 201 行的 251 行索引,prompt.test.ts:154 仍固定读取侧自身的 'WARNING: MEMORY.md is 250 lines (limit: 200). Only part of it was loaded.' 行数上限路径。请补一个用例:200 条合法行加一条超长行、且该行的超出部分并非溢出成因,断言 prompt 不含「index entries are too long」并给出累计长度的表述;回退该门控须使其再次变红。
— qwen3.8-max via Qwen Code /review (v0.26.1)
|
R2-1 is fixed. Reader advice is now covered separately in #15368 (item 1 of #15277), including R3-2’s 200-entry counterexample. I’m keeping the remaining Suggestions in #15277 until #14937 lands. Linux tests, lint/static and no-AK integration pass on this head. The web-shell job timed out installing Playwright’s system dependencies before any browser tests ran. Please rerun that job. |
|
Resolved the main conflict in Fresh Linux validation: frozen install, root build/bundle/typecheck, changed-file format/lint and full memory suite 1,157 passed / 2 skipped; CLI smoke and direct startup-closure check pass. Removing native-prefix forwarding fails 1 regression(s); restoring it gives 35 indexer tests passed / 1 skipped. Independent built-output verification passes six cases, including separate 32/200 entry and 207/407 topic-file omissions with all 167 native entries preserved. Independent review: C=0, new S=0. The description now records this exact head. Existing Suggestions stay in #15277; reader advice remains separate in #15368. New upstream CI is pending, and no live-provider/TUI coverage is claimed. |
|
I merged current main in |
|
Native CI is now green on |
qwen-code-review-bot
left a comment
qwen-code-review-bot
left a comment
There was a problem hiding this comment.
6 Suggestion-level finding(s) this review confirmed are already reported on this PR and are not repeated:
- orphaned scan/trim exports and notice vocabulary (structured-scan.ts:626, :886; index-budget.ts:113, :15) — already reported (R2-4, comment 4351849968; R1-7, comment 4343381380; round-2 deferral list, review 5618749110)
- writer↔reader 1024-unit notice contract unenforced (prompt.ts:173-176) — already reported (R2-3, comment 4351849960)
- writer/reader overflow-cause predicate divergence (prompt.ts:210-212; indexer.ts:248-254) — already reported (R1-4, comment 4343381355; R3-2, comment 4354055944)
- writer line-cap reason unreachable (indexer.ts:244-246) — already reported (R2-5, comment 4351849973)
- shape-based notice-exemption gate / forged single-paragraph tail (prompt.ts:173-177) — already reported (round-2 deferral list, review 5618749110)
- Scan limit prints retained-array size (indexer.ts:290-292) — already reported (round-2 deferral list, review 5618749110)
Deferred under the convergence posture (round 4, not a blocker) — recorded, not requested in this round:
packages/core/src/memory/index-budget.ts:15 — [probe] Legacy INDEX_TRUNCATION_WARNING is derived from the live prefix: a reword silently rewrites the legacy string while every legacy-recognition test asserts against the same derived constan…packages/core/src/memory/indexer.ts:232 — [probe] assembleIndex takes scanNotice and scanOmitted as two positional representations of one fact; a desynced future caller compiles clean and emits a false 'too large' headline with no remedypackages/core/src/memory/indexer.ts:264 — [probe] budgetLever's reasons.length === 0 guard is untested: deleting the empty arm survives 120/120 tests and puts index-body advice on scan-cap-only noticespackages/core/src/memory/prompt.ts:168 — [probe] lastIndexOf is unpinned against indexOf: an indexOf mutant survives 163/163 tests and breaks any store whose index body quotes the warning textpackages/core/src/memory/indexer.ts:287 — [probe] describeScanOmissions re-parses manufactured docIndexLine output: titles containing ']' print truncated ('Fix [core'), and the notice's sanitization is an untested side effect on the omitted…packages/core/src/memory/index-drop-notice.test.ts:105 — [probe] The Reviewer Test Plan's mixed-cap fixture (32 of 200 entries / 207 of 407 topic files) matches no shipped test; the plan's discriminating ratio is uncovered (the numbers are …packages/core/src/memory/indexer.ts:272 — [probe] Scan-cap remedy blames file count for omissions the imported/ demotion causes: acting on it for the named just-imported files changes nothing; only deleting native memories clears the notice
Convergence: round 4 posted 9 inline comment(s), 1 of them reported for the first time; the previous round posted 8 (2 new). Findings keep coming back to the same files: packages/core/src/memory/indexer.ts (findings in rounds 1, 2; 1 more now). A cluster that keeps producing siblings usually means the fixes are treating instances of a shared root cause — triaging that cause before the next round, or splitting an independent cluster into its own pull request, tends to end the loop faster than fixing them one at a time. (Observation only — nothing was withheld from this review because of this observation.)
中文说明
本轮确认的 6 条建议级发现已在 PR 上报告过,不再重复发布(列表见上方英文部分)。
收敛姿态下延后(第 4 轮,非阻断)——已记录,本轮不要求修改:共 7 条(原文未翻译,列表见上方英文部分)。
收敛情况:第 4 轮发布了 9 条行内评论,其中 1 条是首次提出;上一轮发布了 8 条(其中 2 条首次提出)。发现反复回到同一批文件:packages/core/src/memory/indexer.ts(第 1、2 轮已出过发现,本轮又有 1 条)。一个不断再生兄弟发现的簇,通常意味着逐条修复只在处理同一根因的实例——先定位并处理该根因,或把独立的簇拆成单独的 PR,通常比逐条修复更快结束循环。(仅为观察——本轮评审未因此扣留任何内容。)
— qwen3.8-max via Qwen Code /review (v0.26.1)
|
I fixed R4-1 and R3-1 in |
…ry-writer-advice-oct25
qwen-code-review-bot
left a comment
qwen-code-review-bot
left a comment
There was a problem hiding this comment.
Partially reviewed — gaps disclosed.
4 Suggestion-level finding(s) this review confirmed are already reported on this PR and are not repeated:
- R2-3 writer/reader 1024-unit notice contract unenforced (prompt.ts:176) — already reported (comment 4351849960)
- R1-4 writer's overflow diagnosis a hand-rolled twin of the reader's (indexer.ts:253) — already reported (comment 4343381355)
- R2-5 writer's entry-count reason unreachable from production paths (indexer.ts:245) — already reported (comment 4351849973)
- R5-3 notice scan total vs the status API census (indexer.ts:291) — already reported (round-2 deferral list, review 5618749110)
Not reviewed: build-and-test — Agent 7's test-efficacy probe never reached a validated baseline (harnessValidated: null; 0 mutants and 0 hunk probes ran, the probe baseline tripped the vitest globalSetup guard), so revert/mutant/hunk coverage is unmeasured rather than clean. The Step 4 verifier did run one successful mutation, which is what confirmed R5-2..
Not reviewed: build-and-test — Test (macos-latest, Node 22.x) and Test (windows-latest, Node 22.x) were skipped in CI and no local run covered those platforms, while this diff changes path handling in the memory scanner (encodeIndexPathTarget, relativePath segment matching).
Not explored to full depth (tool budget reached): "agent 6b": ESLint / npm run lint on the changed files (I verified typecheck only, so a lint-only violation such as filename or import-order rules would not have been cau….
Test Plan (not a blocker): 1158 passed — this review observed 38656, 2816, 1028, 2278, 650, 13256 passed.
Convergence: round 5 posted 6 inline comment(s), 2 of them reported for the first time; the previous round posted 9 (1 new). Findings keep coming back to the same files: packages/core/src/memory/prompt.ts (findings in rounds 2, 3; 1 more now). The rate of new findings is not falling. A cluster that keeps producing siblings usually means the fixes are treating instances of a shared root cause — triaging that cause before the next round, or splitting an independent cluster into its own pull request, tends to end the loop faster than fixing them one at a time. Batching the remaining fixes and verifying them before the next push, or dropping this PR's reviews to --severity-floor critical, keeps the loop from re-deriving the same set. (Observation only — nothing was withheld from this review because of this observation.)
中文说明
仅完成部分审查,审查缺口已披露。
本轮确认的 4 条建议级发现已在 PR 上报告过,不再重复发布(列表见上方英文部分)。
未审查(原文为英文):build-and-test — Agent 7's test-efficacy probe never reached a validated baseline (harnessValidated: null; 0 mutants and 0 hunk probes ran, the probe baseline tripped the vitest globalSetup guard), so revert/mutant/hunk coverage is unmeasured rather than clean. The Step 4 verifier did run one successful mutation, which is what confirmed R5-2..
未审查(原文为英文):build-and-test — Test (macos-latest, Node 22.x) and Test (windows-latest, Node 22.x) were skipped in CI and no local run covered those platforms, while this diff changes path handling in the memory scanner (encodeIndexPathTarget, relativePath segment matching).
未探索到全部深度(达到工具调用预算):"agent 6b":ESLint / npm run lint on the changed files (I verified typecheck only, so a lint-only violation such as filename or import-order rules would not have been cau…。
Test Plan(非阻断):1158 passed — this review observed 38656, 2816, 1028, 2278, 650, 13256 passed。
收敛情况:第 5 轮发布了 6 条行内评论,其中 2 条是首次提出;上一轮发布了 9 条(其中 1 条首次提出)。发现反复回到同一批文件:packages/core/src/memory/prompt.ts(第 2、3 轮已出过发现,本轮又有 1 条)。新发现的产出速度没有下降。一个不断再生兄弟发现的簇,通常意味着逐条修复只在处理同一根因的实例——先定位并处理该根因,或把独立的簇拆成单独的 PR,通常比逐条修复更快结束循环。把剩余修复攒成一批、验证后再推送,或将本 PR 的评审降到 --severity-floor critical,可以避免循环反复推导同一组发现。(仅为观察——本轮评审未因此扣留任何内容。)
— qwen3.8-max via Qwen Code /review (v0.26.1)
| ...MEMORY_FRONTMATTER_EXAMPLE, | ||
| '', | ||
| '**Step 2** — add a pointer to that file in the `MEMORY.md` index that lives in the SAME directory you wrote to (each directory has its own index — never cross-reference). Each entry should be one line, under ~150 characters: `- [Title](file.md) — one-line hook`. It has no frontmatter. Never write memory content directly into `MEMORY.md`.', | ||
| '**Step 2** — add a pointer to that file in the `MEMORY.md` index that lives in the SAME directory you wrote to (each directory has its own index — never cross-reference). Each entry should be one line, under ~150 characters: `- [Title](file.md) — one-line hook`. It has no frontmatter. If a trailing warning is present, insert new pointers above it so it stays last. Never write memory content directly into `MEMORY.md`.', |
There was a problem hiding this comment.
[Suggestion] R5-1: The Step-2 save instruction this round added here (and at the twin site :402) is the only thing that enforces the invariant the reader's notice exemption depends on, and it is incomplete in two ways. First, its only stated success criterion is "so it stays last", but the exemption at prompt.ts:174-177 requires a blank line before the notice — it matches '\n\n> WARNING: …' and then rejects anything containing a further newline. Two of the three literal ways to insert a pointer above the warning keep the warning last and still destroy the exemption. Second, the boundary was added to two of the three sibling Step-2 index-save instructions; extractionAgentPlanner.ts:219 and dreamAgentPlanner.ts:100, which also teach an agent to hand-edit MEMORY.md, never received it.
A compliant agent performing Step 2 by string-anchored insertion (old_string = the > WARNING: line, new_string = the new pointer, a single newline, then that same line) satisfies the instruction exactly as written — the warning is still the file's final line — yet hasWriterNotice goes false. The notice is then budgeted as an ordinary entry and dropped, and the reader reports the writer's own notice back as a dropped index entry named after itself, inflates the line count, and on the character-budget variant flips the cause to "index entries are too long" and issues the "keep entries to one line at most 150 UTF-16 code units" lever, blaming the writer's own 361-unit notice as the overlong entry. That is the attribution this PR's design doc forbids for cumulative-length pressure.
On the missing sibling: the refutation that a rebuild always regenerates MEMORY.md afterwards is incomplete. extract.ts:222-236 sits inside the if (agentResult.touchedTopics.length > 0) gate at extract.ts:204, and touchedTopicsFromFilePaths (extractionAgentPlanner.ts:266-296) adds a topic only when the first path segment under the memory root is user, feedback, project or reference. A write to <memoryRoot>/MEMORY.md sets touchedProjectScope but contributes no topic, so the gate is false, neither rebuild nor refreshMemoryInstruction runs, and extract.ts:243-250 still advances the cursor. dream.ts:263-271 handles exactly this case deliberately via writtenPaths.has(AUTO_MEMORY_INDEX_FILENAME); extraction has no counterpart.
Witness (executed against the real buildManagedAutoMemoryIndex + buildManagedAutoMemoryPrompt, 205-document store):
EDIT A (anchor on "> WARNING:", one newline):   warning still last line: true
  reader: "…MEMORY.md is 202 lines (limit: 200). Only part of it was loaded.
           Dropped 2 of 202 entries: \"New fact\", \"> WARNING: MEMORY.md is too large; only part of it was writ…\".
           No candidate entry exceeds the 150-unit line limit, so shortening entries cannot help — prune or merge entries."
  writer diagnostic survived into prompt: false
EDIT C (blank kept above, one before warning):  warning still last line: true
  reader: "…203 lines (limit: 200)… Dropped 2 of 203 entries…"   survived: false
EDIT B (pointer above the blank line):          writer notice retained verbatim + reader adds its own   survived: true

character-budget variant, PR arm vs merge base:
  BASE saved-notice length 124 -> reader: "…25082 UTF-16 code units (limit: 25000) — too many index entries (167)…"
  PR   saved-notice length 361 -> reader: "…25319 UTF-16 code units (limit: 25000) — index entries are too long…
                                 Keep index entries to one line at most 150 UTF-16 code units; move detail into topic files."
extraction gate, from the repo's own test at extract.test.ts:97-131:
  touchedTopics: [], hasToolActivity: true -> expect(refreshMemoryInstruction).not.toHaveBeenCalled(); cursor.processedOffset = 2
State the separator requirement in the imperative itself, at both :381 and :402 — for example: "If a trailing warning is present, insert new pointers above it and keep a blank line between the last pointer and the warning, so the warning stays the file's last paragraph; inserting a pointer directly against it, or appending one after it, makes the warning count as an index entry and it is dropped." Mirror the same precision at docs/users/features/memory.md:101 and in both design-doc languages, and add the boundary sentence to extractionAgentPlanner.ts:219 (and dreamAgentPlanner.ts:100) — or fold the index filename into the extraction rebuild trigger the way dream.ts:263-271 does.
Any widening of the reader must keep prompt.ts:174-177 and its pin green: index-drop-notice.test.ts "does not exempt unbounded handwritten warning-like text from the entry budget" asserts a 25,000-unit forged notice is still budgeted, so the recorded prefix-forgery surface must not grow. Please add one case to index-drop-notice.test.ts asserting that a pointer inserted with a single \n before the notice loses the exemption — buildManagedAutoMemoryPrompt must then contain Only part of it was loaded. and must not contain the full writer notice. Nothing pins this today (index-drop-notice.test.ts:394-404 covers only three and four newlines, and prompt.test.ts:351-361 always emits the separator twice), so that test goes red if the separator requirement is ever loosened without the prose being updated. For the extraction half, extend extract.test.ts with an index-only write (touchedTopics: []) asserting the rebuild or refresh still runs; note extract.test.ts:637 pins expect(result.touchedTopics).not.toContain('user'), so a fix that widens the rebuild gate instead of the prompt text must preserve it.
中文说明
本轮在此处(以及孪生位置 :402)新增的 Step-2 保存指引,是唯一强制「读取侧警告豁免所依赖的不变量」的地方,但它在两个方面不完整。第一,它唯一陈述的成功判据是「so it stays last」,而 prompt.ts:174-177 的豁免要求警告前有一个空行——它匹配 '\n\n> WARNING: …',并拒绝其中再含换行的文本。把指针插到警告上方的三种字面做法中,有两种能让警告保持在文件末尾、却仍然破坏豁免。第二,该边界只加到了三个同类 Step-2 索引保存指引中的两个;同样教 agent 手改 MEMORY.md 的 extractionAgentPlanner.ts:219 与 dreamAgentPlanner.ts:100 都没有拿到。
一个遵守指引的 agent 若用字符串锚定方式执行 Step 2(old_string 为 > WARNING: 行,new_string 为新指针加一个换行再加同一行),完全满足指引字面要求——警告仍是文件最后一行——但 hasWriterNotice 变为 false。警告随后被当作普通条目参与预算并被丢弃,读取侧把写入侧自己的警告当作「被丢弃的索引条目」按名字引用回来,行数被夸大;在字符预算变体上,原因翻转为「index entries are too long」,并给出「Keep index entries to one line at most 150 UTF-16 code units」杠杆,把写入侧自己那条 361 单元的警告当成超长条目。这正是本 PR 设计文档对累计长度压力所禁止的归因。
关于缺失的第三处:「重建总会重新生成 MEMORY.md」这一反驳并不完整。extract.ts:222-236 位于 extract.ts:204 的 if (agentResult.touchedTopics.length > 0) 门控之内,而 touchedTopicsFromFilePaths(extractionAgentPlanner.ts:266-296)只在内存根目录下第一段路径是 user、feedback、project 或 reference 时才加入 topic。对 <memoryRoot>/MEMORY.md 的写入会置 touchedProjectScope 为真但不贡献任何 topic,因此门控为假,重建与 refreshMemoryInstruction 都不执行,而 extract.ts:243-250 仍然推进游标。dream.ts:263-271 通过 writtenPaths.has(AUTO_MEMORY_INDEX_FILENAME) 刻意处理了这种情况;extraction 侧没有对应逻辑。
见证(针对真实 buildManagedAutoMemoryIndex + buildManagedAutoMemoryPrompt 执行,205 个文档的存储)见上方英文部分的三种编辑对照、字符预算变体的 BASE/PR 双臂输出,以及 extract.test.ts:97-131 中仓库自有测试对门控的固定。
修复:在 :381 与 :402 的祈使句中直接写明分隔符要求(例如:插入新指针到警告上方,并在最后一个指针与警告之间保留一个空行,使警告仍是文件最后一段;紧贴警告插入或在其后追加,都会让警告被当作索引条目而丢弃)。同样的精确表述应同步到 docs/users/features/memory.md:101 与两种语言的设计文档,并把该边界句补到 extractionAgentPlanner.ts:219(及 dreamAgentPlanner.ts:100)——或者像 dream.ts:263-271 那样把索引文件名纳入 extraction 的重建触发条件。
任何对读取侧的放宽都必须保持 prompt.ts:174-177 及其固定用例通过:index-drop-notice.test.ts 的「does not exempt unbounded handwritten warning-like text from the entry budget」断言 25,000 单元的伪造警告仍被计入预算,因此已记录的前缀伪造面不得扩大。请在 index-drop-notice.test.ts 增加一个用例,断言以单个 \n 插到警告之前的指针会失去豁免——此时 buildManagedAutoMemoryPrompt 必须包含 Only part of it was loaded.,且不得包含完整的写入侧警告。目前没有任何测试固定这一点(index-drop-notice.test.ts:394-404 只覆盖三个和四个换行,prompt.test.ts:351-361 总是发出两次分隔符),因此该用例可以在分隔符要求被放宽而文本未同步时变红。extraction 一侧请在 extract.test.ts 增加仅改索引的写入(touchedTopics: [])并断言重建或刷新仍会执行;注意 extract.test.ts:637 固定了 expect(result.touchedTopics).not.toContain('user'),若选择放宽重建门控而非修改提示文本,必须保持该断言。
— qwen3.8-max via Qwen Code /review (v0.26.1)
| expect(prompt).toContain('shortening entries cannot help'); | ||
| }); | ||
|
|
||
| it('does not blame a long entry already excluded by the line cap', () => { |
There was a problem hiding this comment.
[Suggestion] R5-2: This is the only test named for the writer's new candidate scoping at indexer.ts:248 (const candidates = lines.slice(0, MAX_INDEX_LINES);), but its fixture cannot discriminate it: the verdict is identical whether charCount and ordinaryCharCount are computed from candidates or from all of lines. That scoping is what the R2-1 fix from an earlier round turned on, so the behaviour a previous blocker was closed against is currently unpinned.
With the doc(i) fixture every ordinary line is exactly 150 units, so the 200 candidates alone total 30,199 against the 25,000 limit. ordinaryCharCount is therefore already over budget before the 201st (25,003-unit) line is ever considered, so overlongEntriesCauseOverflow is false in both variants and every assertion here — cumulative index entry length, not … index entries are too long, Dropped 36 of 201 entries: — passes identically. Only the printed unit count changes, and nothing asserts it. All 20 writer cases in this file were walked: each either passes 200 or fewer lines (so candidates === lines by construction) or keeps the total under 25,000 either way. The scoping can silently regress in the exported builder with the whole memory suite green.
Witness (mutation run in an isolated copy; indexer.ts:248 const candidates = lines.slice(0, MAX_INDEX_LINES); changed to const candidates = lines;):
CONTROL: "…201 entries (limit: 200); 30199 UTF-16 code units (limit: 25000) — cumulative index entry length. Dropped 36 of 201 entries…"
MUTANT:  "…201 entries (limit: 200); 55231 UTF-16 code units (limit: 25000) — cumulative index entry length. Dropped 36 of 201 entries…"
         <- the mutant is live: the emitted unit count moves by 25,032

CONTROL src/memory: Test Files 2 failed | 50 passed (52)   Tests 9 failed | 1150 passed | 1 skipped (1160)
MUTANT  src/memory: Test Files 2 failed | 50 passed (52)   Tests 9 failed | 1150 passed | 1 skipped (1160)
diff of the two FAIL sets: IDENTICAL FAILURE SETS
(The 9 failures are artifacts of the isolated copy — import-paths.test.ts and memoryDiscovery.test.ts — identical in both arms, so they carry no information about the mutation. Writer-focused subset control: 133/133 passed.)
Add one writer case that isolates the scoping: about 200 ordinary docs whose lines total under 25,000 units (for example 200 entries of roughly 30 units with description: ''), plus a 201st doc whose percent-encoded path alone exceeds 25,000 units, appended last in input order — buildManagedAutoMemoryIndex's comparator only partitions native against imported, so input order is preserved and the oversized doc genuinely lands past the line cap. Assert toContain('201 entries (limit: 200)'), not.toContain('index entries are too long'), not.toContain('Overlong entries already omit descriptions.'), and not.toContain('UTF-16 code units (limit:').
The new case must be pinned by the mutation that proves it: replacing candidates with lines in assembleIndex's charCount / ordinaryCharCount (indexer.ts:248-252) has to turn it red, and reverting the mutation must green it again. Keep the new fixture's overlong line outside the first 200 so the genuinely-overlong-retained-candidate arms stay reached only by their own tests — index-drop-notice.test.ts:348 asserts toContain('Overlong entries already omit descriptions.') with :347 toContain('index entries are too long'), and the same pair sits at :252.
中文说明
这是唯一为写入侧新的候选裁剪(indexer.ts:248 的 const candidates = lines.slice(0, MAX_INDEX_LINES);)而命名的测试,但它的 fixture 无法区分该行为:无论 charCount 与 ordinaryCharCount 是按 candidates 还是按全部 lines 计算,结论都完全相同。而这段裁剪正是此前某轮 R2-1 修复所开启的行为,也就是说,一个早先阻断项据以关闭的行为目前没有任何测试固定。
在 doc(i) fixture 下每条普通行恰好 150 单元,因此仅 200 个候选合计就有 30,199,超出 25,000 上限。ordinaryCharCount 在考虑第 201 行(25,003 单元)之前就已超预算,所以两种实现下 overlongEntriesCauseOverflow 都为 false,此处所有断言——cumulative index entry length、not … index entries are too long、Dropped 36 of 201 entries:——都完全一样地通过。唯一变化的是打印出的单元数,而没有任何断言检查它。本文件全部 20 个写入侧用例均已逐一走查:每个要么传入不超过 200 行(此时按构造 candidates === lines),要么两种实现下总量都在 25,000 以内。因此该裁剪可以在整个 memory 测试套件全绿的情况下于导出的构建函数中静默回归。
见证(在隔离副本中执行的变异:把 indexer.ts:248 的 const candidates = lines.slice(0, MAX_INDEX_LINES); 改为 const candidates = lines;)见上方英文部分——变异体是活的(输出的单元数变化 25,032),但两侧失败集合完全相同(各 1150 通过 / 9 失败)。那 9 个失败是隔离副本自身的环境产物(import-paths.test.ts 与 memoryDiscovery.test.ts),两臂一致,对变异不携带任何信息;写入侧子集对照为 133/133 通过。
修复:新增一个能单独隔离该裁剪的写入侧用例——约 200 个普通文档、行合计低于 25,000 单元(例如 200 条约 30 单元、description: '' 的条目),再加第 201 个文档,其百分号编码路径本身就超过 25,000 单元,并按输入顺序追加在最后(buildManagedAutoMemoryIndex 的比较器只区分 native 与 imported,因此输入顺序被保留,该超大文档确实落在行数上限之外)。断言 toContain('201 entries (limit: 200)')、not.toContain('index entries are too long')、not.toContain('Overlong entries already omit descriptions.') 以及 not.toContain('UTF-16 code units (limit:')。
新用例必须由能证明它的变异来固定:把 assembleIndex 中 charCount / ordinaryCharCount 的 candidates 换回 lines(indexer.ts:248-252)必须使其变红,还原变异后必须重新变绿。请让新 fixture 的超长行落在前 200 之外,使「真实超长且被保留的候选」分支仍只由其自有用例触达——index-drop-notice.test.ts:348 断言 toContain('Overlong entries already omit descriptions.')、:347 断言 toContain('index entries are too long'),同一对断言也出现在 :252。
— qwen3.8-max via Qwen Code /review (v0.26.1)
…ry-writer-advice-oct25
|
I merged the current gate in |


|
Verdict: merge-ready — 101/101 scripted assertions passed, 0 failed. Verified head 中文摘要结论:merge-ready —— 101/101 条脚本化断言通过,0 失败。验证 head A/B 结论(见 变异矩阵( 门禁:head 记忆套件 1238 过 / 2 败 / 1 跳过,base 1203 / 2 / 1;两条失败的文件与用例名两臂逐字节相同(+35 过、+0 败):memoryDiscovery 的 ANSI 用例在 main 顶端与独立 v0.26.3 checkout 同样失败(main 预存缺陷);冷扫描 500 主题 base 112.2ms / head 120.6ms 均超 100ms 严格上限(环境/预存,佐证作者的上游对照声明)。core typecheck、7 个改动路径 ESLint(含投毒活性证明)、10 个路径 Prettier 全绿。 未覆盖:逐提交归因(首轮,矩阵按守卫计);macOS/Windows lane;全仓 build/bundle;模型实际插入指针的行为(只测了代码侧容忍度);daemon/真实 provider/TUI;本 head 的 CI 尚在运行。 Central claim and A/BClaim: index rebuilding that omits memories — at the 200-file scan cap or the 200-line / 25,000-unit index budget — now stamps a bounded, named, cause-specific notice into the written Instrument: source-level harness (
Head 47/47, base 28/28. The S2 character count (25,669) independently reproduces the exact number the PR description claims for 170 legal entries. Previous review findings, re-measured at head 2fea5d2First verification round; the PR carries five bot review rounds. Every open ledger item was re-measured, not quoted:
Corrections
Findings (all non-blocking; ordered by value)F1 — writer candidate scoping is unpinned (confirms R5-2). M5 ( F2 — F3 — F4 — the Step-2 trailing-warning instruction is unasserted (new). M13/M14 (delete the sentence at either site) survive all 446 tests. This instruction is the only enforcement of the invariant the reader's exemption depends on (R5-1's point); nothing pins its presence, let alone its precision. Coverage gap; suggest a prompt-text assertion at both sites. F5 — standing reader findings R2-2/R3-2 (delegated, pre-existing). Measured above; not charged to this PR's ledger. Merge path: #15368 first, then resync. F6 — main-side observation (not this PR). Evidence: Reviewer Test Plan walkthrough
Not covered
EvidenceCaptured from the live runs (files hosted on the
MethodologyLocal maintainer round in the dedicated |
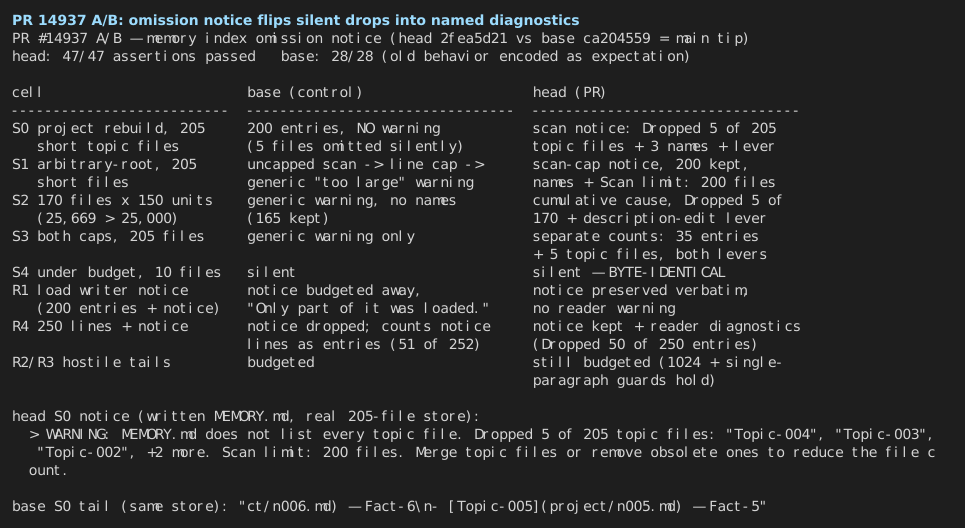
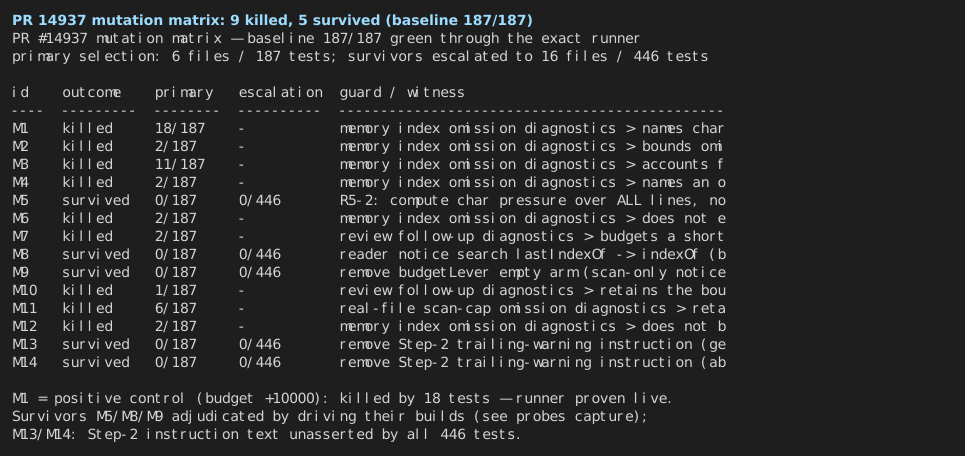
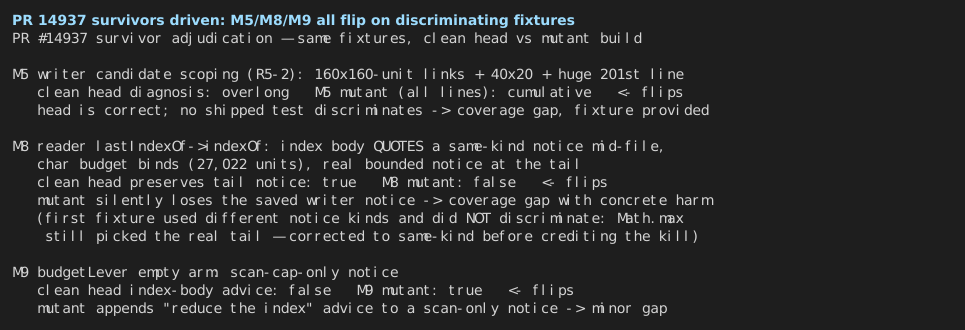
qwen-code-review-bot
left a comment
qwen-code-review-bot
left a comment
There was a problem hiding this comment.
Partially reviewed — gaps disclosed.
5 Suggestion-level finding(s) this review confirmed are already reported on this PR and are not repeated:
- R5-1 Step-2 save-instruction separator and sibling-site gap — already reported (comment 4378967496)
- R5-2 candidate-scoping test cannot discriminate the scoping — already reported (comment 4378967514)
- R3-2 reader overflow-cause predicate divergence — already reported (comment 4354055944)
- R1-7 orphaned team scan wrapper — already reported (comment 4343381380)
- R2-4 orphaned uncapped scan wrapper — already reported (comment 4351849968)
Not reviewed: build-and-test — Test (macos-latest, Node 22.x) and Test (windows-latest, Node 22.x) were skipped in CI and no local run covered those platforms.
中文说明
仅完成部分审查,审查缺口已披露。
本轮确认的 5 条建议级发现已在 PR 上报告过,不再重复发布(列表见上方英文部分)。
未审查(原文为英文):build-and-test — Test (macos-latest, Node 22.x) and Test (windows-latest, Node 22.x) were skipped in CI and no local run covered those platforms.
— deepseek-v4.1-flash-1017 via Qwen Code /review (v0.26.3)


 yiliang114
left a comment
yiliang114
left a comment
There was a problem hiding this comment.
APPROVE — no remaining P0/P1 findings at head 2fea5d2.
This PR has been through 5+ rounds of review and the remaining Suggestion-level work is properly deferred per the AGENTS.md five-round rule. The notice-preservation guard in truncateManagedAutoMemoryIndex is correctly bounded (≤1024 UTF-16 units, single-paragraph only) and the test coverage is thorough across scan-cap, character-budget, combined, hostile-name, surrogate-pair, and multiline-tail cases. Linked reader Criticals R2-2 and R3-2 remain with #15368 as disclosed.
|
Released in v0.26.5. |


What this PR does
Report index-budget omissions and scan-cap topic-file omissions separately, with bounded name samples, and preserve the saved writer warning when loading a bounded, known trailing notice into the prompt. Character pressure among otherwise legal entries names cumulative entry length and offers durable description/name/path edits alongside merging or removal. The save instructions keep new pointers above a trailing warning.
Why it's needed
Index rebuilding can omit memories without telling the next session which files are missing. The two omission counts have different meanings: one grouped team entry can represent several files. A character limit can also bind below the entry-count cap: 170 legal entries fill 25,669 units, while shortening their descriptions can preserve all 170. Calling that state only “too many entries” can send the maintenance agent toward unnecessary removal.
Reviewer Test Plan
How to verify
Evidence (Before & After)
Current head:
fe9439ffb09161e86ef67327d4c6afa60d586e57, containing required upstream gatee24f9c48fd333fceeb69883434045a47574ed496through a normal merge. This update changes integration history, not the reviewed writer/scanner implementation.The recorded writer control retains 165/170 entries under the original pressure. Description-only edits retain 170/170 without a warning. Its regression fails when the diagnosis is reverted; the prior mutation evidence remains tied to the earlier recorded head.
Fresh current-head root build, bundle, complete typecheck, ESLint over seven changed TypeScript paths, Prettier over all ten PR paths, nine gate-freshness tests, and 44 lint-scope tests pass. The full Linux memory run reports 1,162 passed, two skipped, and one cold-scan performance failure: 210.0 ms against the unchanged 100 ms ceiling. This is not a green suite. A separate native Windows control reproduces the same assertion on clean gate-source
e24f9c48fdat 182.5 ms, with its own rebuilt core and unchanged test/configuration/dependencies; it is not a full-root baseline build and does not clear the performance gate or identify its sole cause.Tested on
Environment
Node 22.21.1, frozen pnpm dependencies, isolated Linux checkout, 6 GiB build/typecheck heap. Performance limits, retries and CI/runner markers were not relaxed.
Risk & Scope
Linked Issues
Related to #14834 and companion #15368.
中文说明
此 PR 的改动
分别报告索引预算省略和扫描文件上限省略,并提供有界名称样本;读取提示时保留已保存且符合有界尾部格式的写入警告。普通长度条目造成的字符压力会被解释为累计条目长度,并提供持久的描述、名称、路径修改以及合并或移除方式。保存指令要求将新指针插在尾部警告之前。
为什么需要
索引重建可能省略内存,却没有告诉下次会话哪些文件缺失。两类省略数量含义不同:一个分组团队条目可能代表多个文件。字符限制也可能在未超过条目数上限时生效:170 条合法条目占 25,669 单位,而缩短描述可能保留全部 170 条。仅将这种情况称为“条目过多”可能引导维护代理进行不必要的移除。
审阅者测试计划
如何验证
前后对比证据
当前提交:
fe9439ffb09161e86ef67327d4c6afa60d586e57,通过普通合并包含所需的上游门槛e24f9c48fd333fceeb69883434045a47574ed496。此次更新改变集成历史,不改变已审阅的写入端和扫描器实现。已记录的写入端对照在原始压力下保留 165/170 条目。仅修改描述可保留 170/170 且没有警告。恢复原来的诊断会使回归失败;此前变异证据仍对应先前记录的提交。
当前提交重新执行的根目录构建、打包、完整类型检查、覆盖七个 TypeScript 修改路径的 ESLint、覆盖全部十个 PR 路径的 Prettier、九个门槛新鲜度测试及 44 个 lint 范围测试均通过。完整 Linux 内存运行结果为 1,162 个通过、两个跳过、一个冷扫描性能失败:210.0 毫秒,超过未修改的 100 毫秒上限。这不是全绿套件。独立原生 Windows 对照在干净的门槛源码
e24f9c48fd上同样触发该断言,测得 182.5 毫秒,使用自行重建的核心及未修改的测试、配置和依赖;这不是完整根目录基线构建,也不代表性能门槛通过或唯一原因已确定。已测试平台
环境
Node 22.21.1,冻结 pnpm 依赖,独立 Linux 检出目录,构建和类型检查使用 6 GiB 堆。未放宽性能限制、重试次数或 CI/runner 标识。
风险与范围
关联问题
关联 #14834 及配套 #15368。