Repository navigation
Where should a training-free high-resolution hook for Flux (DyPE / spectral attention) live? #14520
Description

Summary
I have a working, tested implementation of training-free ultra-high-resolution generation for RoPE DiTs (Flux) — DyPE plus an optional spectral-attention mode (SEGA) — and I'd like to contribute it. Before opening the PR I want to align on where it should live, because precedent points two ways.
The placement question (the main thing I'd like a call on)
- Core
src/diffusers/hooks/— the method modifies the transformer's positional embedding at inference, exactly likeapply_pyramid_attention_broadcast/apply_faster_cachemodify attention. That argues for a core hook (apply_dype). examples/community/— but training-free high-resolution generation methods have historically landed as community pipelines (e.g. DemoFusion, [Community Pipeline] DemoFusion: Democratising High-Resolution Image Generation With No $$$ #6022), which argues for a community pipeline instead.
DyPE straddles the two. I've built it as a core hook (details below), but I'm happy to reshape it as a community pipeline if that's the preferred home. Which do you want?
What it does
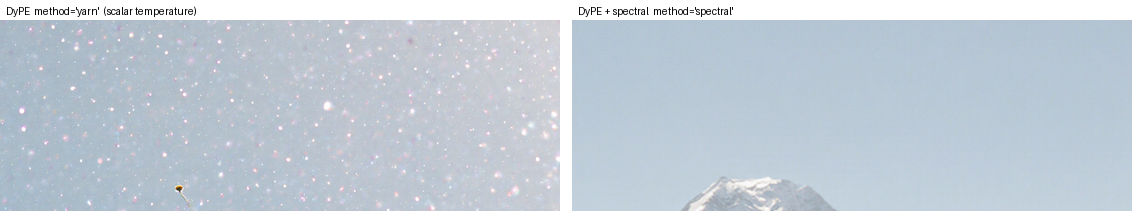
apply_dype(pipe.transformer, method="yarn") swaps the transformer's RoPE embedding for a timestep-aware YaRN/NTK-by-parts schedule that engages only above the trained resolution (a no-op at/below 1024² for Flux). method="spectral" adds a per-frequency, content-aware attention temperature derived from the latent's spectral energy, which removes the residual high-frequency speckle a scalar temperature leaves in flat regions at 4K. State is fed via a native register_forward_pre_hook, so it survives enable_model_cpu_offload.
Naming note: the spectral mode implements SEGA (arXiv:2605.22668), but I've named the API value
method="spectral"rather than"sega"to avoid confusion with the existing Semantic Guidance ("SEGA") in diffusers (SemanticStableDiffusionPipeline,examples/community/pipeline_flux_semantic_guidance.py). Open to a different name.
Validation (FLUX.1-Krea-dev, 4096²)
method="yarn"reproduces the reference (guyyariv/DyPE, MIT) bit-for-bit (Δ=0 on the positional-embedding output).method="spectral"drops flat-sky high-frequency energy ~6× (76.5 → 12.7) with detail retained:
Other design questions
- One PR or split? DyPE and the spectral mode are independent (spectral layers on top). Land DyPE first + spectral as a follow-up, or both together?
- High-resolution flow-match shift. Above ~2K,
calculate_shift'smugrows with sequence length and collapses the sigma schedule; today the fix is a documentedpipe.scheduler.register_to_config(base_shift=1.15, max_shift=1.15). A pos-embed hook can't reach the pipeline schedule — keep it as documented usage, add a helper, or handle it pipeline-side? .item()in the embedding forward. Extrapolation engages only above the trained resolution, which needs a data-dependent read of the max position (a device sync /torch.compilegraph break the stock embedding doesn't have). Acceptable, or a preferred pattern?
Status
Implementation + docs + tests are ready and rebased on current main (24 hook tests pass, make fix-copies clean, apply_dype a no-op at/below the trained resolution). I can open the PR as soon as we settle placement (1) — reference branch/diff available on request.
Activity
smellslikeml commentedon Aug 27, 2026
Following up on the placement question — I went ahead and built the community modular pipeline version, since it needs no core changes and mirrors the direction suggested for the HRDiT high-res pipeline in #14480.
remyxai/dype-flux-modular — https://huggingface.co/remyxai/dype-flux-modular
It's a Modular Diffusers custom block — load and generate at up to 4096² from off-the-shelf FLUX.1-Krea-dev in three lines, single pass, training-free:
What the block does:
method="spectral"— an optional SEGA per-frequency attention temperature that selectively suppresses the high-frequency speckle DyPE leaves in flat regions, without softening real detail.Validated on FLUX.1-Krea-dev at 4096² / guidance 4.5: coherent full frames where the stock pipeline collapses to a blob, and
spectralvisibly removes the speckle (before/after crops are on the model card). Peak ~49.8 GB (bf16) with VAE tiling.