






Search and retrieval for .NET — BM25, rank fusion and reranking in composable pipelines.
Index a corpus, score it, fuse several retrievers by rank, rerank the result — then read back why each document landed where it did. The core is an in-memory inverted index, four ranking strategies and their BM25 variants, rank fusion, reranking, IR metrics and end-to-end search traces; the models stay in your application behind a seam you implement. It references no NuGet package at all.
- Nothing to host. No vector database, no embedding API, no native library: the core is BCL only. PostgreSQL, ASP.NET Core and MessagePack are separate, optional packages.
- The ranking can explain itself. Every stage writes a
SearchTrace— the score going in and out — andExplainbreaks a scorer down further, to its per-term contributions, so "why did this rank here?" is a method call. - Composition, not configuration. The index owns corpus statistics, the scorer is a pure
strategy over it, the engine orchestrates. Hybrid retrieval and reranking are decorators over
the same
ITextSearchEngine, so a pipeline is stages wrapping each other. - Scored against published results. The plain BM25 scorer is measured on three public BEIR corpora and compared with the figures published for them; the numbers are pinned, and a workflow replays every one of them on a push that touches the library or the harness, and weekly.
📖 Documentation → — the guide, the reference, and every measurement with the command that reproduces it. This README is the short version.
nDCG@10 on three public BEIR corpora, with the analysis, the BM25 parameters and the metric convention aligned to those the published figures were produced with:
| Corpus | LexiSharp | Published | Δ |
|---|---|---|---|
| NFCorpus | 0.3215 | 0.3218 | −0.0003 |
| SciFact | 0.6788 | 0.6789 | −0.0001 |
| ArguAna | 0.3970 | 0.3970 | 0.0000 |
Under this library's own default analysis and parameters the same scorer reads 0.308 / 0.662 /
0.320; that difference is the configuration, not the ranking. Corpora are md5-verified on
download, and on ArguAna trec_eval — the standard evaluator, not this repository's metric
code — reads the same figures off a run the harness writes.
The full tables, and the command that reproduces them →
dotnet add package LexiSharp # the core: index, scorers, engines, decorators — no dependenciesOr from a terminal, without writing any code:
dotnet tool install -g LexiSharp.Cli
lexisharp segment build ./docs              # → ./.lexisharp
lexisharp search --query "rank fusion" # finds the store in the foldernet10.0, MIT. Optional: LexiSharp.MessagePack (binary index persistence),
LexiSharp.AspNetCore (a GET /search minimal-API endpoint), LexiSharp.Postgres (lexical,
vector, sparse, fuzzy and true BM25 backends) — packages.
using LexiSharp.Core;
using LexiSharp.Indexing;
using LexiSharp.Ranking;

// Three pieces, one contract: the index owns the corpus statistics, the scorer is a pure
// ranking strategy reading from it, the engine orchestrates. Each of the three is an
// interface, so you replace one without touching the others.
ITextSearchEngine engine = new RankedTextSearchEngine(
    new InMemoryTextIndex(),
    new Bm25Scorer());

engine.Index(new[]
{
    new SearchDocument("1", "The search engine uses BM25 to rank the results"),
    new SearchDocument("2", "TF-IDF is a classic method of textual search"),
    new SearchDocument("3", "Italian cuisine is renowned in Rome"),
});

foreach (var result in engine.Search("textual search"))
    Console.WriteLine($"{result.DocumentId} - {result.Score:0.###}: {result.Document.Text}");
That is the smallest thing the library does. The rest is composition: every engine above
implements ITextSearchEngine, and a pipeline is stages wrapping each other. Given two engines
over one index, HashingEmbeddingProvider standing in for your IEmbeddingProvider (no model,
no service):
var hybrid = new HybridTextSearchEngine(
    new[] { lexical, dense },
    new ReciprocalRankFusionMerger());   // a BM25 score and a cosine, fused by rank, uncalibrated

ITextSearchEngine pipeline = new RerankedTextSearchEngine(
    hybrid, new ProximityReranker(index));   // ...or MMR, a cascade, MaxSim, a cross-encoder
Replacing a piece is the whole extension model. A PostgreSQL, vector, sparse or fuzzy backend
takes the same slot, and IEmbeddingProvider, ISparseEmbeddingProvider and
ICrossEncoderScorer are yours to implement — pipelines,
backends.
LexiSharpIndex<T> is the typed facade over the same engine if you would rather hand it your own
objects — Getting started.
dotnet run --project samples/LexiSharp.Demo # → http://localhost:5000Five retrieval strategies over one corpus, compared live — BM25, corpus-derived semantic expansion, dense hashing embeddings, RRF fusion and a term-overlap rerank — with per-lane latency, highlighting and a click-through "why did this rank here?" panel. No model, no external service.
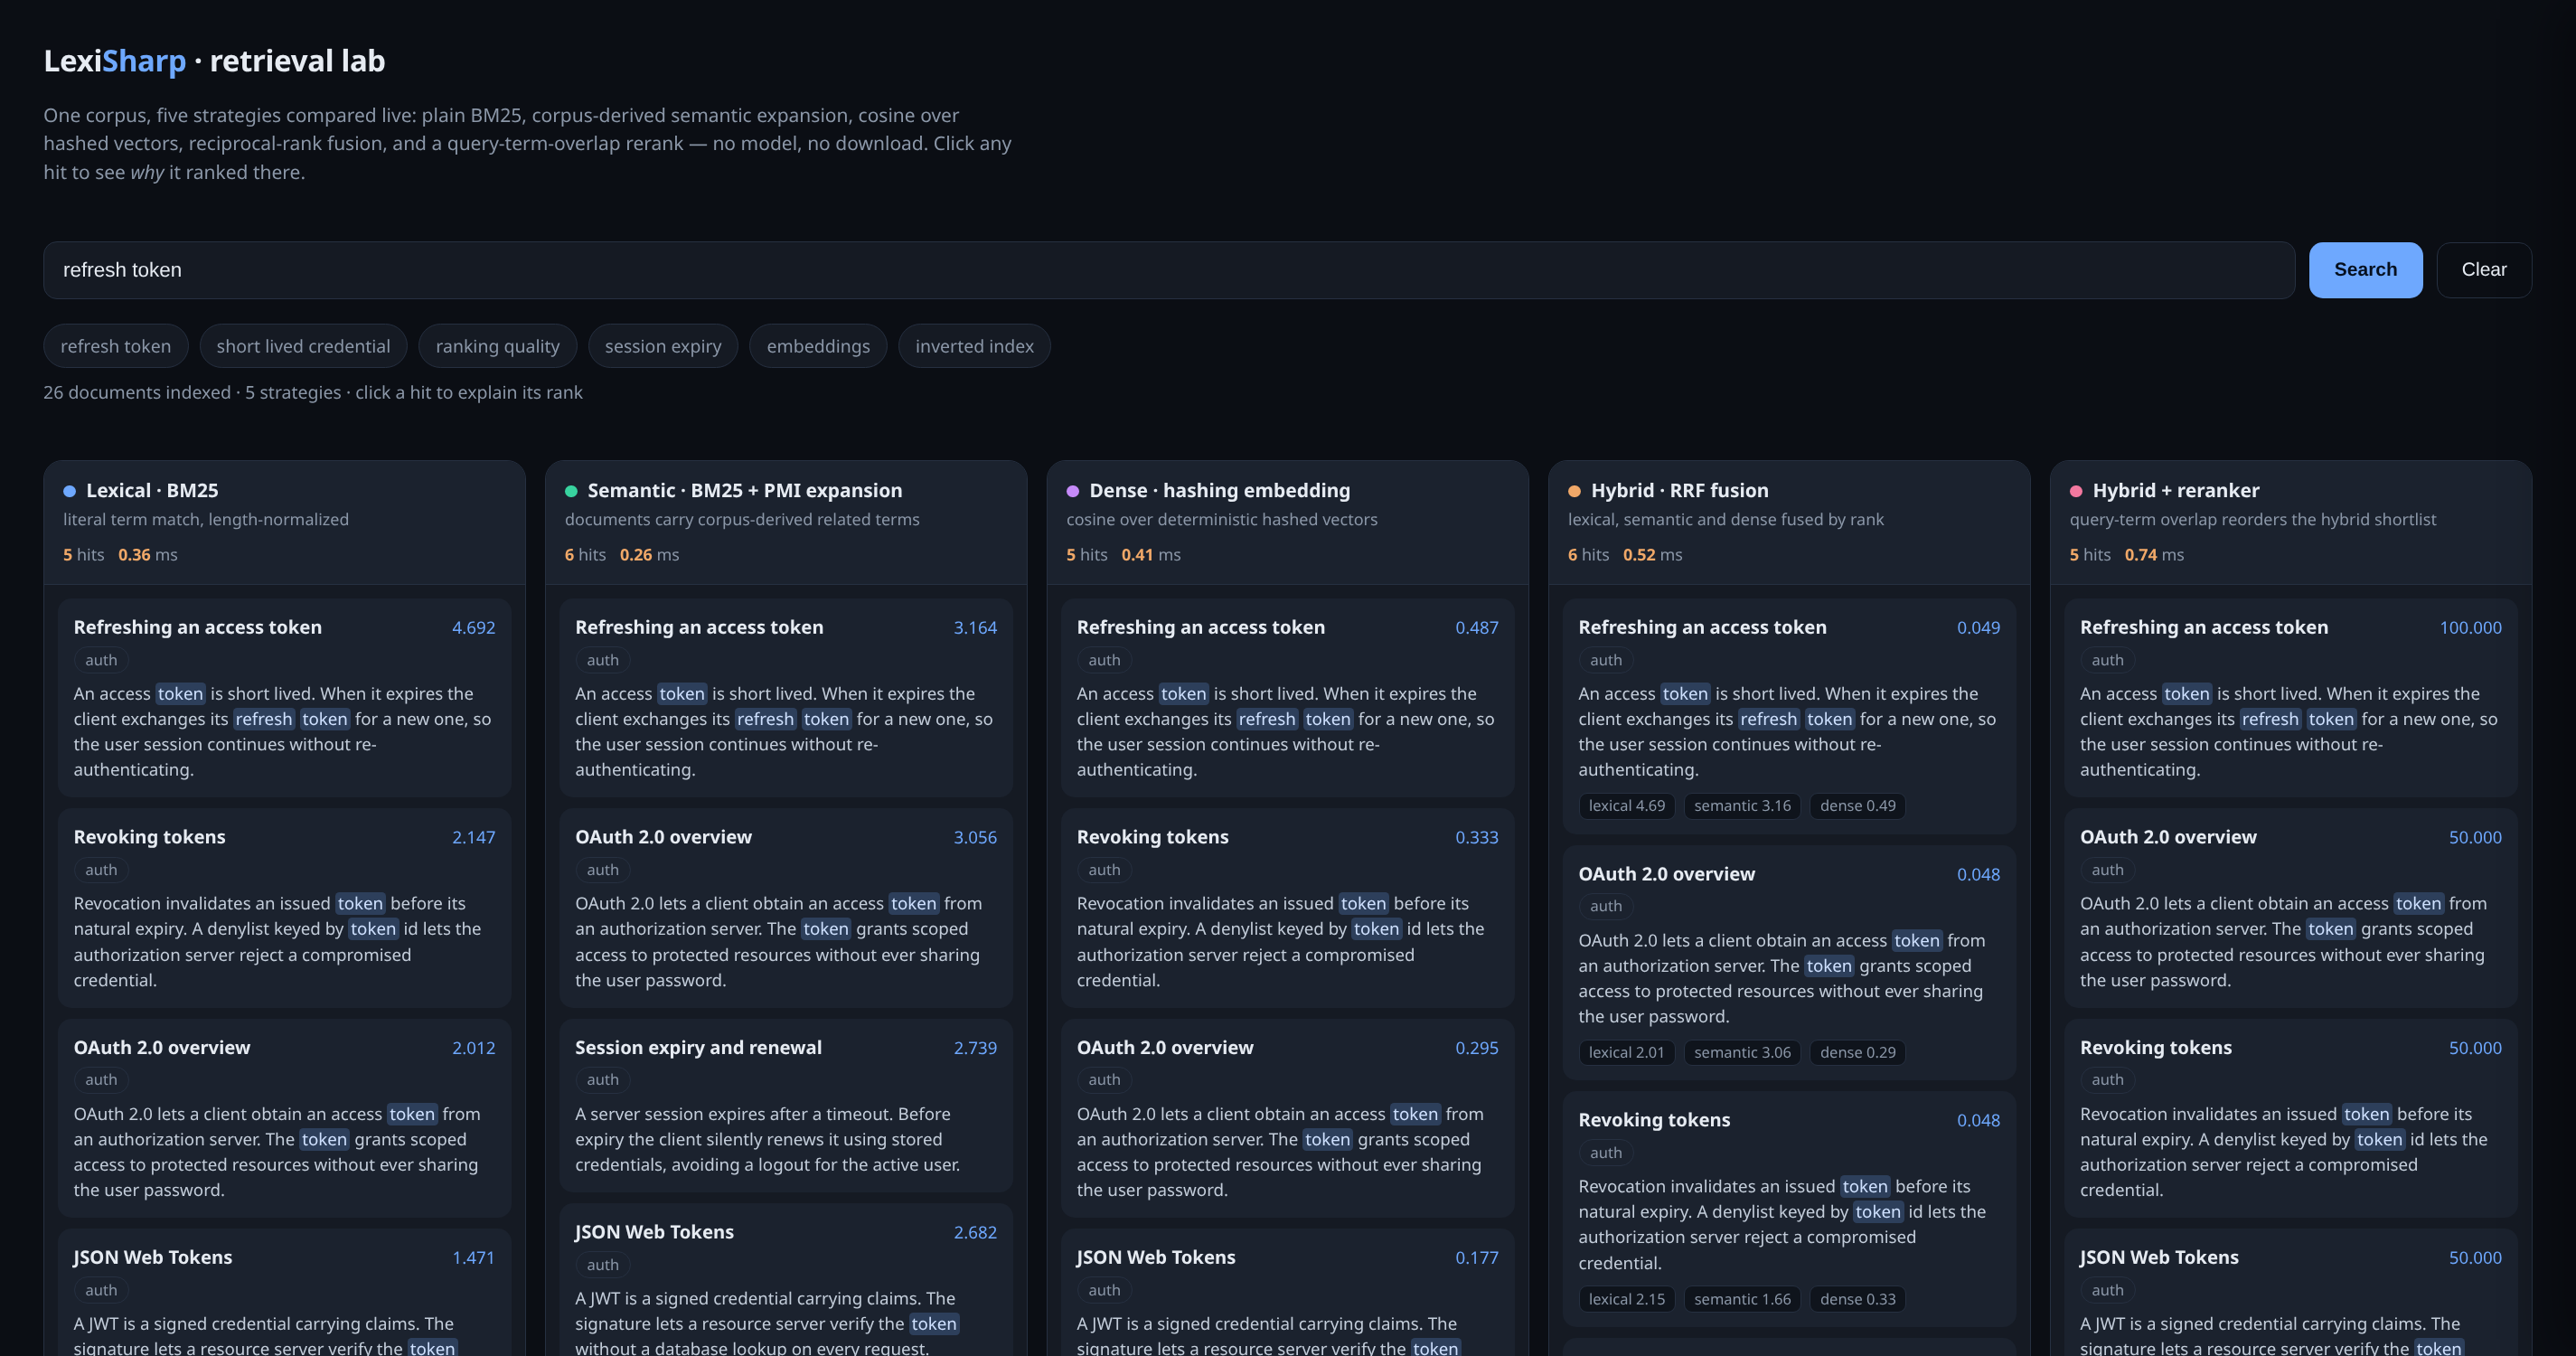
Clicking a hit shows the SearchTrace for that document: the stages it passed through, and the
score going in and out of each.
score   4.6925 -> 4.6925  BM25
score   3.1642 -> 3.1642  BM25
score   0.4867 -> 0.4867  Dense
merge   0.0492 -> 0.0492  dense=0.4867 lexical=4.6925 semantic=3.1642
rerank  0.0492 -> 100     CrossEncoder(QueryTermOverlap)
Each lane states what backs it — the semantic lane uses PmiTermExpander, the dense lane a
HashingEmbeddingProvider, the rerank lane a local term-overlap ICrossEncoderScorer — and all
three are swappable for a real model behind their existing seam.
--corpus nfcorpus|scifact|arguana runs the same five lanes over a BEIR corpus instead of the
built-in one, read from the evaluation harness's data directory. The demo and the harness do not
tokenize identically, so a demo figure is not a harness figure — compare by running the harness.
What the demo shows, and how to read it →
LexiSharp                core: index, scorers, fusion, reranking, metrics, traces — no dependencies
├── LexiSharp.Postgres   tsvector · pgvector · sparsevec · pg_trgm · pg_search (Tantivy) BM25
├── LexiSharp.MessagePack    binary persistence for the in-memory index
├── LexiSharp.AspNetCore     a GET /search minimal-API endpoint over LexiSharpIndex<T>
└── LexiSharp.Cli            a dotnet tool: search a directory, build a store, benchmark a config
LexiSharp also carries text analysis next to the search box: lexical similarity, keyword
extraction and a Naive Bayes classifier — text analysis.
Stated plainly, so nothing is implied. The full list, with the measurement behind each claim, is Scope and limits.
- It matches the published BM25 baseline on all three corpora it can be compared on. On NFCorpus
and SciFact, with the analysis, the BM25 parameters and the metric convention aligned to those the
reference figures were produced with, the plain BM25 scorer reaches nDCG@10 0.3215 and
0.6788 against 0.3218 and 0.6789 — equal to the fourth decimal. On ArguAna, at the
reference's own k1=0.9/b=0.4, it reaches 0.3970 against the 0.3970 that implementation
publishes, and recall@100 0.9324 against 0.9324. That last one is not measured only by this
harness:
trec_eval— the standard evaluator, not this repository's code — reads both figures off a run this harness writes, and the 15,466 returned scores for the 1,406 queries match the reference's own searcher on the raw bits, so the ranking is that ranking rather than a lookalike. The same scores read under the library defaults are 0.308 / 0.662 / 0.320; that difference is the analyzer, the parameters and one task convention, not the ranking. Corpora are md5-verified on download, and the numbers are pinned and re-checked by thePinned referenceworkflow, which replays every pinned configuration and exits non-zero on drift. It runs on a dispatch, on a push that touches the library or the harness, and weekly — see evaluation. - An earlier figure published for ArguAna was withdrawn; it is not reproducible by any code path in this repository. See the changelog.
- No scorer here has a measured win over a tuned BM25. BM25+ and BM25L, tuned on their own
δ, tie a tuned BM25 on the reference corpus and NFCorpus and edge it by 0.002–0.004 on SciFact — an in-sample margin, so an upper bound rather than a result. On ArguAna, untuned, they lose, and noδ-tuned ArguAna row exists, so whether tuning closes that gap is unmeasured (ranking). - The SQL backends are measured on ranking, not on every engine. The two PostgreSQL engines
that rank on their own are scored over the same BEIR queries and qrels as the in-memory table: at
matched k1=0.9/b=0.4, ParadeDB's Tantivy BM25 reads 0.3055 and 0.6633 on NFCorpus and
SciFact against this library's 0.305 and 0.655, and
ts_rank_cdreads 0.1864 and 0.0188, which is mostly its matcher — it ANDs every term. ArguAna produces no row: both engines reject 2 of its 1,406 test queries' syntax, and these rows are not pinned. The vector engine goes the same way over the cached embeddings, one row peref_search: NFCorpus 0.2882 / 0.2960 / 0.3013 at 10 / 40 / 160 against the exact in-memory dense row's 0.304, and SciFact 0.5998 / 0.6528 / 0.6550 against 0.655 — that gap is what the index costs in nDCG. ArguAna is not measurable for any of the three (the text engines reject 2 of its 1,406 test queries, the vector engine 148), and the sparse and fuzzy engines are still measured only by integration tests (backends, evaluation). - Not every combination is tested. Engines, scorers, rerankers and mergers are tested individually and in the combinations described, but not every pairing — treat an unusual one as supported but unproven until you test it on your data.
- Version 0.8.0, one maintainer. The public API may still change between minor versions —
pin a version and read the release notes. 0.8.0 breaks two things:
QueryFeatures.Phrasesreplaces the pair ofparent/childfeatures on the central record, andAccumulateFilteredQueriesnow defaults to the fast path.
dotnet build LexiSharp.slnx
dotnet test  tests/LexiSharp.Tests   # xUnit suite; the Postgres suites need POSTGRES_TEST_CONNECTION
The retrieval quality gate replays every pinned configuration on the three BEIR corpora and exits non-zero on any drift. It downloads the corpora on first run, so it is not part of the xUnit suite:
dotnet run --project bench/LexiSharp.Eval -c Release -- --verify-referenceBenchmarks, the evaluation harness and the behavioural gate: Reference and Benchmarks.
MIT — see LICENSE. The ParadeDB pg_search extension used by the BM25 backend is
licensed separately, under AGPL-3.