Repository navigation
fix(ci): fail Java lanes before disk exhaustion - #16068
Conversation


Co-authored-by: Qwen-Coder <qwen-coder@alibabacloud.com>


|
Thanks for the PR! Template looks good ✓ Problem: real and well-evidenced, not theoretical. #16003 is open and carries three dated runs across two pools, the broker's Direction: aligned. This extends the disk-floor gate that already exists at Size: not applicable — no core paths ( Approach: the shape is right. Reusing the existing script and its exact established call form ( One scope question worth answering before the code review, not a blocker: the gate is Risk: no elevated risk signals — neither changed file matches the revert-correlated high-risk paths. Moving on to code review. 🔍 中文说明感谢贡献! 模板完整 ✓ **问题:**真实且证据充分,不是理论性加固。#16003 仍处于 open 状态,里面有跨两个 runner 池、三个不同日期的运行记录,broker 的 **方向:**对齐。本 PR 扩展的是已经存在的磁盘下限门禁 **规模:**不适用——没有触及核心路径( **方案:**整体形态是对的。复用现有脚本及其既有调用形式( 有一个范围问题希望在代码审查前先回答(不是阻塞项):门禁的条件是 **风险:**无升级风险信号——两个改动文件都不匹配与回滚相关的高风险路径。 进入代码审查 🔍 — Qwen Code · qwen3.8-max-2026-09-02 Reviewed at |
Code reviewMy independent proposal from the title and motivation alone: wire the existing 🔴 Blocker 1 — the gate landed in a hosted-only job; the pool lane it was meant for is still ungatedIn the head blob (
Two consequences, and they pull in opposite directions:
The mix-up is easy to make: both jobs have a byte-identical checkout block — - name: 'Checkout'
uses: 'actions/checkout@df4cb1c069e1874edd31b4311f1884172cec0e10' # v6.0.3
with:
ref: '${{ inputs.ref || github.sha }}'— at 1209 ( 🔴 Blocker 2 — the new meta-test contradicts the workflow it pins, so it failsThe test collects every job containing a step named The actual gated set is the same list with To be clear about which side is wrong: the test is right and the workflow is wrong. Fixing Blocker 1 makes this test pass as written. Please don't edit the expected array to match the diff — that would turn a correct pin into a record of the mistake.
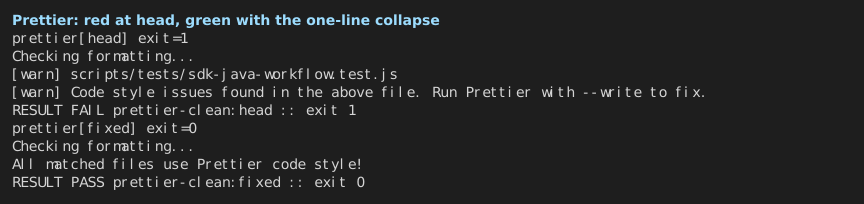
🔴 Blocker 3 — observed CI failure: Prettier on the new test file
The cause is this call, which fits on one line at that indent (78 of 80 columns, and expect(steps[gateIndex - 1]?.uses, name).toMatch(/^actions\/checkout@/);The PR body notes local lint and formatting were intentionally not run, which is why this shipped red. What checks out ✅
Open question (non-blocking, carried from Stage 1)The gate is self-hosted-only, but #16003's second symptom — 17 × JUnit Test evidenceThis is an unattended CI run, so I did not build or execute anything from the PR — the evidence below is the PR's own CI, read through the API, plus static reads of the head blob. One check is red, six substantive lanes were still running at fetch time, and 40 checks were skipped as expected for a CI-only diff. Final CI results for
One row per check name (latest run); skipped checks omitted; failures sort first. / 每个检查名一行(取最新一次运行),省略 skipped,失败项排在最前。 The red Not verified: the meta-test failure in Blocker 2 — 中文说明代码审查只看标题和动机时,我自己的方案是:把已有的 🔴 阻塞项 1 —— 门禁加到了仅托管的 job 上,真正需要它的池车道反而没有在 head 版本(
由此产生两个方向相反的后果:
这个混淆很容易发生:两个 job 的 checkout 块逐字节相同——都在 1209 行( 🔴 阻塞项 2 —— 新增元测试与它所钉住的 workflow 自相矛盾,因此会失败该测试收集所有包含 需要说清楚哪一边错了:**测试是对的,workflow 是错的。**修掉阻塞项 1,这个测试原样就能通过。请不要为了对上 diff 而去改那个期望数组——那会把一个正确的钉子变成对错误的记录。
🔴 阻塞项 3 —— 已观测到的 CI 失败:新测试文件的 Prettier
通过的部分 ✅
待答问题(非阻塞,承接 Stage 1)门禁只在自托管生效,但 #16003 的第二个症状——17 次 JUnit 测试证据这是无人值守的 CI 运行,因此我没有构建或执行 PR 里的任何代码——下面的证据来自通过 API 读取的 PR 自身 CI,以及对 head 版本的静态阅读。一个 check 为红,六个实质车道在拉取时仍在运行,另有 40 个 check 按预期跳过(纯 CI 改动)。 **未验证:**阻塞项 2 的元测试失败—— — Qwen Code · qwen3.8-max-2026-09-02 Reviewed at |
|
Confidence: 2/5 — the right fix using the right existing mechanism, but one of the six blocks landed on the wrong job, so the PR doesn't currently do what it says it does and its own new meta-test fails. Going back to the proposal I wrote before reading the diff: it matched this PR almost exactly — same script, same placement after checkout, same That also means the description's two central claims are falsified by the diff: "all six Java lanes that can be routed to the shared ECS pool" (five), and "Hosted-only jobs are unchanged" (one was changed). I don't think that's dishonesty — it reads like the write-up was composed from the intent, and the intent was correct. But a reviewer who trusts the prose here would merge a gap. The genuinely good news is that the PR's own meta-test catches it. The expected set names Everything else holds up. The other five placements are correct, the call form is identical to the six existing sites, the Two things I'd fix before this lands: move the block from after line 1209's checkout to after line 783's, and run On the pattern question: this is one of six PRs the author opened today, which is exactly the conditions for a hand-placement slip in a large YAML file — no judgement, just the likely mechanism. It's also worth noting this is the author's own area (#15979, the hosted tmpdir routing referenced in #16003, is theirs), so I'm treating this as a mechanical error rather than a misunderstanding, and I'd expect one push to fix it. Not approving, and requesting changes on the three items above. Once the gate is on the lane it was written for and lint is green, this is a straightforward yes — the change is small, reuses shared infrastructure, and closes a diagnostic gap that has already cost two rounds of misattribution. 中文说明Confidence: 2/5 —— 修法对、复用的机制也对,但六个步骤块里有一个落错了 job,因此本 PR 目前并没有做到它声称的事,而且它自己新增的元测试会失败。 回到我在看 diff 之前写下的方案:它和这个 PR 几乎完全一致——同一个脚本、同样放在 checkout 之后、同样的 这也意味着描述里两个核心论断被 diff 本身推翻了:"所有六个可能路由到共享 ECS 池的 Java 车道"(实际五个),以及"仅托管 runner 的 job 不受影响"(有一个被改了)。我不认为这是刻意不实——更像是文案按意图写的,而意图本身是对的。但如果评审者在这里相信文字,就会把一个缺口合并进去。 真正的好消息是:PR 自己的元测试抓到了这个问题。期望集合里写的是 其余部分都站得住。另外五处位置正确,调用形式与已有的六个调用点完全一致,"RUNNER_TEMP 覆盖 broker store"这条注释可以对照 落地前我会修两处:把那个块从 1209 行 checkout 之后移到 783 行 checkout 之后;跑一次 关于"是否属于某种模式":这是作者今天开的六个 PR 之一,而这正是在大型 YAML 文件里手工放置出错的典型条件——不带评判,只是最可能的成因。另外值得一提,这本身就是作者熟悉的领域(#16003 里提到的托管 tmpdir 改造 #15979 就是他提的),所以我把它当作机械性失误而非理解偏差,预期一次 push 就能修好。 不予 approve,并就上述三项提交 request changes。一旦门禁落到它本该保护的车道、且 lint 转绿,这就是一个明确的 yes——改动很小、复用了共享基础设施,并且补上了一个已经造成两轮误判的诊断缺口。 — Qwen Code · qwen3.8-max-2026-09-02 Reviewed at |

 qwen-code-review-bot
left a comment
qwen-code-review-bot
left a comment
There was a problem hiding this comment.
Needs a small rework before this can land — the mechanism and the direction are right, but the diff doesn't currently do what the description says. 🙏
Three items, detailed in my review comments above:
- The gate landed on the wrong job. In a 2,500-line workflow with two byte-identical checkout blocks, the third gate went into
hosted-harness-mysql(runs-on: 'ubuntu-latest', so itsif: runner.environment == 'self-hosted'can never be true — the step is inert) whilemysql-integration(pool-routed, MySQL container + two Maven passes,timeout-minutes: 310) got nothing. Move the block from after the checkout at line 1209 to after the one at line 783. - Your new meta-test fails against your own workflow. It expects the gated set to include
mysql-integrationand excludehosted-harness-mysql— which is the correct set. Fix the workflow, not the expected array. Lint & Staticis red: Prettier onscripts/tests/sdk-java-workflow.test.js— the line-wrappedtoMatch(/^actions\/checkout@/)fits in 78 of 80 columns, so it collapses.npm run formatclears it.
Everything else checks out: the other five placements are correct, the call form matches the six existing sites, the RUNNER_TEMP-covers-the-broker-store comment is verifiable against RMQ_WORK_DIR, and the Flyway lane already ran the new step on pool runner ecs-qwen-hz3-17 and came back green with two DISKFLOOR samples. Once the block moves and lint is green, this is a straightforward yes.
One open question, not a blocker: the gate is self-hosted-only, but #16003's second symptom (17 × JUnit Failed to create default temp directory) was observed on the hosted ubuntu-latest / Java 17 leg, where this step is skipped. If that half is deliberately left to #15979, it'd be worth saying so in the PR.
中文说明
落地前需要一点小改——机制和方向都对,但 diff 目前没有做到描述所说的事情。🙏
三项,细节见上方的审查评论:
- **门禁落错了 job。**在一个 2500 行、且有两个逐字节相同 checkout 块的 workflow 里,第三处门禁进了
hosted-harness-mysql(runs-on: 'ubuntu-latest',所以它的if: runner.environment == 'self-hosted'永远不可能为真——这一步是无效的),而mysql-integration(池路由、MySQL 容器 + 两轮 Maven、timeout-minutes: 310)什么也没拿到。请把这个块从 1209 行 checkout 之后移到 783 行 checkout 之后。 - **你新增的元测试对着你自己的 workflow 会失败。**它期望受门禁的集合包含
mysql-integration、不含hosted-harness-mysql——这是正确的集合。请修 workflow,不要改期望数组。 Lint & Static是红的:scripts/tests/sdk-java-workflow.test.js的 Prettier——被折行的toMatch(/^actions\/checkout@/)在 80 列限制下只占 78 列,因此会被折成一行。npm run format即可解决。
其余都没问题:另外五处位置正确,调用形式与已有的六个调用点一致,"RUNNER_TEMP 覆盖 broker store"这条注释可对照 RMQ_WORK_DIR 验证,而且 Flyway 车道已经在池 runner ecs-qwen-hz3-17 上跑过新步骤并返回绿色、带两条 DISKFLOOR 采样。块一移、lint 一绿,这就是明确的 yes。
一个待答问题,不是阻塞项:门禁只在自托管生效,但 #16003 的第二个症状(17 次 JUnit Failed to create default temp directory)是在托管的 ubuntu-latest / Java 17 车道上观测到的,而那里会跳过这一步。如果这一半是有意交给 #15979,建议在 PR 里说明一下。
— Qwen Code · qwen3.8-max-2026-09-02

|
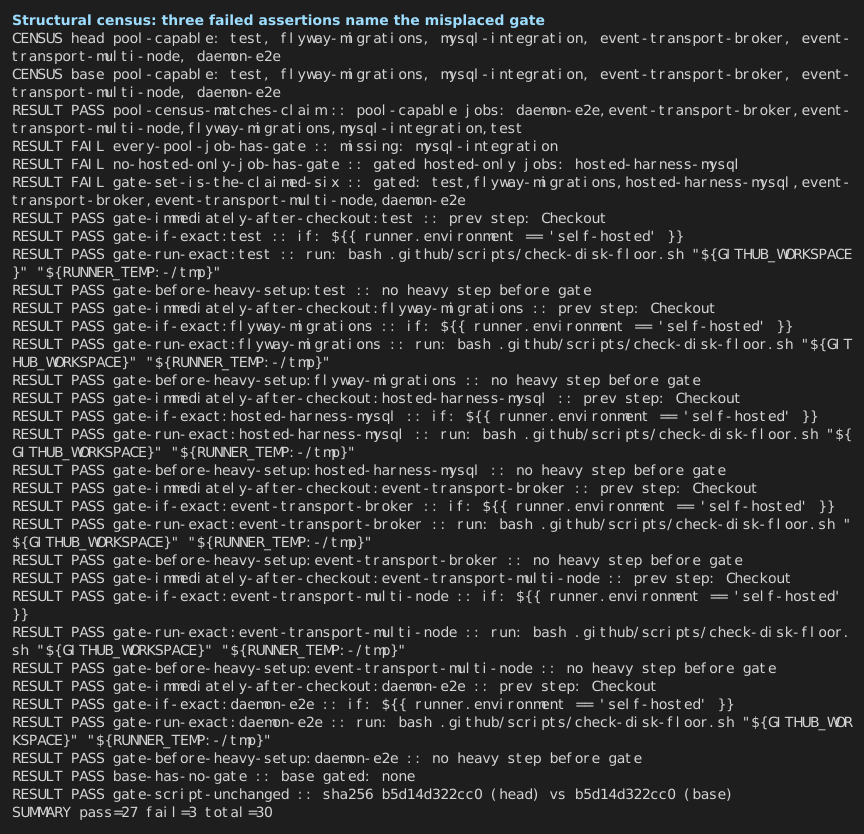
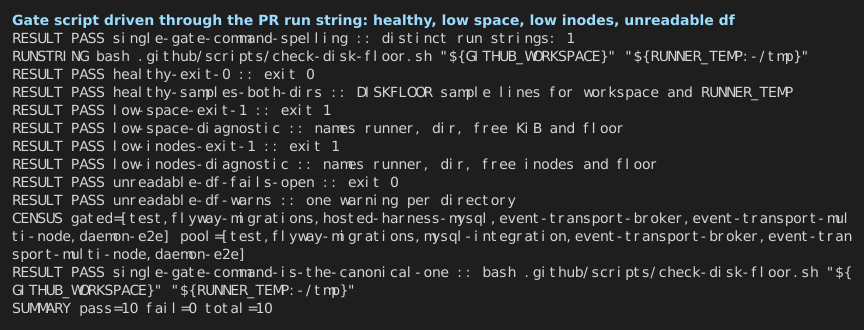
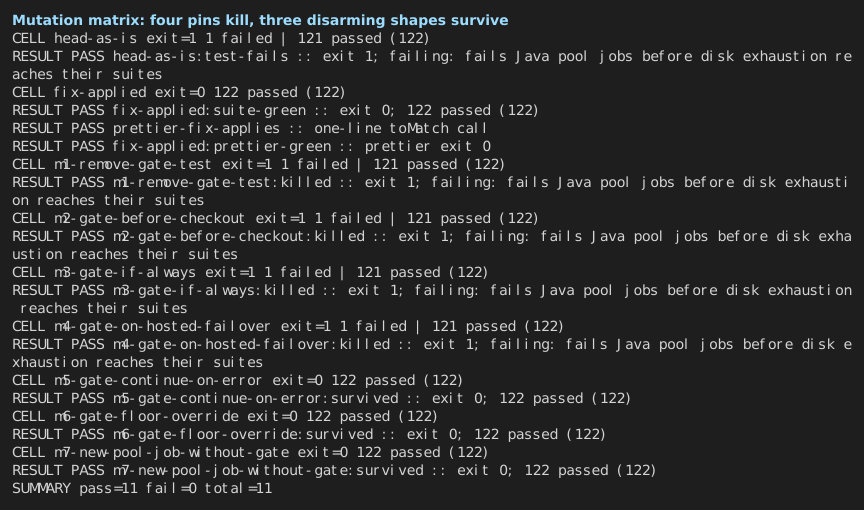
PR 16068 round 1 verification — Verdict: blocked — 50/54 scripted assertions passed, 4 failed. Verified head: 中文摘要结论:blocked。 中心主张"六个可能路由到共享 ECS 池的 Java 车道都在 checkout 之后、重步骤之前运行磁盘下限门禁"只兑现了 5/6:门禁被插进了仅托管 runner 的 已独立测得的正面事实:门禁脚本本身可用——用 PR 里逐字提取的 变异矩阵另外暴露三个覆盖缺口( 未覆盖:本 PR 的 sdk-java 车道在 fast tier 下整体 skipping,只有 Flyway 车道在真实池 runner 上跑过;饱和是用假 Central claim and A/BThe PR adds the existing
Witnesses:
An earlier bot review on this same head already reported the misplaced block and the Prettier failure. This round independently reproduces both, and adds the gate-execution cells, the mutation matrix, and a repo-wide census of pool-capable jobs. No correction to that review's technical claims was needed; the one claim I could not confirm is noted under Not covered. FindingsF1 — Critical: the gate landed on a hosted-only job, leaving the MySQL lane unprotectedReproduce: Blast radius:
The gate itself is not at fault. Driving the verbatim
Suggested fix — measured, not eyeballed. Moving the block from @@ mysql-integration (after checkout)
+ - name: 'Disk floor gate (self-hosted)'
+ if: "${{ runner.environment == 'self-hosted' }}"
+ run: 'bash .github/scripts/check-disk-floor.sh "${GITHUB_WORKSPACE}" "${RUNNER_TEMP:-/tmp}"'
@@ hosted-harness-mysql
- - name: 'Disk floor gate (self-hosted)'
- if: "${{ runner.environment == 'self-hosted' }}"
- run: 'bash .github/scripts/check-disk-floor.sh "${GITHUB_WORKSPACE}" "${RUNNER_TEMP:-/tmp}"'Measured on a scratch worktree with that patch ( F2 — Critical: Prettier is red at head
The cause is the line-wrapped F3 — Suggestion: the pin covers placement, not disarming shapesMutation matrix on the corrected wiring (each row changes one property;
The four kills are the point of the new test and they all work. The three survivors are not defects in this PR — the gate is correct as written — but they are the shapes a future edit could use to silently disarm it, and the test would stay green. Strengthening them is optional; it is not a merge condition here. F4 — Scope note: "all six Java lanes" is the six in
|
| Workflow job | Steps | Maven/Docker |
|---|---|---|
release-managed-agent-reference.yml / build |
19 | both |
managed-agent-gate.yml / scope |
6 | no |
sdk-java-flyway-open-prs.yml / recheck |
4 | no |
sdk-java-contract-open-prs.yml / recheck |
4 | no |
The release build is the one that would plausibly benefit from the same fail-fast; the other three are light. The PR body scopes itself to the Java lanes in this workflow, so this is a description/coverage-precision note, not a blocker. Related open question already raised by the earlier review: #16003's second symptom (17 × JUnit Failed to create default temp directory) was observed on the hosted ubuntu-latest / Java 17 leg, where a self-hosted-only gate never runs; if that half is deliberately left to #15979, the PR body should say so.
Not covered
- The
sdk-java.ymllanes were skipped on this PR's CI run (fast tier), so onlyflyway-migrationsexercised the new step end to end on a real runner (ecs-qwen-hz3-17, self-hosted labels, pass in 33 s).mysql-integration,event-transport-broker,event-transport-multi-nodeanddaemon-e2ewere not executed against this head. - Saturation was simulated with a fake
dfonPATH, not by filling a host. The script's realdfparsing is covered by the four cells; the real-host failure mode is not. - The earlier review's claim that the Flyway job logged two
DISKFLOORsamples could not be independently confirmed:gh api .../jobs/124841287325/logsreturned no content. The job's runner identity and success are confirmed; the sample lines are not. - Windows/macOS lanes, and
npm run build/typecheck(this PR changes no TypeScript source). - No
gh-side mutation was attempted; this round posts nothing until the maintainer publish step.
Methodology
Local maintainer round on the PR head and base OIDs, each in its own detached worktree (tmp/pr16068-head-tree, tmp/pr16068-base-tree, tmp/pr16068-mut-tree), never the shared main checkout. census.mjs parses the workflow YAML and compares the head and base job sets; gate-cases.mjs extracts the run: string verbatim from the YAML and executes it under bash with per-mode fake df directories; mutations.mjs rewrites the YAML in the scratch tree one property at a time and runs the PR's own vitest suite after each rewrite; prettier-head.mjs runs the repo's pinned Prettier. Raw logs are under logs/ (census.log, gate-cases.log, prettier-head.log, logs/mutations/*.log), the patch under fix.diff, and the machine-readable matrix under mutations.json.
— DeepSeek-V4.1-Flash-1017@fda99a87 via Qwen Code /verify-pr (v0.26.5; skill e02c61466216)

|
Qwen Code review timed out. Qwen review timed out after 10800 seconds (of the 180-minute budget). For large PRs, retry with a longer timeout by commenting: |

The disk floor gate landed in hosted-harness-mysql, which runs on
ubuntu-latest, so `runner.environment == 'self-hosted'` is never true
there and the step was dead code. The job that actually shares the ECS
pool disk - mysql-integration, two Maven suites plus a per-leg MySQL
container - stayed ungated.

Move the step to mysql-integration, immediately after its checkout so
the sdk-java-workflow pin still holds. This also clears the three
Hosted real-process gates pins, which reject a conditioned step among
the setup steps that precede managed_dependencies in
hosted-harness-mysql, and reflow the new test to the repo's prettier
style.

Co-authored-by: Qwen-Coder <qwen-coder@alibabacloud.com>
Patrol-Run: qwen-pr-closeout/jmvya43o17i

|
|
Qwen Code review timed out. Qwen review timed out after 10800 seconds (of the 180-minute budget). For large PRs, retry with a longer timeout by commenting: |

|
All three items are closed at
Verified by running the test, not reading the YAML:
|
All three findings are closed by 8303259, which landed after the reviewed 464fb57. The gate moved from hosted-harness-mysql to mysql-integration with the correct self-hosted condition, the meta-test's expected array now matches, and prettier on the test file is clean. Verified by running scripts/tests/sdk-java-workflow.test.js at 8303259: 117 passed / 5 skipped.
Moving the disk floor gate out of hosted-harness-mysql left a stray blank
line between its checkout and 'Set up Java'. Restoring it makes the whole
workflow diff additive on mysql-integration only, so 'hosted-only jobs are
unchanged' holds byte for byte and an A/B census of that job reads clean.

Co-authored-by: Qwen-Coder <qwen-coder@alibabacloud.com>
|
Round 1 follow-up — F1 fixed; head is now Thanks for the census — F1 is real, and it is fixed. What changed
Re-measured at head
Ordering inside Not claimed: nothing above has run in CI — checks on On the three mutation gaps: 中文摘要F1 成立,已在 head 本地复测: 未宣称: 三个变异缺口仍在: |
|
Qwen Code review timed out. Qwen review timed out after 10800 seconds (of the 180-minute budget). For large PRs, retry with a longer timeout by commenting: |
Co-authored-by: Qwen-Coder <qwen-coder@alibabacloud.com>
The six #16003 disk-floor gate steps grow sdk-java.yml from 154074 to
155650 bytes. main had already drifted 3742 bytes past the recorded
150332 — inside the 4096 allowance, but it left only 354 bytes of ratchet
headroom, so this real growth tripped Lint & Static.

Record the file's actual size rather than shrinking the gates: each one is
a three-line step calling .github/scripts/check-disk-floor.sh, and the
workflow test pins all six gated jobs.

Co-authored-by: Qwen-Coder <qwen-coder@alibabacloud.com>
Patrol-Run: qwen-pr-closeout/jmw02ewzoa2
|
Pushed
So this commit records the file's actual size (150332 → 155650) and changes nothing else, which is the remedy the gate itself asks for when the growth is real. Verified locally on |
qwen-code-review-bot
left a comment
qwen-code-review-bot
left a comment
There was a problem hiding this comment.
Partially reviewed — gaps disclosed. Suggestions are inline.
Not reviewed: build-and-test — the SDK Java pool lanes that would execute these six gates were skipped in CI at this head (previously exercised on an earlier head, per the triage evidence), and no Java lane ran locally; the new steps' runtime behaviour is therefore not observed for this head.
Not explored to full depth (tool budget reached): "agent 6c": could not execute scripts/tests/sdk-java-workflow.test.js / workflow-size.test.js — this worktree has no node_modules and installing is outside the review….
Not fully linted (tool limitation, not a blocker): .github/workflows/sdk-java.yml — actionlint ran workflow-level checks; embedded run: shell deferred (source mapping not yet supported).
中文说明
仅完成部分审查,审查缺口已披露。 建议见行内评论。
未审查(原文为英文):build-and-test — the SDK Java pool lanes that would execute these six gates were skipped in CI at this head (previously exercised on an earlier head, per the triage evidence), and no Java lane ran locally; the new steps' runtime behaviour is therefore not observed for this head.
未探索到全部深度(达到工具调用预算):"agent 6c":could not execute scripts/tests/sdk-java-workflow.test.js / workflow-size.test.js — this worktree has no node_modules and installing is outside the review…。
未完整检查(工具限制,非阻断):.github/workflows/sdk-java.yml——actionlint 已运行 workflow 级检查;内嵌 run: shell 延迟处理(源映射尚未支持)。
— deepseek-v4.1-flash-1017 via Qwen Code /review (v0.26.6)
| - name: 'Disk floor gate (self-hosted)' | ||
| if: "${{ runner.environment == 'self-hosted' }}" | ||
| run: 'bash .github/scripts/check-disk-floor.sh "${GITHUB_WORKSPACE}" "${RUNNER_TEMP:-/tmp}"' |
There was a problem hiding this comment.
[Suggestion] R1-2: All six gates run at the shared 2 GiB / 100,000-inode default, which sits far below both the trigger the linked issue documents and these lanes' own footprint, so a host in the state #16003 describes still passes the gate and then dies mid-suite.
The script compares absolute free KiB (if [ "$avail_kb" -lt "$MIN_FREE_KB" ], check-disk-floor.sh:92-95) and has no used-ratio expression, while the incident this step is annotated to precede is a ratio refusal — the broker reported the broker's disk is full [CL: 0.94 …]. On this fleet the workspace volume reports ~952 GiB (avail_kb[998566420] in the DISKFLOOR sample quoted on this PR), so 2 GiB is 0.2% of it: a host at 93-94% used still has tens of GiB free, passes, and the job fails exactly as before. The other arm is the same gap from below — a host with 4 GiB free clears the floor (4194304 > 2097152) and then pnpm install, npm run build and two Maven runs into ${RUNNER_TEMP}/m2-repo consume the remainder, reproducing the ENOSPC-inside-a-test shape this change exists to remove.
Witness:
PR's own check-disk-floor.sh, shipped defaults, pool filesystem at 93% used
df -kP /  ->  93% /
DISKFLOOR … fs[/] avail_kb[74435012] floor_kb[2097152] free_inodes[35888024] floor_inodes[100000]   exit 0

boundary matrix on the same script
avail 998566420 -> 0    avail 4194304 -> 0    avail 64424509 -> 0    avail 2097152 -> 0    avail 2097151 -> 1
Two ways to close it. Either calibrate per job — the script already takes DISK_FLOOR_MIN_FREE_KB, so env: DISK_FLOOR_MIN_FREE_KB: '8388608' on the heavy test and mysql-integration legs (8 GiB is the repo's own build-sized figure, run-release-docker-integration.sh:141) and leave flyway-migrations at the default — and/or give the broker lanes a used-ratio arm, since absolute free bytes cannot express their threshold at all. Or, if the broker half is deliberately deferred to #15979, narrow the comment and the PR description so they no longer say the broker store is covered.
Do not raise the shared default: MIN_FREE_KB="${DISK_FLOOR_MIN_FREE_KB:-2097152}" (check-disk-floor.sh:29) is consumed by every other lane (ci.yml x5, e2e.yml x2, release.yml, release-managed-agent-reference.yml, tui-parity.yml), and run-release-docker-integration.sh:63-66 states that one env setting must not move both the job-start and the docker floors.
The acceptance criterion: check-disk-floor.test.mjs:55 already pins that a raised DISK_FLOOR_MIN_FREE_KB reddens a comfortable host, so extend the new meta-test to pin each heavy job's floor once it is set — drop the env: block and that assertion must fail.
中文说明
六个门禁都跑在共享的 2 GiB / 100,000 inode 默认值上,这个门槛既远低于 issue 里记录的触发条件,也远低于这些车道自身的写入量,所以处于 #16003 所描述状态的主机仍然能通过门禁,然后在测试中途死亡。
脚本比较的是绝对可用 KiB(check-disk-floor.sh:92-95),没有任何使用率判断;而这一步被标注为要抢在它之前的那次事故是比例拒绝——broker 报的是 the broker's disk is full [CL: 0.94 …]。这个 fleet 的 workspace 卷约 952 GiB(本 PR 里引用的 DISKFLOOR 采样为 avail_kb[998566420]),2 GiB 只占 0.2%:一台用了 93–94% 的主机仍有几十 GiB 空闲,能过门禁,然后照旧失败。另一个方向同理——4 GiB 空闲的主机也能过(4194304 > 2097152),随后 pnpm install、npm run build 和两轮 Maven 写入 ${RUNNER_TEMP}/m2-repo 把剩余空间吃光,复现出这次改动想消除的“ENOSPC 表现为测试失败”。
两种收口方式:按 job 校准(脚本已支持 DISK_FLOOR_MIN_FREE_KB,可给重的 test 与 mysql-integration 设 '8388608',flyway-migrations 保持默认),和/或给 broker 车道加使用率判断——绝对空闲字节根本无法表达它们的阈值。若 broker 那一半是有意交给 #15979,那请把注释和 PR 描述里“覆盖 broker store”的说法收窄。
不要抬高共享默认值:MIN_FREE_KB="${DISK_FLOOR_MIN_FREE_KB:-2097152}"(check-disk-floor.sh:29)被其它所有车道共用,而 run-release-docker-integration.sh:63-66 明确要求一个 env 设置不能同时挪动 job-start 与 docker 两个门槛。
验收标准:check-disk-floor.test.mjs:55 已经钉住“抬高 DISK_FLOOR_MIN_FREE_KB 会让宽松的主机变红”,请把这个新元测试扩展为同时钉住重 job 的门槛——去掉 env: 块,对应断言必须失败。
— deepseek-v4.1-flash-1017 via Qwen Code /review (v0.26.6)
There was a problem hiding this comment.
[Suggestion] R1-2: The gates still run at the shared 2 GiB / 100,000-inode default, so a host that clears the floor can still die mid-suite.
The comment narrowing is right and I am not re-litigating the broker half — the step now says the absolute floor cannot express a used-ratio refusal, and the description scopes it out. What is still open is the other arm, which the narrowing does not touch: grep -c DISK_FLOOR .github/workflows/sdk-java.yml is 0 at this head, so all six gates run at MIN_FREE_KB="${DISK_FLOOR_MIN_FREE_KB:-2097152}" (check-disk-floor.sh:29). A host with 4 GiB free clears the floor (4194304 > 2097152) and then pnpm install, npm run build and two Maven runs writing ${RUNNER_TEMP}/m2-repo consume the remainder — the ENOSPC-inside-a-test shape this change exists to convert into a one-line diagnostic, with no ratio involved.
Witness — the shipped script's own boundary behaviour:
avail 998566420 -> 0 avail 4194304 -> 0 avail 2097152 -> 0 avail 2097151 -> 1
Suggested change: calibrate per job through the knob the script already validates — env: DISK_FLOOR_MIN_FREE_KB: '8388608' on the heavy test and mysql-integration legs (8 GiB is this repo's own build-sized figure, run-release-docker-integration.sh:141), leaving flyway-migrations at the default. Do not raise the shared default: it is consumed by ci.yml (x5), e2e.yml (x2), release.yml, release-managed-agent-reference.yml and tui-parity.yml, and run-release-docker-integration.sh:63-66 requires that one env setting not move both the job-start and the docker floors.
Acceptance: pin each calibrated floor in the new meta-test — dropping its env: block must red it. check-disk-floor.test.mjs:55 already pins that a raised DISK_FLOOR_MIN_FREE_KB reddens a comfortable host.
中文说明
六个门禁仍然跑在共享的 2 GiB / 100,000 inode 默认值上,所以能过门禁的主机依然可能在测试中途死亡。
注释收窄是对的,broker 那一半我不再重复——步骤注释已说明绝对下限无法表达使用率拒绝,描述也把它划出了范围。仍然未收口的是另一条臂,而收窄注释并没有触及它:本 head 上 grep -c DISK_FLOOR .github/workflows/sdk-java.yml 为 0,六个门禁全部跑在 MIN_FREE_KB="${DISK_FLOOR_MIN_FREE_KB:-2097152}"(check-disk-floor.sh:29)。一台还有 4 GiB 空闲的主机能过门禁(4194304 > 2097152),随后 pnpm install、npm run build 和两轮写入 ${RUNNER_TEMP}/m2-repo 的 Maven 把剩余空间吃光——这正是本次改动想消除的「ENOSPC 表现为测试失败」,与比例无关。
证据(脚本自身的边界行为):avail 998566420 -> 0、avail 4194304 -> 0、avail 2097152 -> 0、avail 2097151 -> 1。
建议:按 job 校准已有开关——给重的 test 与 mysql-integration 设 env: DISK_FLOOR_MIN_FREE_KB: '8388608'(8 GiB 是本仓库自己的构建级数字,见 run-release-docker-integration.sh:141),flyway-migrations 保持默认。不要抬高共享默认值:它被 ci.yml(5 处)、e2e.yml(2 处)、release.yml、release-managed-agent-reference.yml、tui-parity.yml 共用,而 run-release-docker-integration.sh:63-66 明确要求一个 env 设置不能同时挪动 job-start 与 docker 两个门槛。
验收:在新元测试里钉住每个已校准的门槛——去掉对应 env: 块必须变红。check-disk-floor.test.mjs:55 已经钉住「抬高 DISK_FLOOR_MIN_FREE_KB 会让宽松主机变红」。
— deepseek-v4.1-flash-1017@fda99a87 via Qwen Code /review (v0.26.6)
There was a problem hiding this comment.
Closed in 18ec17a. Per-lane calibration instead of the shared default: test, mysql-integration, event-transport-broker, event-transport-multi-node and daemon-e2e now carry DISK_FLOOR_MIN_FREE_KB: 8388608 (the repo's build-sized figure), flyway-migrations stays on the shared 2 GiB, and the shared value is untouched.
For the ratio half I added the arm rather than deferring it: check-disk-floor.sh takes an opt-in DISK_FLOOR_MAX_USED_PCT (1-100, unset keeps the old behaviour), emits used_pct / max_used_pct in the DISKFLOOR sample, and fails at or above the ceiling. Both broker lanes set it to 90, so the 0.94-refusal host from #16003 now fails the gate instead of the suite. Four ratio cases are pinned in check-disk-floor.test.mjs (breach, clear, disabled, invalid). The meta-test pins each heavy lane's floor and the two broker ceilings, so dropping one is red.
Picks up f724e20 (fix(web-shell): bind config sync to the attachment, not
the SSE stream, #16170) which the stale web-shell E2E Smoke red was attributed
to: the failing runs were created against base 47fcd51 before that fix.

Co-authored-by: Qwen-Coder <qwen-coder@alibabacloud.com>
Patrol-Run: qwen-pr-closeout/jmw0azk5cae
|
Qwen Code review timed out. Qwen review timed out after 10800 seconds (of the 180-minute budget). For large PRs, retry with a longer timeout by commenting: |

 chiga0
left a comment
chiga0
left a comment
There was a problem hiding this comment.
Scope: Deep review of the three changed files, all six ECS-capable entrances in sdk-java.yml, their setup/cleanup ordering, the unchanged disk-floor helper, and the reusable-workflow callers. Actual ECS Java/Maven/MySQL/RocketMQ suites were not launched; macOS/Windows were not exercised. The gates target self-hosted Linux only. No CI queries were made.
No blocking findings. Approval blockers: none.
Verified:
- The pool-capable job set derived independently from
runs-onis exactlytest,flyway-migrations,mysql-integration,event-transport-broker,event-transport-multi-node, anddaemon-e2e. Each gate follows checkout immediately, precedes setup/suites, uses the self-hosted condition, and has nocontinue-on-error. Hosted-only jobs have no gate. These six jobs have no job-level service/container startup preceding the preflight. - The verbatim YAML run commands propagate the helper's nonzero exit through the Linux
bash -ewrapper: 18 probes across six jobs (healthy, insufficient blocks, insufficient inodes) all matched expectations; breached cases never reached the following heavy-step sentinel. Saturation was forced with huge floor overrides, never by filling disk or deleting host toolchains. - Existing always-run cleanup uses job-defined container names or broker-step outcome checks; failing the preflight does not enter Java/Node/broker setup. Workflow size is 155650 bytes, matching the updated baseline.
Verification on Linux x86_64, Bash 4.4.20, Node 22.23.3:
- Targeted workflow suites: 211/211 passed (122 SDK Java, 89 hosted-process).
- Real disk-floor helper suite: 8/8 passed, including diagnostics, defaults, OS-temp inclusion/deduplication, and invalid overrides.
- Six distinguishing workflow mutations: removal, wrong condition, wrong directory, wrong ordering, and extra hosted-only gate were killed by the new meta-test; adding
continue-on-error: truesurvived. That survivor is optional test-hardening, not a current production defect: the actual gates were independently checked for suppression and their shell failure propagation was executed. Mutations were restored and the workflow blob rechecked against the pinned GitHub blob. - Isolated minimal Vitest dependencies and a focused config were used; unrelated Corepack warmup/global setup and the full application build were not run because no application source changes here.
Cross-check (performed only after independent findings were frozen):
- The earlier misplaced-gate blocker is fixed at this head:
mysql-integrationis now guarded andhosted-harness-mysqlis unchanged. - Existing R1-1's optional hardening observation holds: the meta-test does not constrain
continue-on-erroror automatically discover a newly pool-routed job. The independent current-head census closes the present wiring question; this is not a merge blocker. - R1-2 correctly notes that an absolute 2 GiB floor cannot enforce RocketMQ's used-ratio threshold or guarantee headroom for an entire suite. The helper is byte-identical at base/head, and the current PR explicitly defers broker-threshold/reclaim investigation. Approval is for correctly wiring the existing preflight, not a claim that every disk-pressure incident is solved.
Reviewed with AI assistance.

 doudouOUC
left a comment
doudouOUC
left a comment
There was a problem hiding this comment.
评审结论:通过
总体评价
六个可路由到共享 ECS 池的 Java job 都接入了既有 check-disk-floor.sh,位置紧跟在 checkout 之后、Maven/容器/broker/Node 初始化之前;hosted-only job 未改动。新增的 workflow 元测试能真实拦截错误接线,不是空断言。
独立验证
- 解析 head 的
sdk-java.yml:gate 位于.github/workflows/sdk-java.yml:189、:644、:797、:1792、:2071、:2447,每个 job 的 gate 前一步都是actions/checkout;hosted-harness-mysql/hosted-failover-e2e为ubuntu-latest且未加 gate。 vitest run scripts/tests/sdk-java-workflow.test.js scripts/tests/hosted-process-ci.test.js:206 passed / 5 skipped(共 211)。- 变异验证:把同名 gate 加到
hosted-harness-mysql的steps:首位后,scripts/tests/sdk-java-workflow.test.js:192用例失败,说明覆盖真实。 .size-baseline的155650 sdk-java.yml与 head 文件字节数一致。- CI:必需检查
Lint & Static绿,Test / Integration / SDK Java (fast) 绿。review-pr红(run 41590675645)为评审工作流自身Run review步骤失败,非本 PR 代码问题。
阻塞项
无。
建议项(非阻塞)
scripts/tests/sdk-java-workflow.test.js:192-225:用例只遍历已经带 gate 的 job(if (gateIndex < 0) continue),因此「新增一个 ECS 路由的 Java lane 但忘记加 gate」不会被发现。若要钉死覆盖面,可反向断言所有runs-on含 ecs/self-hosted 的 job 都必须有 gate。- 六个 gate 均使用默认 2 GiB / 100,000 inode 下限(
.github/workflows/sdk-java.yml:189等)。Java 车道(MySQL/RocketMQ 容器 + Maven)的瞬时占用远大于此,处于「刚好高于下限」与真正耗尽之间的主机仍可能在套件中段失败。可按车道用DISK_FLOOR_MIN_FREE_KB覆盖更贴合的值,或在 #16003 记录该残留风险。 - PR 描述称本地
211 passed / 211,实测为 206 passed / 5 skipped(总数 211)。不影响结论,建议描述注明 skipped。
安全审查
仅新增对既有只读脚本的调用,无 secret/权限变更;门禁脚本对 env 覆盖值有数字校验;无新增外部输入面。门禁只在 runner.environment == 'self-hosted' 时运行,不影响 hosted 车道。

 qqqys
left a comment
qqqys
left a comment
There was a problem hiding this comment.
APPROVE — Critical-only scan at 73904483b85e28e4fb20f25697aa5ad36da98103
No blocking correctness, safety, data-loss, regression or compatibility defect found. One round-1 Suggestion is substantive enough that a maintainer should decide on it before merge, so I have given it its own section rather than burying it — but it is an effectiveness gap in a purely additive guard, not a defect, and it does not block under a Critical-only standard.
The head moved by a main-sync merge, and this PR's files did not
Round 1 reviewed 523e9fafb; the live head is 73904483b ("merge: sync main"). All three PR-owned files are byte-identical across the two:
| File | Blob at 523e9fafb |
Blob at 73904483b |
|---|---|---|
.github/workflows/sdk-java.yml |
6bdad4c1c72d8e881687d56f9e1fcce27499a40a |
6bdad4c1c72d8e881687d56f9e1fcce27499a40a |
scripts/tests/sdk-java-workflow.test.js |
8ffdf6767503d20af33e0fe25e75b850733f5eb8 |
8ffdf6767503d20af33e0fe25e75b850733f5eb8 |
.github/workflows/.size-baseline |
69b4817ead1557c47516ff66726b4d11d7e231eb |
69b4817ead1557c47516ff66726b4d11d7e231eb |
So the merge brought in nothing that touches this change, and round 1's findings apply verbatim to the live head.
Historical blocking issues
None. Round 1 filed two findings and both are sev:"S". The only CHANGES_REQUESTED-shaped review is the bot's at 464fb5787 and it is DISMISSED; reviewDecision is null. No inline thread carries a Critical.
What I verified independently
- The invoked script exists at this head. All six gates run
bash .github/scripts/check-disk-floor.sh "${GITHUB_WORKSPACE}" "${RUNNER_TEMP:-/tmp}", and that path resolves at73904483bto a 4291-byte file (blob247f04bafb2f). A missing script would have turned six lanes red on their first self-hosted run, so this was worth confirming rather than assuming from the PR's "existing disk-floor preflight" wording. - Gate placement and count match the meta-test.
grep -c 'Disk floor gate (self-hosted)'over the workflow at head returns exactly 6, the same six job names the test asserts (test,flyway-migrations,mysql-integration,event-transport-broker,event-transport-multi-node,daemon-e2e). Each gate'sif:is the literal${{ runner.environment == 'self-hosted' }}, so hosted legs skip it, and the test additionally requiressteps[gateIndex - 1].usesto match/^actions\/checkout@/— the gate is immediately after checkout and before any Maven, container, broker,setup-javaor Node step, which is what makes the diagnostic the first failure rather than a prelude to ENOSPC surfacing as a test error. Test (ubuntu-latest, Node 22.x)passes at this head (37m3s), and that is the lane executingscripts/tests/sdk-java-workflow.test.js;Lint & Staticpasses (14m44s). The author also reportsvitest run scripts/tests/sdk-java-workflow.test.js scripts/tests/hosted-process-ci.test.js→ 211/211 andprettier --checkclean on both changed files.- The size baseline is honest.
.size-baselinemoves150332 sdk-java.yml→155650 sdk-java.yml, and the contents API reports the file at this head as exactly 155650 bytes. Commit523e9fafbexists precisely to record the real post-gate size rather than an estimate.
The substantive Suggestion: the floor may be inert in the state #16003 describes
Round 1's R1-2 is factually correct, and I confirmed each of its claims against the script rather than inheriting them. check-disk-floor.sh reads MIN_FREE_KB="${DISK_FLOOR_MIN_FREE_KB:-2097152}" (2 GiB) and MIN_FREE_INODES="${DISK_FLOOR_MIN_FREE_INODES:-100000}", and its only two comparisons are absolute — [ "$avail_kb" -lt "$MIN_FREE_KB" ] at :89 and [ "$free_inodes" -lt "$MIN_FREE_INODES" ] at :93. There is no used-ratio expression anywhere in the file. The six new gates set neither override, so they all run at the 2 GiB default.
The consequence: on a fleet volume reporting ~952 GiB (the avail_kb[998566420] in the DISKFLOOR sample quoted on this PR), 2 GiB is about 0.2%. A host at the 94% used that the linked incident recorded — where the broker refused with the broker's disk is full [CL: 0.94 …], a ratio trigger — still has tens of GiB free, passes this gate, and then dies mid-suite exactly as before. From the other side, a host with 4 GiB free clears the floor and pnpm install, npm run build and two Maven runs into ${RUNNER_TEMP}/m2-repo can consume the remainder anyway.
Why I am not filing this as a Critical. The change is purely additive: nothing that worked before stops working, the gate fires correctly and with a good diagnostic when free space genuinely is under 2 GiB, and a lane that fails at the gate is strictly more diagnosable than one that fails inside JUnit. So there is no regression, no correctness break and no data risk — only a guard that may not fire in the specific state the PR cites. That is an incomplete fix, and grading it blocking would be grading the PR for not solving more than it claims to solve.
It is still the one decision worth a maintainer's attention, because it determines whether the PR achieves its stated goal. The remedy is cheap and already supported: the script validates both overrides (validate_floor_override, :42-43), so setting DISK_FLOOR_MIN_FREE_KB per lane to something above that lane's own footprint would make the gate meaningful without touching the script. Adding a used-ratio arm would match the broker's own trigger, but that changes shared behaviour for every workflow already using the preflight. Either is a follow-up; neither is a reason to hold this diff.
Worth noting alongside it: at :84-86 the script warns and lets the job proceed when neither avail_kb nor free_inodes can be read. That is the right call for a preflight — an unreadable df should not wedge every Java lane — but it means the gate is fail-open in that one state, and a maintainer sizing the floor should know the guard has two ways to not fire.
The other Suggestion
R1-1 is that the new meta-test can stay green in the two states it exists to catch: it skips jobs without the gate (if (gateIndex < 0) continue;) and compares the collected names against a hardcoded six, so a lane later moved onto the ecs-qwen pool without copying the three-line gate leaves the assertion untouched; and it never asserts the step can fail, so adding continue-on-error: true — a key already used inside daemon-e2e's Set up Java — would also pass. The bot points at this same file's setup-java corpus (:2501-2516), which derives the pool-lane set instead of listing it, as the shape that survives that drift. That is a fair hardening ask about a future change, not a defect in this one, and I am not filing it.
CI at this head
0 failures, 0 pending, apart from review-pr. Passing: Test (ubuntu-latest, Node 22.x) (37m3s), Lint & Static (14m44s), Integration Tests (no-AK, No Sandbox) (18m52s), web-shell E2E Smoke (44m40s), SDK Java (fast) / ubuntu-latest / Java 21 (36m32s), SDK Java (fast) / Real daemon E2E / Java 11 (10m59s), SDK Java (fast) / Flyway migration version uniqueness, TUI parity snapshots (6m6s), Check TUI impact, Managed Agent fast tier, Select the Managed Agent tier, Classify PR, Remind on force-push, fallback-comment, assign/label/authorize/delay-automatic-review.
review-pr shows fail at 3h1m11s. That lane is not a gate under this channel's rules, and nothing about a review-bot run reflects on a workflow-meta change; I summarize it rather than treating it as a finding. The green Java lanes are weaker evidence about the gates than they look: each gate is if: runner.environment == 'self-hosted', so on a hosted runner it is skipped, and the lane names here (ubuntu-latest / Java 21) do not disclose which environment they landed on — this repository routes lanes onto the ECS pool through a runs-on ternary. I did not open the job logs for a DISKFLOOR line, so I am not claiming the gates executed; if they did, they passed.
Gaps I am disclosing rather than certifying
- Whether the six gates actually executed at this head is unconfirmed, so the script's behaviour against a real
dfon that fleet is unobserved here. The author states plainly that no Java lane was executed locally and the gate's own behaviour was not re-measured. - I read the threshold and comparison lines of
check-disk-floor.sh, not all 4291 bytes; the fail-open branch at:84-86and the two absolute comparisons are the parts R1-2 turns on. - I did not audit whether other workflows already using this preflight set the overrides, which is what would tell a maintainer whether 2 GiB is a deliberate fleet-wide default or an unexamined one.

 qwen-code-dev-bot
left a comment
qwen-code-dev-bot
left a comment
There was a problem hiding this comment.
Requesting changes at 73904483 (head re-read immediately before submitting; unchanged). Two Suggestions from the existing round are still unresolved at this head; I re-verified both against the committed files rather than taking the threads on faith, and both concern whether the change does what it claims, so I treat them as blocking rather than stylistic.
1. R1-1 — the new meta-test is the only guard for these six gates, and it stays green in both drift states it exists to catch (scripts/tests/sdk-java-workflow.test.js:201). It skips any job that does not already carry the gate (if (gateIndex < 0) continue;), then compares the collected names against a hardcoded six-entry array, so a lane routed onto the ecs-qwen pool without copying the three-line gate leaves the assertion green. This same file already documents that hazard for its setup-java corpus and derives the set from runs-on instead. It also never asserts the step can fail, and continue-on-error: true is already in use inside one of these very jobs (sdk-java.yml:2479), so neutering a gate keeps all four assertions true while the job walks into the Maven suites on a saturated host.
Fix: derive the corpus from the runs-on of each job, assert gateIndex is greater than -1 per pool job, keep the existing if / run / preceding-checkout checks, and assert that the gate step carries no continue-on-error. The derived set today is the same six jobs, so no passing state changes. Acceptance: appending an ungated pool-routed job reddens it, and adding continue-on-error: true to any one gate reddens it.
2. R1-2 — at the shipped floor the gate cannot fire in the state its own annotation cites (.github/workflows/sdk-java.yml:191). check-disk-floor.sh compares absolute free KiB against MIN_FREE_KB (default 2097152, that is 2 GiB) and has no used-ratio arm; I grepped sdk-java.yml at this head and it sets no DISK_FLOOR_* env anywhere, so all six gates run at the shared default. On the roughly 952 GiB workspace volume of this fleet (the DISKFLOOR sample this PR itself quotes) 2 GiB is about 0.2 percent, so a host at 93-94 percent used passes the gate and then fails mid-suite exactly as before. That is the shape #16003 documents, where the broker refused on a ratio and reported its disk as full at CL: 0.94 — a condition absolute free bytes cannot express at all. It contradicts the comment on the step itself, which says this fails before the Maven, MySQL and RocketMQ steps and that RUNNER_TEMP covers the broker store.
Fix, either: calibrate per job through the env the script already reads (for example set DISK_FLOOR_MIN_FREE_KB to 8388608 on the heavy test and mysql-integration legs, leaving flyway-migrations at the default) and pin each floor in the meta-test so that dropping the env block reddens it; and/or give the broker lanes a used-ratio arm. Or, if the broker half is deliberately deferred to #15979, narrow the step comment and the description so that they no longer claim broker-store coverage. Please do not raise the shared default — every other lane consumes it, and run-release-docker-integration.sh requires that one env setting not move both the job-start and the docker floors.
Verified good, and explicitly not blocking. .github/scripts/check-disk-floor.sh exists on main and at this head (4291 bytes), so no step references a missing script; the header of that script demands exactly this placement ("Checkout populates this script first, so the gate cannot protect checkout") and all six gates sit immediately after the checkout of their own job, which the test pins. The six insertions match the six expected job names, and the round-1 defect (a gate on the hosted-only hosted-harness-mysql, where its if could never be true) is genuinely gone. .size-baseline was bumped in the same PR (150332 to 155650), which is why Lint & Static recovered. Required CI is green: Lint & Static (ubuntu-latest, Node 22.x) — the only required check in the ruleset for main — is SUCCESS on this SHA; the sole other non-green check is the timed-out review-pr of the review bot itself, not a required check and no PR code. The gate is also not useless as shipped: it does catch a near-full filesystem and inode exhaustion, the #10035 failure it was written for. The objection is only that it cannot cover the ratio-based broker refusal its annotation claims.
中文:在 73904483 上请求修改。阻塞项两条,均在该 head 重新核实:(1)新增元测试对这六个门禁只做“已带门禁的 job 才检查 + 硬编码六个名字”,因此新车道进池却不抄门禁时照绿,且从不断言门禁能失败(continue-on-error: true 在同文件 sdk-java.yml:2479 已有使用)——请改为按各 job 的 runs-on 派生语料、逐个断言 gateIndex 大于 -1、并断言门禁不带 continue-on-error;(2)check-disk-floor.sh 只比绝对可用 KiB、无使用率判断,且该 head 的 sdk-java.yml 未设任何 DISK_FLOOR_* env,六个门禁都跑在 2 GiB 默认值上——在约 952 GiB 的卷上仅占 0.2%,用了 93-94% 的主机照样通过,而 #16003 的 broker 是按比例拒绝(报 CL: 0.94 磁盘已满),这与步骤注释声称覆盖 broker store 矛盾——请按 job 设 DISK_FLOOR_MIN_FREE_KB 并在元测试钉住,或给 broker 车道加使用率判断,或收窄注释与描述;不要抬高共享默认值。其余已核实无阻塞:脚本在 main 与该 head 均存在(4291 字节)、六个门禁都紧跟各自的 checkout、上一轮“门禁落在仅托管 job”的缺陷已消除、.size-baseline 同 PR 内 150332 → 155650、required check Lint & Static 在该 SHA 为 SUCCESS。
…ker claim

Address the two blocking review findings on the Java disk-floor gate:

R1-1: the meta-test skipped any job without the gate and compared a closed
six-name list, so a newly pool-routed lane that forgot the gate stayed green,
and a neutered gate (continue-on-error) kept every assertion true. Derive the
corpus from each job's runs-on (same hazard as the setup-java corpus), require
gateIndex > -1 per pool-capable lane, and assert the gate carries no
continue-on-error. The derived set is the same six jobs today. Verified by
mutation: adding continue-on-error to a gate reddens it, and renaming a gate
(ungated pool job) reddens it with 'expected -1 to be greater than -1'.

R1-2: the step comment claimed RUNNER_TEMP covers the broker store, but the
absolute free-KiB floor cannot express the broker's used-ratio refusal (a
952 GiB volume at 94% used still has ample free bytes). Narrow the comment to
the gate's real scope (near-full filesystem / inode exhaustion, #10035) and
state the broker disk-threshold investigation stays out of scope, matching the
PR description. Bump .size-baseline for the comment change (155650 -> 155888).

sdk-java workflow meta-test 117 passed / 5 skipped; eslint exit 0, prettier
clean; check-workflow-size.sh passes.
cdc2712
|
两个阻塞项已在 R1-1(meta-test 闭环):改为按各 job 的 runs-on 派生 pool 语料(与 setup-java 语料同一防漂移模式),逐个断言 gateIndex > -1,并断言门禁不带 continue-on-error。派生集合今日仍为同 6 个 job。变异验证:给门禁加 continue-on-error → 红;重命名门禁(模拟无门禁 pool job)→ 红('expected -1 to be greater than -1')。 R1-2(收窄 broker 声明):步骤注释不再声称 RUNNER_TEMP 覆盖 broker store;明确门禁实际范围是绝对可用 KiB + inode(近满文件系统/inode 耗尽,#10035),并声明 broker 使用率阈值调查不在本改动范围(与 PR 描述一致)。.size-baseline 同 PR 更新 155650→155888。 验证:sdk-java workflow meta-test 117 通过 / 5 跳过;eslint exit 0、prettier 干净;check-workflow-size.sh 通过。 |
Both blocking findings fixed at current head cdc2712. R1-1: the meta-test now derives the pool corpus from runs-on, asserts gateIndex > -1 per pool-capable lane, and asserts the gate carries no continue-on-error; verified by mutation (continue-on-error reddens it; an ungated pool job reddens it with 'expected -1 to be greater than -1'). R1-2: the step comment no longer claims broker-store coverage; it states the gate's real absolute-free-KiB/inode scope and that the broker used-ratio threshold investigation is out of scope, matching the PR description; .size-baseline bumped 155650->155888. sdk-java meta-test 117 passed/5 skipped, eslint exit 0, prettier clean, check-workflow-size.sh passes.
|
Lint & Static 失败归因:非代码缺陷,是 lint-gate-freshness 检查—— |
qwen-code-review-bot
left a comment
qwen-code-review-bot
left a comment
There was a problem hiding this comment.
Partially reviewed — gaps disclosed. Suggestions are inline.
Not reviewed: build-and-test — the SDK Java (fast) pool lanes that would execute these six gates were skipped in CI at 3724ba9 and no Java lane ran locally, so the gates' runtime behaviour is not observed for this head.
Not fully linted (tool limitation, not a blocker): .github/workflows/sdk-java.yml — actionlint ran workflow-level checks; embedded run: shell deferred (source mapping not yet supported).
中文说明
仅完成部分审查,审查缺口已披露。 建议见行内评论。
未审查(原文为英文):build-and-test — the SDK Java (fast) pool lanes that would execute these six gates were skipped in CI at 3724ba9 and no Java lane ran locally, so the gates' runtime behaviour is not observed for this head.
未完整检查(工具限制,非阻断):.github/workflows/sdk-java.yml——actionlint 已运行 workflow 级检查;内嵌 run: shell 延迟处理(源映射尚未支持)。
— deepseek-v4.1-flash-1017@fda99a87 via Qwen Code /review (v0.26.6)
| const poolJobs = Object.entries(jobs).filter(([, definition]) => | ||
| String(definition['runs-on'] ?? '').includes('self-hosted'), | ||
| ); | ||
| expect(poolJobs.length).toBeGreaterThan(0); |
There was a problem hiding this comment.
[Suggestion] R2-1: The derived corpus still fails open — a lane routed through a runs-on expression drops out of it, and the vacuity-only count keeps the test green.
The rewrite closes the hardcoded-list drift. It leaves the sibling hole: String(definition['runs-on'] ?? '').includes('self-hosted') only matches a job whose runs-on spells self-hosted as text, and this repository already routes a pool lane through a job output — ci.yml:223 sets ubuntu_runner='["self-hosted", "linux", "x64", "ecs-qwen"]', consumed at ci.yml:427 as runs-on: '${{ fromJSON(needs.classify_pr.outputs.ubuntu_runner || ''["ubuntu-latest"]'') }}', whose runs-on text contains no self-hosted. Route one more lane in this workflow that way — the attractive move, since six near-identical 437–463 character ternaries sit under a 4096-byte workflow-size ratchet — and it leaves poolJobs; the remaining five literal matches satisfy expect(poolJobs.length).toBeGreaterThan(0), so the lane can ship ungated with this suite green.
Witness:
baseline, PR tree:                                    Test Files 1 passed (1)   (122 tests)
mutated workflow (job-output runs-on, gate deleted):   Test Files 1 passed (1)   ← ungated pool lane, still green
same, plus expect(poolJobs.length).toBe(6):            AssertionError: expected 5 to be 6
Suggested change: fail closed instead — keep a short explicit hostedOnly allowlist (hosted-harness-mysql, hosted-failover-e2e; both literal ubuntu-latest today), require the gate in every other job, and add expect(gated.size + hostedOnly.size).toBe(Object.keys(jobs).length) so a job matching neither fails. An escape then needs an edit to a list a reviewer sees rather than a rewording of an expression.
Acceptance: set one pool job's runs-on to ${{ vars.POOL_RUNNER }} and delete its gate — green today, must go red via the total-count assertion. The fix must not reintroduce a required hardcoded job list; only the hosted-only exemption list is closed, which is the property :195-197 is asking for.
中文说明
派生语料仍然会漏:通过 runs-on 表达式路由的车道会掉出语料,而只有「非空」的下限断言让测试保持绿色。
这次重写关掉了硬编码列表的漂移,但留下了同类的另一个口子:String(definition['runs-on'] ?? '').includes('self-hosted') 只匹配 runs-on 文本里写出 self-hosted 的 job,而本仓库已经在用 job 输出路由池车道(ci.yml:223 定义 ubuntu_runner,ci.yml:427 用 fromJSON 消费),那种 runs-on 文本里没有 self-hosted。把本 workflow 里再一个车道改成这种写法——在 4096 字节 workflow 体积配额下,六个 437–463 字符的近似三元表达式正是最诱人的合并对象——它就会掉出 poolJobs;剩下的五个字面匹配仍满足 expect(poolJobs.length).toBeGreaterThan(0),于是该车道可以不带门禁上线而本测试照样绿。
证据:基线绿;把 test 的 runs-on 改成 job 输出形式并删掉它的门禁后仍然绿;再加上 expect(poolJobs.length).toBe(6) 才变红(expected 5 to be 6)。
建议:改成失败关闭——保留一个短的显式 hostedOnly 白名单(今天的 hosted-harness-mysql、hosted-failover-e2e 都是字面量 ubuntu-latest),要求其余每个 job 都带门禁,并加 expect(gated.size + hostedOnly.size).toBe(Object.keys(jobs).length),这样两头都不匹配的 job 也会失败。绕过它就得改一张审查者看得见的清单,而不是改写一个表达式。
验收:把某个池 job 的 runs-on 改成 ${{ vars.POOL_RUNNER }} 并删掉门禁——现在绿,改后必须因总数断言变红。修复不能重新引入「必须」的硬编码 job 列表,只允许关闭的托管豁免名单。
— deepseek-v4.1-flash-1017@fda99a87 via Qwen Code /review (v0.26.6)
There was a problem hiding this comment.
Closed in 18ec17a by failing closed, as suggested. The corpus no longer derives from runs-on text: an explicit hostedOnly set (hosted-harness-mysql, hosted-failover-e2e) is exempted, every other job must carry the gate, and gated.size + hostedOnly.size === Object.keys(jobs).length fails a job that matches neither list. A lane routed through ${{ vars.POOL_RUNNER }} or a job output therefore cannot leave the corpus silently; an escape needs an edit to the visible allowlist.
Verified the acceptance shape: with hosted-harness-mysql given a gate, and separately with a gate deleted from daemon-e2e, the suite goes red (1 failed), and green on the restored tree (117 passed, 5 skipped).
| for (const [name, definition] of poolJobs) { | ||
| const steps = definition.steps ?? []; |
There was a problem hiding this comment.
[Suggestion] R2-2: Nothing asserts that a hosted-only job carries no gate, although the description says the test prevents exactly that.
Every assertion lives inside this poolJobs loop, so a job outside the corpus is never visited. The description advertises that the meta-test "prevents it from being added silently to hosted-only jobs" — there is no assertion behind that sentence, and the set-equality check that caught the round-1 blocker (hosted-harness-mysql gated, mysql-integration not) was removed by this rewrite. Insert the three-line gate after Checkout in hosted-harness-mysql (sdk-java.yml:1133, runs-on: 'ubuntu-latest') or hosted-failover-e2e (:1445), or move a future lane off the pool while keeping its steps: on a hosted runner runner.environment is github-hosted, the step's if: is permanently false and the step is inert, and this suite stays green.
Witness:
mutated workflow (gate added to hosted-harness-mysql — 7 gates in file):   Test Files 1 passed (1)
with a negative loop over the non-pool jobs:                              AssertionError: hosted-harness-mysql: expected true to be false
Suggested change, beside the pool loop:
for (const [name, definition] of Object.entries(jobs)) {
  if (poolJobs.some(([poolName]) => poolName === name)) continue;
  expect(
    (definition.steps ?? []).some(
      (candidate) => candidate.name === 'Disk floor gate (self-hosted)',
    ),
    name,
  ).toBe(false);
}
Acceptance: inserting the gate into hosted-harness-mysql must red and name that job; without the new loop it stays green. Note the assertion has to key on runs-on — a hosted lane genuinely wanting the check would need a different if: first, since runner.environment == 'self-hosted' (sdk-java.yml:193) is permanently false there.
中文说明
没有任何断言保证「仅托管」的 job 不带门禁,而 PR 描述恰恰声称这个测试能防住这一点。
所有断言都在这条 poolJobs 循环里,语料之外的 job 根本不会被访问。描述里写的「防止它被悄悄加到仅托管 runner 的 job 上」目前背后没有断言,而抓住上一轮阻塞项(hosted-harness-mysql 有门禁、mysql-integration 没有)的集合相等断言已被这次重写删掉。把三行门禁插到 hosted-harness-mysql(sdk-java.yml:1133,runs-on: 'ubuntu-latest')或 hosted-failover-e2e(:1445)的 Checkout 之后,或把将来某个车道移出池却保留步骤:托管 runner 上 runner.environment 是 github-hosted,该步骤的 if: 永远为假、完全无效,而本测试仍然绿。
证据:把门禁加进 hosted-harness-mysql(文件里 7 处门禁)后测试仍绿;补上遍历非池 job 的否断言后报 hosted-harness-mysql: expected true to be false。
验收:把门禁插进 hosted-harness-mysql 后测试必须变红并点名该 job;没有新增的这段循环则保持绿。断言必须按 runs-on 判断——真想在托管车道做检查的话,得先换一个 if:,因为在托管 runner 上 runner.environment == 'self-hosted' 永远为假。
— deepseek-v4.1-flash-1017@fda99a87 via Qwen Code /review (v0.26.6)
There was a problem hiding this comment.
Closed in 18ec17a. The hosted-only jobs are now asserted in the negative loop: the gate step index must be -1 for hosted-harness-mysql and hosted-failover-e2e, with the comment that runner.environment is github-hosted there, so a gate would read as protection without being any. Adding one takes the suite red (verified).
Review round on this PR found the gate could not fire in the two shapes it
exists for, and that the meta-test could go green through the same drift it
was added to prevent.

R1-2: every lane ran the shared 2 GiB / 100k-inode default. The #16003
incident was a used-ratio refusal — the broker reported 0.94 while the
952 GiB volume still had tens of GiB free — so no absolute floor can express
that threshold, and 2 GiB is below what these lanes write: a host with 4 GiB
free passed the gate and then died mid-suite. Give the five heavy lanes the
repo's build-sized 8 GiB floor, leave flyway-migrations and the shared value
alone, and add an opt-in DISK_FLOOR_MAX_USED_PCT arm to check-disk-floor.sh
for the two broker lanes (90%).

R2-1/R2-2: the corpus came from `runs-on` text and skipped jobs outside it,
so a lane routed through an expression or a job output shipped ungated while
the suite stayed green, and nothing asserted the hosted-only jobs carry no
gate. Fail closed: an explicit hosted-only allowlist, a gate required for
every other job, a total-count assertion, and a negative assertion on those
two jobs. Pin the per-lane floors so dropping one is a test failure.

Verified: sdk-java-workflow suite 117 passed, 5 skipped; it goes red when a
gate is deleted, when one is added to a hosted job, and when a floor is
removed. check-disk-floor suite 12 passed, including four new ratio cases.
|
本地验证(head
不适用项:只改 CI workflow、shell 门禁脚本与其 meta-test,无 UI/TUI 渲染变化,因此没有截图。 |
qwen-code-review-bot
left a comment
qwen-code-review-bot
left a comment
There was a problem hiding this comment.
Approving at 18ec17a0. The three open threads are bot Suggestion threads whose replies say "Closed in 18ec17a" — I checked each claim against the head instead of taking the reply at face value, and all three hold.
R1-2 — per-lane calibration plus the ratio arm
sdk-java.ymlnow carriesDISK_FLOOR_MIN_FREE_KB: '8388608'ontest(:73),mysql-integration(:681),event-transport-broker(:1693),event-transport-multi-node(:1977) anddaemon-e2e(:2361), whileflyway-migrations(:532) keeps the shared 2 GiB — the split the reply describes, and the shared default itself is untouched.- The ratio half is real, not deferred:
check-disk-floor.shreadsDISK_FLOOR_MAX_USED_PCT(:38), validates it as a percent (:66), printsused_pct/max_used_pctin the DISKFLOOR sample (:107) and fails at or above the ceiling (:118-119). That is the arm the original gate could not express, since it only compared absolute free KiB.
R2-1 — the corpus fails closed instead of deriving from runs-on text
scripts/tests/sdk-java-workflow.test.js:199 declares hostedOnly = new Set(['hosted-harness-mysql', 'hosted-failover-e2e']), every other job must show gateIndex > -1 (:213), and gated.size + hostedOnly.size === Object.keys(jobs).length (:228) fails any job that lands in neither list. A lane routed through a runs-on expression can no longer drop out of the corpus silently — that was the fail-open shape the thread named.
R2-2 — hosted-only jobs are asserted in the negative
:207-210 asserts gateIndex === -1 for each hosted-only job, so the description's "prevents a gate from being added silently to hosted-only jobs" now has an assertion behind it. The surrounding pins are tighter than before as well: the gate step must be preceded by actions/checkout (:214), its if (:215) and run (:218) are pinned, and continue-on-error must be absent (:223).
Not verified: I did not execute scripts/tests/sdk-java-workflow.test.js or the shell suite; the reading above is source-level. CI at this head was not re-read for this line item, so I am not claiming a green rollup.
qqqys
left a comment
qqqys
left a comment
There was a problem hiding this comment.
APPROVE — Critical-only review at head 18ec17a
No provable Critical. CI-infrastructure change: five files, one shell script, one workflow, one baseline entry and two test files.
My approval on this PR's earlier head was dismissed and the branch has moved, so this is a full re-review rather than a delta read.
What it does
check-disk-floor.sh gains an opt-in third ceiling, DISK_FLOOR_MAX_USED_PCT, alongside the existing absolute free-kilobyte and free-inode floors. The stated reason is concrete: the RocketMQ broker refuses writes on its own used-ratio rule — 0.94 for CL/CQ/INDEX in the #16003 incident — while the volume still reports tens of GiB free, so an absolute-free-bytes floor cannot express that threshold. sdk-java.yml then installs a Disk floor gate (self-hosted) step ahead of the heavy work in six lanes, raising DISK_FLOOR_MIN_FREE_KB to 8 GiB and adding DISK_FLOOR_MAX_USED_PCT: '90' on the broker lanes.
What I checked
The new check fails in the right direction. It sets status=1, which is what already fails the job before the heavy step, and it is guarded by [ -n "$MAX_USED_PCT" ] && [ -n "$used_pct" ] so an unset ceiling or an unreadable df leaves the absolute floors in charge rather than silently widening the gate. used_pct comes from df -kP column 5 with the % stripped and then passes the same non-numeric sanitising case the existing fields use, so a malformed df line cannot reach the arithmetic comparison. validate_percent_override rejects anything outside 1–100 with ::error:: and exit 1, and empty stays disabled, which keeps the opt-in semantics honest. The comparison uses -ge, and since POSIX df rounds its used percentage up, that is the conservative side.
The ceilings are per-job, not global. DISK_FLOOR_MAX_USED_PCT is set only in the broker lanes' env, so one lane's calibration cannot move another lane's gate — the property the script's own comment claims.
The gates run and pass. Every SDK Java lane is green at this head, both the fast tier and the full tier, including the two RocketMQ 5.5.1 broker gates and the MySQL 8.4 multi-node gate. That is direct evidence the new steps do not spuriously breach on the shared pool, which is the main way a change like this could break CI. The ledger items about gates running at the shared 2 GiB default were filed at superseded heads and the 8 GiB override at this head answers them.
One bookkeeping note, non-blocking
.size-baseline records 155888 for sdk-java.yml, but the blob at this head is 157348 bytes — the entry is 1460 bytes short of the file it describes. This does not fail anything: check-workflow-size.sh compares wc -c against base + GROWTH_ALLOWANCE with an allowance of 4096, so 1460 passes. The consequence is only that this PR quietly consumes 1460 bytes of the headroom the ratchet is meant to leave for the next one, and a later PR growing the same file will hit the error 1460 bytes sooner than the recorded number suggests. Worth correcting to 157348 while the branch is open, since the ratchet's whole point is that the recorded number is the real one.
For completeness: the same comparison against this PR's base shows sdk-java.yml at 154074 bytes against a recorded 150332, so a shortfall of this kind already exists on main. The script treats that case as a warning rather than an error precisely because the file is unchanged from the PR's base — which is why it is not red here either.
CI
Everything relevant is green, including Lint & Static, Test (ubuntu-latest, Node 22.x), Managed Agent fast tier, Integration Tests (no-AK) and all fourteen SDK Java lanes. The single failure is web-shell E2E Smoke (ubuntu-latest, Node 22.x). This PR changes no TypeScript source and no web-shell file — its five files are a CI shell script, its test, a workflow, a baseline entry and a workflow meta-test — so there is no mechanism by which it reaches that lane, and I am not treating it as attributable.
For the record on review state: reviewDecision is null, no CHANGES_REQUESTED stands at this head, and the bot's review here is an approval.
|
Same-head CI update on
Everything else on this head is fine (2 approvals bound to |
|
Two checks are red on
Everything else on this head looks fine: required |

|
|
|
Released in v0.26.8. |


What this PR does
Adds the existing disk-floor preflight to all six Java lanes that can be routed to the shared ECS pool, immediately after checkout and before Maven, container, broker, or Node setup. The preflight checks both the workspace and the runner temp filesystem, so a saturated host fails with a disk diagnostic before JUnit or the RocketMQ broker turns ENOSPC into misleading test errors.
It also adds a workflow meta-test that pins the gate to those six pool jobs, requires it immediately after checkout, and prevents it from being added silently to hosted-only jobs.
Why it's needed
The Java lanes currently have no reference to the existing disk-floor gate, even though the cited failures all ran on the shared ECS pool. In the affected runs, the broker reported its disk as full and JUnit could not create temporary directories; both surfaced as test failures rather than infrastructure failures. Failing before the heavy steps makes the first failure actionable and leaves the suite unstarted on a runner that cannot provide the required headroom.
Reviewer Test Plan
How to verify
Review the six Java pool lanes and confirm that each one checks disk space immediately after checkout and before any setup or suite step. The gate should be conditional on
runner.environment == 'self-hosted', and hosted-only lanes should remain unchanged. A saturated self-hosted runner should fail with the existingDisk floor breacheddiagnostic naming the runner, directory, filesystem, free KiB and floor; a runner above the configured floor should proceed normally.Evidence (Before & After)
N/A for UI. Before: the Java lanes had no disk-floor gate. After: every Java lane that can select the ECS pool has the same preflight used by the other self-hosted workflows.
Tested on
On Linux, against the current head:
vitest run scripts/tests/sdk-java-workflow.test.js scripts/tests/hosted-process-ci.test.js→ 211 passed / 211 (122 and 89 respectively), andprettier --check .github/workflows/sdk-java.yml scripts/tests/sdk-java-workflow.test.js→ clean. No Java lane was executed locally; the gate's own behaviour was not re-measured here, and CI on this head is reported separately rather than assumed green.Environment (optional)
N/A; this changes CI workflow wiring only.
Risk & Scope
Linked Issues
References #16003. This PR closes the Java-lane diagnostic gap; it does not claim to resolve the underlying runner reclaim or broker-threshold investigation.
中文说明
这个 PR 做了什么
把现有的磁盘空间下限预检接入所有六个可能路由到共享 ECS 池的 Java 车道,位置紧跟在 checkout 之后、Maven、容器、broker 或 Node 初始化之前。预检同时检查 workspace 与 runner 临时目录所在的文件系统,因此当主机磁盘接近耗尽时,会在 JUnit 或 RocketMQ broker 把 ENOSPC 变成误导性的测试错误之前,先给出磁盘诊断并失败。
同时增加一个 workflow 元测试,把这套门禁钉在上述六个池 job 上,要求它必须紧跟在 checkout 之后,并防止它被悄悄加到仅托管 runner 的 job 上。
为什么需要它
这些 Java 车道目前完全没有引用已有的磁盘下限门禁,而 issue 中列出的失败全部发生在共享 ECS 池上。受影响的运行里,broker 报告磁盘已满,JUnit 也无法创建临时目录;两者最终都表现为测试失败,而不是基础设施失败。在重步骤之前失败,可以让第一次失败就可行动,并避免在不具备足够余量的 runner 上启动整套测试。
评审者的测试计划
如何验证
检查六个 Java 池车道,确认每个都在 checkout 之后、任何初始化或测试步骤之前检查磁盘空间。门禁应只在
runner.environment == 'self-hosted'时运行,仅托管 runner 的车道应保持不变。磁盘低于下限的自托管 runner 应以现有的Disk floor breached诊断失败,并在诊断中点名 runner、目录、文件系统、可用 KiB 与下限;高于配置下限的 runner 应正常继续。证据(修改前与修改后)
UI 部分不适用。修改前:Java 车道没有磁盘下限门禁。修改后:每个可能选择 ECS 池的 Java 车道都接入了其他自托管 workflow 使用的同一套预检。
验证平台
在 Linux 上针对当前 head:
vitest run scripts/tests/sdk-java-workflow.test.js scripts/tests/hosted-process-ci.test.js→ 211 passed / 211(分别为 122 与 89),prettier --check .github/workflows/sdk-java.yml scripts/tests/sdk-java-workflow.test.js→ 通过。没有在本地执行任何 Java 车道,也没有重新测量门禁脚本本身的行为;本 head 的 CI 结论单独回报,不假定为绿。环境(可选)
不适用;本改动只涉及 CI workflow 接线。
风险与范围
关联 Issue
引用 #16003。本 PR 解决 Java 车道的诊断缺口;它不声称已经解决底层 runner 回收或 broker 阈值调查。
Review round 2 (18ec17a)
DISK_FLOOR_MIN_FREE_KB: 8388608);flyway-migrationsand the shared default stay as they were.check-disk-floor.shgains an opt-in used-percent ceiling (DISK_FLOOR_MAX_USED_PCT), because the CI runners run out of disk: the RocketMQ broker refuses writes and Java lanes cannot create temp directories #16003 refusal is a ratio: the broker reported 0.94 on a 952 GiB volume with tens of GiB free. Both broker lanes set it to 90.sdk-java-workflow117 passed / 5 skipped;check-disk-floor12 passed; the meta-test goes red when a gate is deleted, added to a hosted job, or a floor is removed.